Desktop AI App Development Cost Guide: Budgeting On-Device LLMs via Electron in 2026

What This Guide Covers

Who this is for: CTOs, product managers, and founders at SaaS and software companies planning a desktop app with local AI features, or adding on-device inference to an existing Electron product for desktop ai app development cost.

Search intent: Understand desktop AI app development cost, including on-device LLM integration cost, hardware requirements, and when local inference beats a cloud API.

What you will walk away with: USD cost ranges from MVP to enterprise, a cloud vs on-device vs hybrid comparison, RAM and VRAM guidance by model size, and a list of budget-blowing mistakes to avoid.

Introduction
desktop ai app development cost

The global edge AI market was valued at $24.9 billion in 2025 and is projected to reach $118.7 billion by 2033, growing at a 21.7% CAGR from 2026 to 2033, according to Grand View Research. Some of that growth is landing on ordinary laptops and desktops, where product teams now run language models locally instead of sending every request to a remote cloud API and paying for each token.

That fundamentally changes how desktop AI app development cost gets calculated. A cloud integration asked two questions: how many engineering hours, and how many tokens. An on-device LLM adds a third: what hardware does every user need to run it? RAM, VRAM, model size, and quantization level now shape both the engineering scope and who can actually install and use the product. This guide breaks down the engineering, hardware, and ongoing costs of shipping an on-device LLM through Electron in 2026, starting with why hardware now belongs in the project budget at all.

Why Desktop AI App Development Cost Now Includes Hardware, Not Just Engineering
desktop ai app development cost

The Old Cost Model: Cloud API Calls and Dev Hours

Until recently, adding AI to a desktop app meant calling a cloud API. The budget had two lines: engineering hours to build the integration, and per-token usage fees that scaled with active users. Hardware barely mattered, because any machine that could run the app could send a prompt to OpenAI or Anthropic. Electron app development pricing looked much like any other desktop project, with AI as one feature among many. Finance could forecast costs by multiplying expected users by average tokens per session, then adding a margin for growth. That model still works well for many products today.

The New Cost Model: Local Compute, Memory, and Model Size

On-device LLM inference flips that model. Per-token fees disappear, but three new cost drivers appear: the compute and memory each user’s machine needs, the size of the model you ship, and the engineering required to run it reliably across Windows, macOS, and Linux. On-device LLM integration cost is mostly paid upfront, in engineering and testing, rather than monthly in API bills.

The trade-off is not static. Epoch AI found that LLM inference prices have fallen between 9x and 900x per year, depending on the performance milestone, which keeps making cloud APIs cheaper. Local inference therefore has to justify itself on more than price: offline access, data privacy, low latency, and predictable costs at scale.

For budgeting, the practical change is that hardware requirements for local AI become a product decision. Every gigabyte of RAM your model needs narrows the audience that can run your app, which affects revenue as much as cost.

Cloud LLM APIs vs On-Device Inference: Where the Real Costs Sit

When Cloud API Costs Win at Small Scale

For an early-stage product, cloud APIs are almost always cheaper. There is no model packaging, no hardware detection, and no cross-platform inference testing, so an MVP can ship in weeks. Costs scale with usage, so a product with a few hundred active users may spend less per month on tokens than a single day of engineering time. Cloud models are also more capable than anything a typical laptop can run. For SaaS startups still validating demand, that speed and capability usually matter more than long-term unit costs. The catch is that the bill grows with every new user.

When On-Device Inference Wins at Scale or for Offline Use

On-device inference starts to win when usage is high, steady, and repetitive. Once the model ships with the app, each additional query costs you nothing, because the user’s hardware does the work. For a product with tens of thousands of daily active users running frequent tasks like summarization, classification, or autocomplete, that can remove a large and growing API bill. Local inference also wins wherever cloud calls are not allowed or not practical: regulated industries with strict data rules, air-gapped environments, field teams with poor connectivity, and privacy-conscious users who do not want their data leaving the device.

Hybrid Architectures That Split the Difference

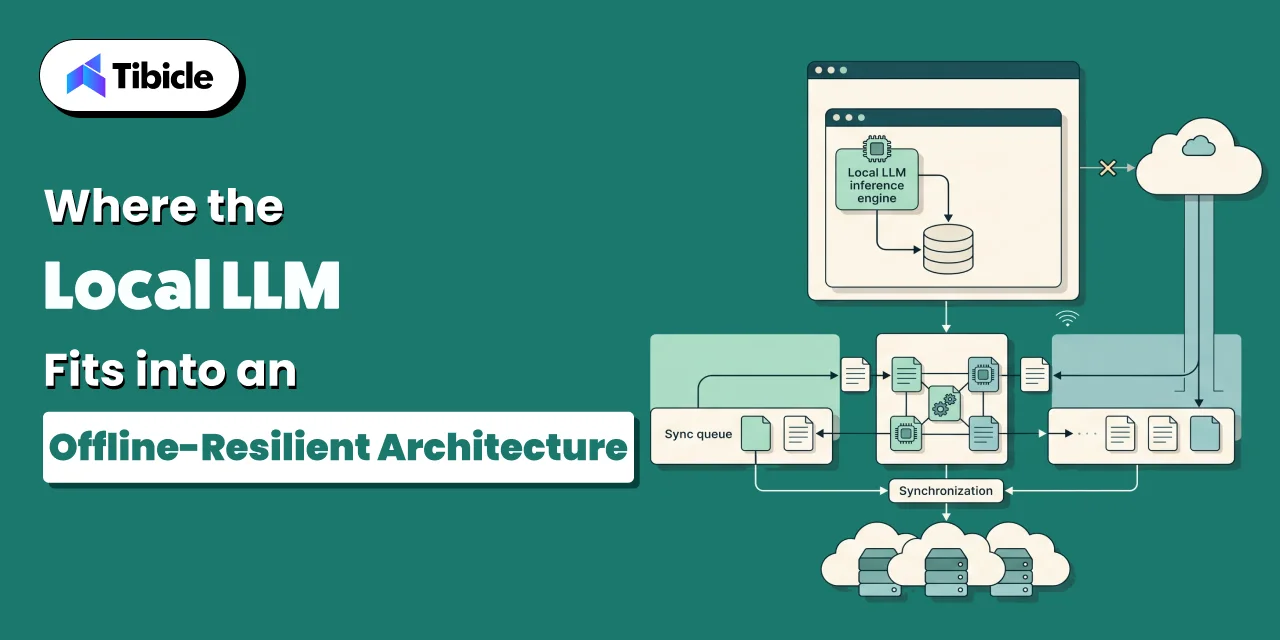
Most products end up with a hybrid cloud and local AI architecture. A small quantized model runs on-device for fast, frequent, or private tasks, such as autocomplete, classification, redaction, or offline drafts. Complex requests, such as long document analysis or multi-step reasoning, route to a cloud model through a standard AI integration when a connection and user permission are available. A router decides based on task type, device capability, connectivity, and data sensitivity. The added cost is the routing logic and testing both paths, but it lowers cloud spend, supports weaker hardware, and keeps the product working offline.

The table below compares the three inference architectures on cost driver and best fit.

Architecture Primary Cost Driver Best Fit
Cloud API only Per-token usage cost, scales with active users Low-volume apps or fast-moving MVPs
Pure on-device One-time engineering cost plus user hardware requirements Offline, regulated, or high-volume desktop apps
Hybrid Engineering cost for routing logic plus reduced cloud usage Apps that need both offline basics and cloud-grade complex tasks

Hardware Budgeting for On-Device LLMs in an Electron App
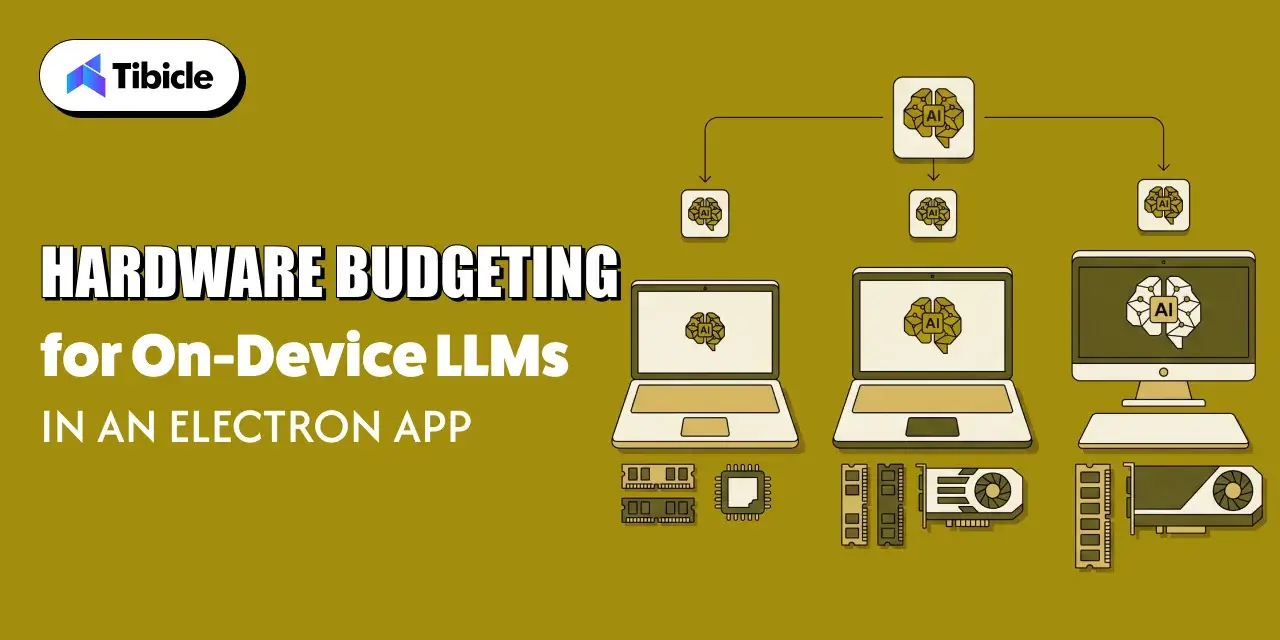
desktop ai app development cost

Minimum RAM and VRAM Requirements by Model Size

VRAM and RAM budgeting starts with a simple rule: a model’s memory footprint is roughly its parameter count multiplied by bits per weight, plus working memory for context. At a common 4-bit quantization, a 3B parameter model needs about 2GB, a 7B to 8B model about 4GB to 5GB, and a 13B to 14B model about 8GB to 9GB, before context. Add the Electron app, the operating system, and everything else the user has open, and a 7B model realistically needs a 16GB machine. GPU vs CPU inference cost matters too: CPU inference runs almost anywhere but slowly, while GPU inference is faster but needs matching VRAM.

Why Memory Prices Are Reshaping Minimum Spec Decisions in 2026

Minimum spec depends on what your users can afford to buy. In February 2026, TrendForce raised its forecast for first-quarter conventional DRAM contract prices to a 90% to 95% quarter-over-quarter increase, up from 55% to 60%, and projected PC DRAM prices to rise more than 100%, driven by AI and data center demand. When memory gets that much more expensive, laptop makers and IT departments have strong reasons to hold RAM configurations flat and delay upgrades. If your app needs a 16GB machine for its local model, a meaningful share of target users may not qualify. Revisit minimum spec close to launch.

Budgeting for Dev and QA Hardware Across Model Tiers

Your team needs the hardware your users have, not just the fastest machines in the office. A realistic QA lab covers each supported tier: a low-end Windows laptop with 8GB of RAM and integrated graphics, a mid-range Windows machine with an 8GB NVIDIA GPU, an Apple Silicon Mac with 16GB of unified memory, and a Linux machine if you support it. As an indicative figure, expect $8,000 to $20,000 for a small physical test lab, or use cloud-hosted Windows, Mac, and GPU instances for burst testing. Developer workstations also need enough memory to run several model variants side by side.

Model Selection and Quantization: The Biggest Lever on desktop ai app development cost

Quantization Levels and What They Cost You in desktop ai app development cost

Model quantization for desktop apps compresses a model’s weights from 16-bit precision down to 8, 5, 4, or even fewer bits. Each step cuts memory and speeds up inference, at some cost to output quality. The surprise is how well larger compressed models hold up. A Systematic Evaluation of On-Device LLMs found that heavily quantized larger models consistently outperform smaller high-precision models, with a threshold around 3.5 effective bits per weight. In budget terms, a 4-bit 8B model is often a better buy than a 16-bit 3B model using similar memory, and that advantage fades below the threshold.

Picking a Model Size That Matches Your User’s Actual Hardware and desktop ai app development cost

The right model is the largest one your minimum-spec user can run comfortably, not the one that looked best on a developer’s workstation. Start with real device data: telemetry from an existing app, customer IT standards, or surveys of your target segment. Then define two or three tiers, such as a 1B to 3B model for 8GB machines, a 7B to 8B model for 16GB machines, and optional GPU acceleration above that. Detect hardware at install or first launch and download the matching model. This keeps the app usable on older machines while rewarding users with better hardware.

GGUF, llama.cpp, and Other Runtime Choices That Affect desktop ai app development cost

The runtime you choose shapes engineering cost as much as the model does. The GGUF model format, used by llama.cpp, packs weights and metadata into a single file built for fast loading, with a wide range of quantization levels. For llama.cpp Electron integration, libraries such as node-llama-cpp provide Node.js bindings with prebuilt binaries for CPU, CUDA, Metal, and Vulkan backends. Alternatives include ONNX Runtime, which suits smaller task-specific models, or wrapping an external engine like Ollama. Choosing a mature, well-maintained runtime avoids months of custom native code. Runtime maturity also decides how much on-device LLM integration cost shifts into maintenance later.

Electron-Specific Engineering Costs for On-Device LLM Integration
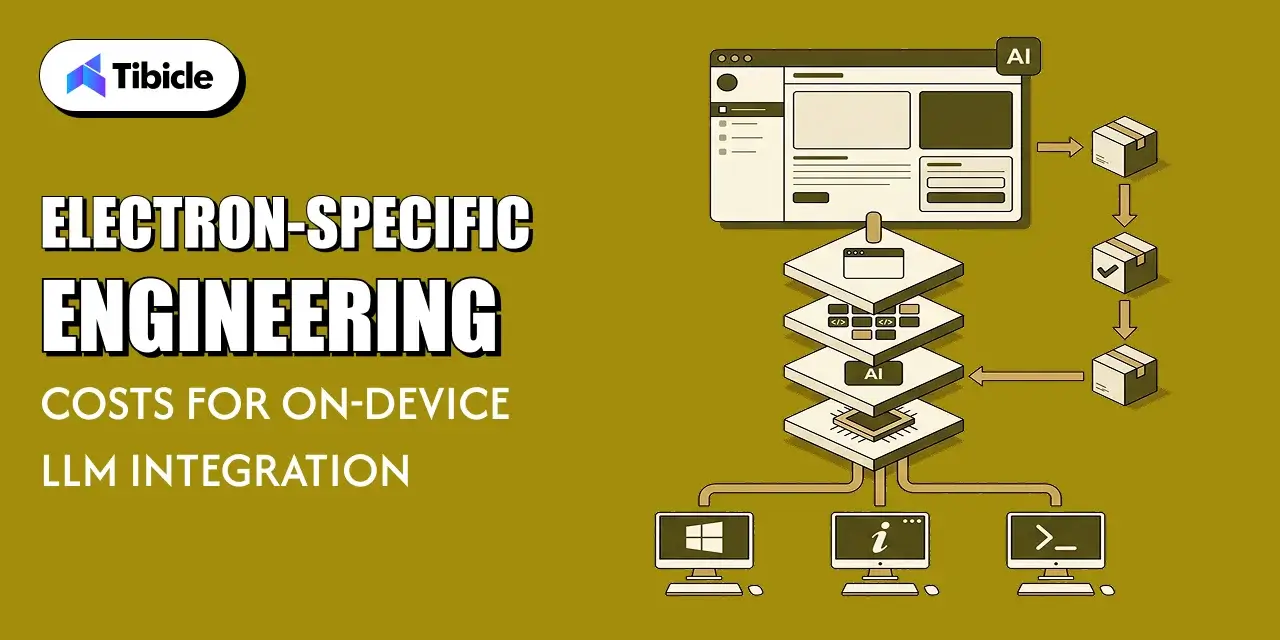
wrapping

Bundling or Downloading Models: Packaging Cost Trade-offs

A 4GB model changes how you ship software. Bundling it inside the installer keeps first launch simple and works offline, but it creates multi-gigabyte downloads, slows every app update, and can run into size limits in some app stores and enterprise deployment tools. Downloading the model on first launch keeps the installer small and lets you pick the right model for each machine, but it requires a resumable downloader, checksum verification, disk space checks, and CDN hosting. Most products download models separately and store them outside the app bundle, so app and model updates can ship on independent schedules.

Native Module Integration for Local Inference Engines

Inference engines are native code, and native code is where Electron projects lose unplanned hours. Bindings must match your Electron version, run in the main process or a utility process rather than the renderer, and stay outside the asar archive so binaries load correctly. Each platform and GPU backend needs its own build and test pass. That work is billed at normal engineering rates: Clutch’s Software Development Company Pricing Guide reports that most software development companies charge $24 to $49 per hour, with an average project cost of about $132,480. Native integration alone can consume several weeks of that budget.

Auto-Update and Model Distribution Across Windows, macOS, and Linux

Auto-update model distribution adds its own line item. Electron’s built-in autoUpdater supports macOS and Windows but not Linux, so Linux builds need a separate path, such as AppImage updates or package repositories. macOS builds must be code-signed and notarized, and Windows builds need code signing to avoid SmartScreen warnings. Models need their own versioned manifest, staged downloads, and rollback if a new model underperforms. Budget for update hosting and CDN bandwidth, which climbs quickly when every model update means a multi-gigabyte download across your whole user base. Signing and update pipelines often take a dedicated sprint to get right across all three platforms.

Building a Realistic Budget: What a Desktop AI App Actually Costs

Cost Ranges by Project Complexity (MVP to Enterprise)

Putting the pieces together, desktop AI app development cost typically falls into three bands. These are indicative ranges based on common project scopes:

  • MVP on one platform with one local model and basic chat or summarization: $25,000 to $60,000
  • Production app across Windows and macOS with hardware tiers, hybrid fallback, and auto-update: $60,000 to $150,000
  • Enterprise app adding Linux, local document search, admin controls, and managed deployment: $150,000 to $350,000+

Model licensing cost is usually low, since many open-weight models allow commercial use, but some carry conditions your legal team should review.

Ongoing Costs: Model Updates, Support, and Hardware Support Matrix 

Launch is where desktop AI app development cost shifts, not where it ends. New open-weight models arrive every few months, and each upgrade means re-quantizing, benchmarking on every hardware tier, and redistributing multi-gigabyte files. Electron and runtime updates bring security patches and occasional breaking changes to native modules. Support costs grow with your hardware support matrix, because every supported GPU, operating system version, and memory tier generates its own bug reports. A practical total cost of ownership AI desktop app estimate sets aside 15% to 25% of the initial build per year for maintenance, plus CDN bandwidth and any cloud usage from hybrid routing.

Common Budget-Blowing Mistakes in On-Device LLM Projects for desktop ai app development cost

Most on-device LLM budgets are not blown by one large surprise. They leak through a handful of decisions made too early or skipped entirely. A model that ran well on a developer’s machine fails on customer laptops. A quantization choice made in week two never gets revisited. The first model update ships without a distribution plan. Users with weaker hardware get error messages instead of a fallback. Each of these turns into rework, support tickets, or refunds after launch, when fixes cost the most. Watch for these four in particular:

  • Scoping the model against a demo machine instead of the customer’s actual minimum spec
  • Treating quantization as a one-time decision instead of testing multiple levels against real hardware
  • Underbudgeting for model update and redistribution costs after the first release
  • Skipping a hybrid fallback path, which turns a hardware gap into a support ticket instead of a graceful degradation

How Tibicle Budgets and Builds On-Device LLM Desktop Apps
wrapping

Cost and Architecture Assessment Before Any Code for desktop ai app development cost

Every Tibicle desktop AI engagement starts with numbers, not code. Our technology consulting team maps your target users’ hardware, expected usage volume, data sensitivity, and offline requirements, then models the cost of cloud-only, on-device, and hybrid architectures side by side. We benchmark candidate models and quantization levels on real minimum-spec machines, so the recommendation reflects what your customers actually own. If the numbers favor a cloud API, we say so. You get a minimum spec, a model tier plan, a build estimate, and a projected three-year total cost of ownership before committing to development, which makes budget conversations with finance far easier.

Implementation With Quantized Models and Native Integration for desktop ai app development cost

Our desktop app development team builds the Electron application with inference isolated from the UI, using mature runtimes like llama.cpp through Node.js bindings rather than custom native code. We ship quantized models in GGUF or ONNX formats matched to each hardware tier, with hardware detection, resumable model downloads, code signing, and a hybrid fallback to a cloud model where your data policies allow it. Every build is tested on the QA hardware matrix agreed during assessment, not just on developer workstations. Our guide to running local LLMs in Electron goes deeper into the technical architecture behind these builds.

Ongoing Support and Model Update Management for desktop ai app development cost

After launch, Tibicle manages the model lifecycle alongside the app. We track new open-weight releases, re-quantize and benchmark promising candidates on your hardware tiers, and ship model updates through a versioned, staged distribution process with rollback. Electron and runtime upgrades are tested on every supported platform before release. Annual maintenance contracts keep these costs predictable, while 24/7 monitoring and support covers production issues. Quarterly reviews compare model quality, hardware reach, and cost against the original plan. Teams that prefer to own development in-house can add Tibicle engineers through dedicated tech resource allocation. You can see examples of our work in our project portfolio.

Key Takeaways for Teams Budgeting a Desktop AI App

  • Desktop AI app development cost splits into engineering cost and user hardware cost once inference moves on-device, and both need a budget line.
  • Quantization level is the single biggest lever on both hardware requirements and output quality, not a late-stage tuning detail.
  • Memory prices are moving fast enough in 2026 that minimum spec decisions need revisiting closer to launch, not locked in at kickoff.
  • A hybrid cloud-plus-local architecture is often cheaper to build and support than forcing every task through an on-device model.
  • Model updates, redistribution, and QA hardware are recurring costs, so plan for them from day one rather than after the first release.
  • Budget against your users’ real minimum spec, not a developer workstation.

Budgeting a desktop AI app with on-device LLMs? Book a 30-minute call with Tibicle.

Frequently Asked Questions

What does desktop AI app development cost typically range from for an MVP versus a full product?
An MVP with one platform and one local model typically costs $25,000 to $60,000. A production app across Windows and macOS with hardware tiers, hybrid fallback, and auto-update runs $60,000 to $150,000. Enterprise builds with Linux support, admin controls, and managed deployment often exceed $150,000. The biggest variables are platform count and hardware tiers.

Is it cheaper to run an LLM on-device or call a cloud API from an Electron app?
At low volume, cloud APIs are usually cheaper because there is no model packaging or hardware testing. At high, steady volume, on-device inference often wins because each extra query costs you nothing. Many teams use a hybrid, running frequent simple tasks locally and routing complex ones to the cloud.

How much RAM or VRAM does a desktop app need to support a local LLM?
At 4-bit quantization, a 3B model needs about 2GB and a 7B to 8B model about 4GB to 5GB, plus memory for context. In practice, plan small models for 8GB machines and 7B to 8B models for 16GB machines. GPU acceleration needs enough VRAM to hold the model.

Does model quantization actually save money, or just reduce quality?
It saves money by lowering hardware requirements, widening your addressable audience, and shrinking download sizes. Quality loss stays modest down to around 4 bits per weight, and research shows larger quantized models often beat smaller full-precision ones. Test several levels on real hardware before choosing.

What ongoing costs come with shipping a desktop app with an on-device model?
Expect model updates and re-quantization, benchmarking across hardware tiers, CDN bandwidth for multi-gigabyte downloads, Electron and runtime upgrades, and support across your hardware matrix. A common planning figure is 15% to 25% of the initial build cost per year. Hybrid apps also carry some ongoing cloud API usage.

Does Tibicle build and budget on-device LLM desktop applications with Electron?
Yes. Tibicle assesses your users’ hardware, models cloud, local, and hybrid costs, then builds Electron apps with quantized models, native inference integration, and ongoing model update management. Every engagement starts with a cost and architecture assessment. Contact our team to scope your project and get a realistic budget.
 

Offline Local LLM Desktop App Integration in Electron

What This Guide Covers

Who this is for

This guide is intended for engineering leads, staff engineers, and technical founders building or maintaining Electron-based desktop applications that must function without a constant connection, particularly teams undertaking offline local LLM desktop app integration to add on-device inference. It is also relevant to product managers scoping offline capability and evaluating build-versus-outsource decisions for sync infrastructure, since offline local llm desktop app integration carries implications for both engineering architecture and resourcing.

Search intent

Informational with commercial undertone. The searcher is past “what is offline-first” and is looking for how to actually architect sync, conflict resolution, and local LLM fallback in a real Electron app, likely while scoping a build or evaluating whether to bring in outside help. They want concrete approaches (CRDTs vs. operational transformation vs. last-write-wins), not a definition-level overview.

What you will walk away with:

A clear reason why local LLM integration turns offline sync into a harder problem than simple read-only caching, along with a framework for choosing last-write-wins, CRDTs, or operational transformation based on the data type involved. You’ll get a concrete sync queue design for Electron, covering local storage choice, write queuing, retry behavior, and partial failure handling, plus a hybrid routing pattern for switching between local and cloud inference based on connectivity. The guide closes with storage and memory budgeting guidance for devices that stay offline for extended periods. 


Introduction

offline local llm desktop app integration


The global edge computing market is projected to reach USD 327.79 billion by 2033, expanding at a 33.0% CAGR from 2025 to 2033 (Grand View Research). That growth is not just infrastructure moving closer to users. It is software vendors deciding that a local model, running inside a desktop app, needs to keep working when the network does not.

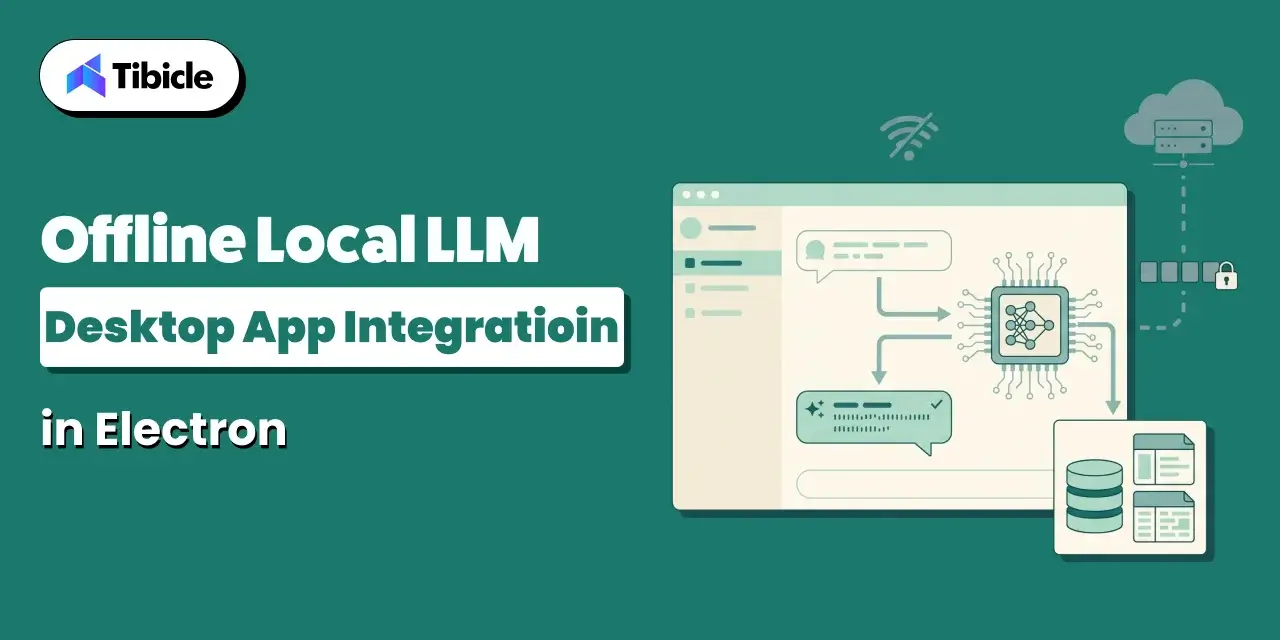
Offline local LLM desktop app integration used to mean caching the last known state and showing it while disconnected. That is no longer the whole job. Once a local model is generating new records while the device is offline, the app needs a real offline-first data sync architecture: a way to queue those records, merge them with whatever changed elsewhere, and resolve conflicts without losing data or duplicating it.

This guide covers why that shift happened, how to resolve conflicts in AI-generated data, how to structure the sync queue in Electron, where the local model fits in the architecture, the cost trade-offs between local and cloud inference, and how much storage and memory to budget for offline-resilient desktop software.

Why Offline-First Matters More Once a Local LLM Is Involved

The Old Offline Problem: Caching Data for Read-Only Access

The original offline problem in desktop software was narrow. An app fetched data while connected, stored a local copy, and served that copy when the network dropped. Users could read messages, view records, or browse a catalog without a connection. Apps either blocked writes outright or queued them as simple, single-field updates: a status flag, a checkbox, a renamed file. Conflict handling barely mattered because so little changed locally. Last-write-wins was good enough because there was rarely more than one write to compare.

The New Offline Problem: A Local Model Generating Data That Needs to Sync

A local LLM changes the shape of the problem. It can summarize a call, draft a document, tag a record, or generate a decision entirely offline, and every one of those outputs is new data that has to reconcile with the server and with other devices once connectivity returns. Unlike a manual edit, a cloud run of the same task can regenerate, revise, or supersede model output on reconnect. The sync layer now has to handle concurrent AI-generated records, not just concurrent user edits, and decide which version wins when both are plausible answers to the same prompt.

Conflict Resolution for Offline Local LLM Desktop App Integration

Why Simple Last-Write-Wins Breaks Down With AI-Generated Content

Last-write-wins assumes the most recent write is the most correct one. That assumption fails once a local model and a cloud model can independently produce a valid answer to the same input at nearly the same time. Overwriting one AI-generated record with another based on timestamp alone can silently discard a better answer, drop structured fields the other version lacked, or erase a human edit made in between. Once concurrent writes come from inference rather than typing speed, the system needs a merge strategy, not a tiebreaker.

Conflict-Free Replicated Data Types for Merging Without Coordination

A conflict-free replicated data type, or CRDT, is a data structure that lets any replica update independently; any two replicas that receive the same updates converge to the same state, deterministically, without central coordination (Preguiça, Baquero & Shapiro). Applied to offline sync, this means a list of tags, a counter of retries, or a set of flagged records can merge cleanly across devices without a server arbitrating every conflict in real time. CRDTs work well for structured data with well-defined merge rules. They are not a drop-in fix for free text.

When Operational Transformation Fits Better Than CRDTs

Operational transformation transforms concurrent operations against each other so the intent of each edit survives the merge, rather than picking a winner. It fits rich text and collaborative document editing, where two people or two processes may edit the same paragraph, and the merge must preserve both edits in a coherent order. CRDTs handle structured data like lists and counters more simply, but for free-form AI-generated text edited by multiple sources, operational transformation is usually the better fit. Some sync layers use both, choosing per field.

Approach How It Resolves Conflicts Best Fit
Last-write-wins The most recent timestamp overwrites earlier changes Simple, low-stakes data with rare concurrent edits
CRDTs Mathematically guaranteed convergence without central coordination Structured data like lists, counters, and sets edited offline
Operational transformation Transforms concurrent operations to preserve intent Rich text and collaborative document editing

Architecting the Sync Queue in an Electron Application

offline local llm desktop app integration

Local-First Storage: SQLite or Embedded Database Choices

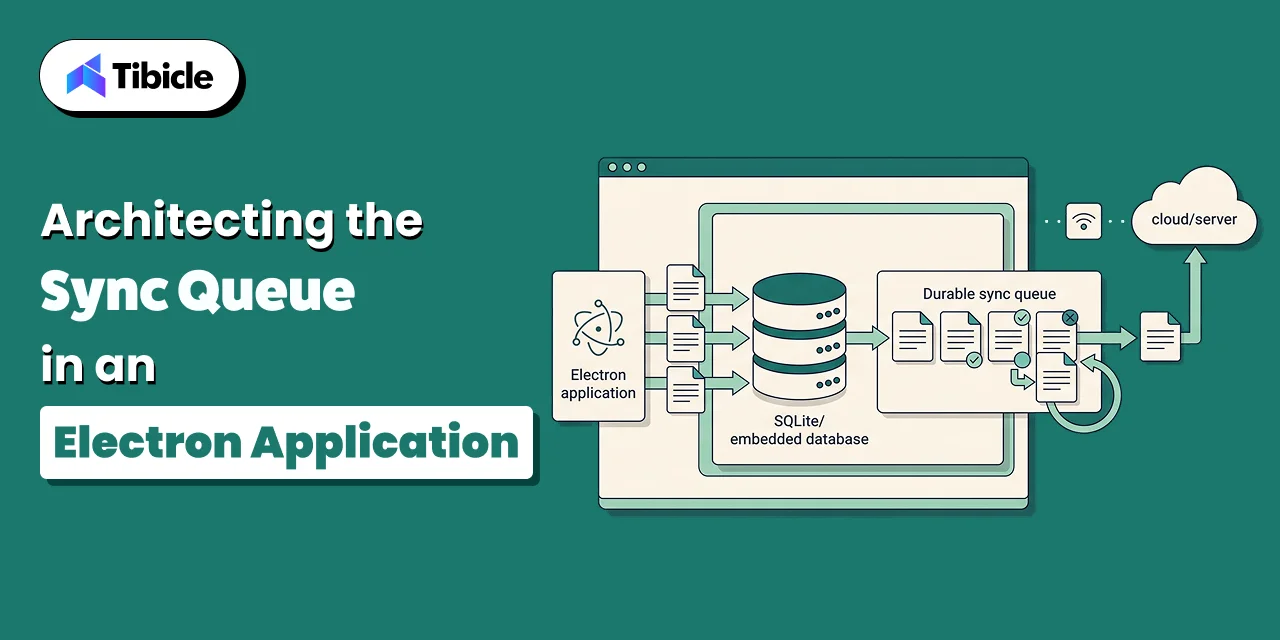
An Electron app needs a local store that survives crashes and holds a full working copy of the user’s data, not just a cache. SQLite is the common default: it is embedded and transactional, and Node bindings support it well, which makes it a reasonable base for a sync queue table alongside application data. Some teams choose an embedded document store instead when the data is less structured, such as raw model output before the app normalizes it. The choice matters less than making sure every local write goes through the same table the sync engine reads from.

Queuing Writes and Retrying on Reconnect in Offline Local LLM Desktop App Integration

Every write made offline, whether typed by a user or generated by the local model, should land in a durable queue before anything else happens to it. On reconnect, the queue drains in order, with retry and backoff for individual failed items rather than the whole batch. A queue that lives only in memory loses everything on an unexpected quit. A queue backed by the same SQLite file as the rest of the app survives restarts and gives the sync engine a clear, inspectable record of what is still pending.

Handling Partial Sync Failures in Offline Local LLM Desktop App Integration

Partial failures are the normal case, not the exception. A batch of twenty queued writes might sync eighteen successfully and fail two due to a validation error or a stale conflict. The failed items need to stay in the queue with their own error state, rather than having the app drop them or silently retry them forever. Logging which records failed, why, and how many attempts the app has made turns a support ticket into a five-minute fix instead of a data recovery exercise.

Where the Local LLM Fits: Architecture for Offline Local LLM Desktop App Integration

offline local llm desktop app integration

Running Inference Locally When There’s No Network at All

When the device has no connection, the local model is the only inference path available. This is why offline local LLM desktop app integration usually pairs a smaller, quantized model with the app itself rather than relying on a cloud call that will simply fail. Heavily quantized large models consistently outperform smaller, high-precision models, with a practical performance threshold around 3.5 effective bits-per-weight (A Systematic Evaluation of On-Device LLMs). That finding argues for shipping a larger model at aggressive quantization rather than a smaller model at higher precision, within the memory budget the device allows.

Falling Back to Cloud in Offline Local LLM Desktop App Integration

Once the network comes back, the app has a choice: keep using the local model or route new requests to the cloud model it may normally prefer for quality or context length. Most architectures switch new requests to the cloud path immediately on reconnect, while letting already-queued local outputs sync as-is rather than re-running them. Re-running every offline output through the cloud model on reconnect duplicates cost and can produce a second, conflicting answer to a question the app has already answered.

Keeping Output Format Sync-Compatible in Offline Local LLM Desktop App Integration

The sync layer should not need to know which model produced a given record. That only works if local and cloud inference write to the same schema. A record generated offline and a record generated in the cloud should carry the same fields, the same validation rules, and the same table, so the merge logic written for one works for both.

  • Structure local model output the same way regardless of which model produced it, local or cloud
  • Timestamp and tag every AI-generated record with its origin, since offline and online outputs may need different review
  • Queue model outputs through the same sync path as user-entered data, not a separate pipeline
  • Test the reconnect path deliberately, since most sync bugs surface during recovery, not during the offline period itself

Cost and Architecture Trade-offs Between Local and Cloud Inference

Why Cloud Costs Keep Falling but Offline Local LLM Desktop App Integration Still Matters

Cloud inference prices for a fixed level of benchmark performance have fallen by a range of 9x to 900x per year depending on the benchmark, according to Epoch AI’s tracking of frontier model pricing (Epoch AI). That trend makes a strong argument for routing most requests to the cloud by default. It does not remove the case for local inference. A device with no connection has no cloud path at any price, and a local model also removes round-trip latency for interactive use cases regardless of connectivity.

Hybrid Routing for Offline Local LLM Desktop App Integration: Local for Offline, Cloud for Everything Else

The practical pattern is hybrid routing: default to the cloud model when connected, fall back to the local model automatically when the network drops, and route back to the cloud once the connection is confirmed stable rather than on the first packet that gets through. This keeps quality high most of the time while guaranteeing the app still functions during an outage, a flight, or a site with no signal.

Testing an App With Networking Deliberately Disabled

Hybrid routing is only as good as the fallback path that gets tested. Running the app with networking disabled at the OS level, not just by killing the API mock, surfaces the failure modes that matter: what happens when a request is mid-flight when the connection drops, what the user sees when the local model is loading, and whether the queue actually captures every write made during the outage.

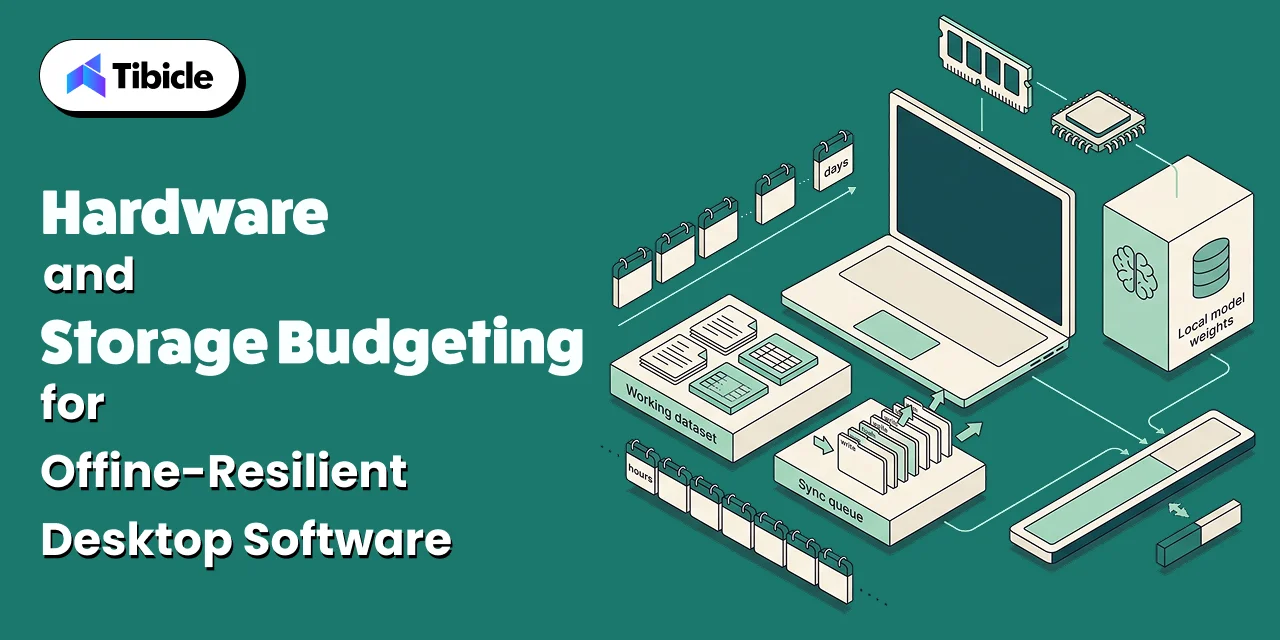
Hardware and Storage Budgeting for Offline Local LLM Desktop App Integration

actually

Local Storage Requirements for Offline Local LLM Desktop App Integration

Budgeting local storage means accounting for three things separately: the working dataset the app needs offline, the sync queue of pending writes, and any local model weights. The queue is usually small unless the app is generating heavy AI output offline for extended periods, in which case it can grow faster than teams expect. Setting a queue size ceiling and a policy for what happens when it is reached, such as blocking new local generation until the backlog clears, avoids an unbounded local database.

Memory Pricing and What It Means for On-Device Model Budgets

Memory budgets for on-device models are getting more expensive to plan around. TrendForce has forecast conventional DRAM contract prices rising 90 to 95 percent quarter over quarter in the first quarter of 2026, driven by AI and data center demand pulling supply away from consumer devices (TrendForce). For teams shipping a local model as part of the app, this makes the case for a smaller, well-quantized model even stronger, since it reduces exposure to rising memory costs on the devices the app runs on.

Planning Offline Local LLM Desktop App Integration for Extended Disconnection

Field devices, laptops used on long flights, or hardware deployed in low-connectivity regions can stay offline for days rather than hours. The sync queue and local storage budget need headroom for that case specifically, not just the average short outage. A queue sized for a two-hour gap will overflow on a two-week one, and the failure mode should be graceful degradation rather than silent data loss.

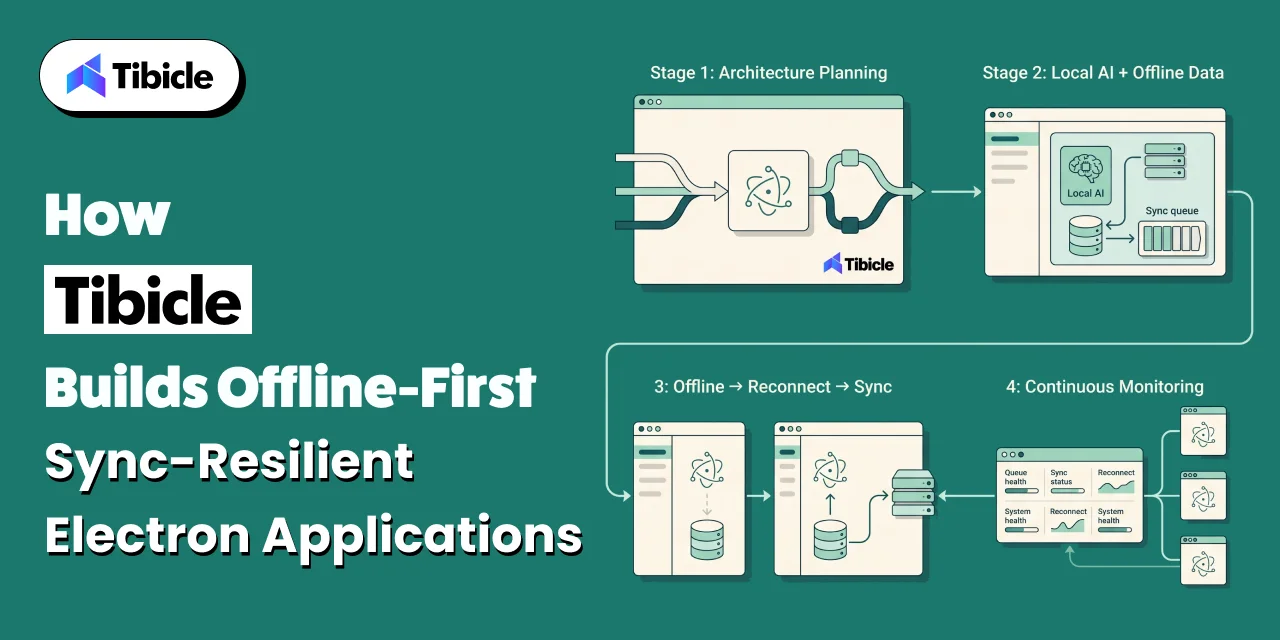
How Tibicle Builds Offline-First, Sync-Resilient Electron Applications

actually

Sync Architecture and Conflict Resolution Planning

Tibicle starts by mapping which data types in the app need CRDT-based merging, which need operational transformation, and which can safely use last-write-wins. That decision is made per field, not per app, based on how the data is actually edited offline.

Implementation With Local LLM and Hybrid Routing Built In

Implementation includes the local model, the sync queue, and the hybrid routing logic as one connected system rather than three separate features bolted together. Local and cloud inference write to the same schema from day one, so the sync layer never has to special-case which model produced a record.

Ongoing Support and Sync Monitoring

After launch, Tibicle monitors queue depth, sync failure rates, and reconnect behavior in production, since these are the areas most sync bugs come from. Issues get caught from queue metrics before they show up as a support ticket about missing data.

Key Takeaways for Teams Building Offline-Resilient Software

Offline local LLM desktop app integration introduces a new sync problem: locally generated data, not just cached data, that needs to merge cleanly later. CRDTs offer a mathematically sound way to merge concurrent offline edits without central coordination, especially for structured data. Falling cloud inference costs don’t remove the case for local inference, offline capability and latency still matter. Most sync bugs surface during reconnect, not during the offline period, so the recovery path needs deliberate testing. Getting the offline-first data sync architecture right early avoids a rebuild once real users start generating data offline at scale.

FAQ

What does offline local LLM desktop app integration actually require beyond running a model locally?
It requires a sync architecture that can accept new AI-generated records while offline, queue them durably, and merge them with server state on reconnect, not just a model that runs without internet access.

How do conflicting edits get resolved when two devices were offline at the same time?
It depends on the data type. Structured fields like lists or counters typically use CRDTs for automatic, coordination-free convergence. Free-form text usually needs operational transformation to preserve both edits’ intent.

Should we use CRDTs or a simpler last-write-wins approach for our sync layer?
Last-write-wins is fine for low-stakes, rarely-contested fields. Once AI-generated content or frequent concurrent edits are involved, last-write-wins risks silently discarding valid data, and a CRDT or operational transformation approach is safer.

What happens to AI-generated data created while a device is completely offline?
It should be written to local storage and queued through the same sync path as user-entered data, tagged with its origin, so it merges into the server state correctly once the connection returns.

How much local storage does an offline-resilient Electron app typically need?
Enough for the working dataset, the sync queue, and any local model weights, sized for the longest expected offline period rather than the average one, with a defined ceiling and overflow policy for the queue.

Does Tibicle build offline-first Electron applications with local LLM integration?
Yes. Tibicle designs the sync architecture, conflict resolution strategy, local model integration, and hybrid routing as one system, and provides ongoing sync monitoring after launch.

Ready to plan the sync architecture for your Electron app? Book a call with Tibicle.

Fine-Tuning vs. RAG Deployment: Total Cost of Ownership (TCO) for Enterprise AI Apps

What This Guide Covers

Who this is for

Commercial investigation. The reader is comparing two viable technical approaches before a budget or architecture decision, not looking for a definition of either term. They want numbers, a framework, and a clear answer on when each approach wins on cost.

Search intent

Enterprise engineering leads, ML platform teams, and technical decision-makers evaluating how to customize an LLM for a production application. Written for readers who already know what fine-tuning and RAG are and need to compare cost, not learn the basics. 

What you will walk away with:

A working framework for comparing fine-tuning and RAG on total cost of ownership rather than sticker price alone, including where the hidden costs sit in each approach and how OpenAI’s fine-tuning platform wind-down changes the calculation for teams already in production. The guide breaks down one-time training cost, the ongoing inference premium on fine-tuned models, vector database and per-query costs for RAG, and the accuracy and latency trade-offs that affect the decision beyond price. It closes with a break-even model readers can apply to their own request volume and data change frequency, plus the most common budgeting mistakes to avoid when making the call. 

Introduction

custom llm fine tuning services cost

OpenAI’s decision to wind down self-serve fine-tuning has made the cost comparison between fine-tuning and RAG harder to get right with old assumptions. Enterprises that treated the fine-tuning API as a stable, always-available option now have to factor in platform risk alongside training and inference pricing, while RAG’s own costs keep shifting as vector database pricing and per-query token costs move in opposite directions. This guide lays out what each approach actually costs, where the estimates most teams use fall short, and how to build a TCO model that holds up regardless of which provider changes its pricing or availability next. 

Why the Fine-Tuning vs RAG Cost Question Just Got More Complicated

OpenAI’s wind-down does not delete anything a team has already shipped. Inference on fine-tuned models keeps running until the underlying base model is deprecated (OpenAI). What changes is optionality. A team that assumed it could retrain a fine-tuned model whenever the underlying data shifted now has to check whether its organization still qualifies to start a new job, and that qualification window is shrinking on a fixed schedule. For a TCO model, that turns “retraining cost” from a variable a team controls into one partly controlled by the provider.

OpenAI Is Winding Down Self-Serve Fine-Tuning
OpenAI’s own deprecation notes confirm a three-stage schedule. Organizations with no prior fine-tuning history could not start new jobs after May 7, 2026. Starting July 2, 2026, organizations that have not run fine-tuned-model inference in the past 60 days lose the ability to start new jobs. On January 6, 2027, the ability to create new fine-tuning jobs closes for every remaining customer (OpenAI). Fine-tuned models already in production are not affected until their base model is deprecated separately.


What This Means for Enterprises Already Fine-Tuning
If a fine-tuned model is already live, nothing breaks this month. The practical exposure shows up at the next retraining cycle. A team that fine-tunes quarterly to reflect new product data needs to confirm its organization still qualifies to submit a new job, and needs a fallback plan for the point where OpenAI’s platform no longer accepts new jobs at all. That fallback is usually one of three things: fine-tuning through a different provider, moving to a hybrid RAG and fine-tuning setup, or shifting the customization work into the RAG layer entirely. Each option carries a different cost profile, which is the reason this comparison now needs updating more than once a year.


What Custom LLM Fine-Tuning Services Actually Cost

custom llm fine tuning services cost

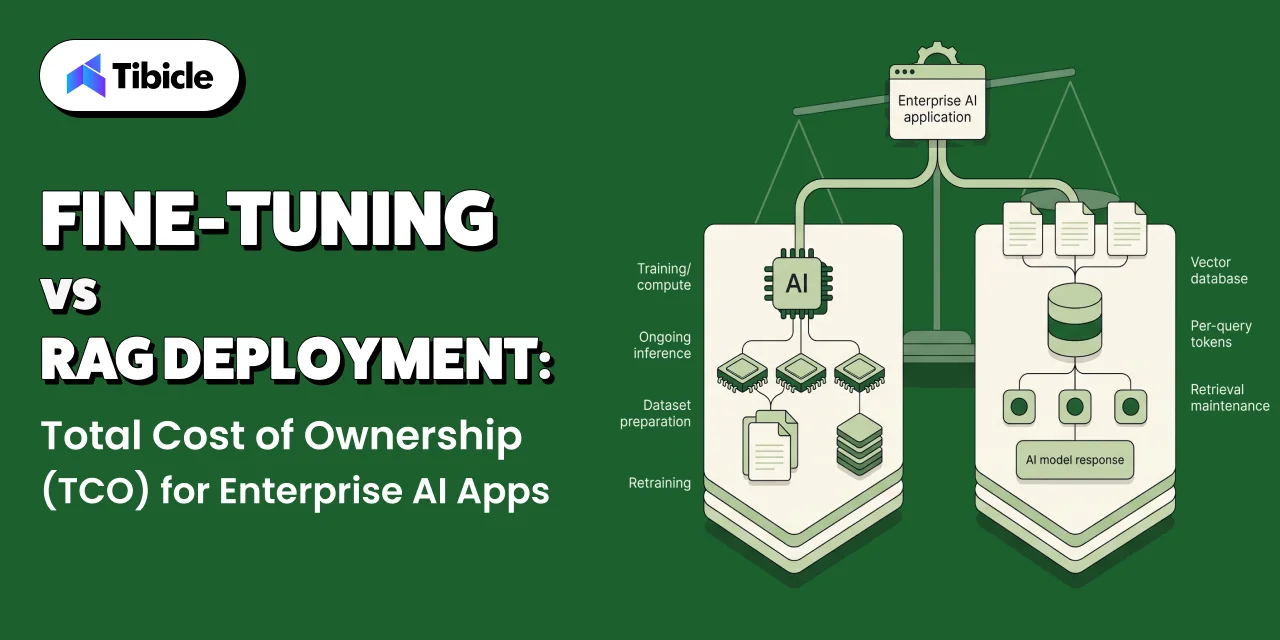
Custom LLM fine-tuning services cost has three components: a one-time training run, an ongoing inference premium, and a set of preparation and retraining costs that most estimates leave out. The training run is the easiest to quote and the smallest share of the real total.

One-Time Training Cost by Model Size

Training cost scales with model size and dataset size, not with how long the fine-tuning job runs on paper. A smaller open-weight model fine-tuned with LoRA on a few thousand examples can run into the low hundreds of dollars in compute. A larger proprietary model fine-tuned through a hosted API, or a full fine-tune of an open-weight model in the tens of billions of parameters, moves into the thousands to tens of thousands of dollars once GPU rental time, multiple training runs for hyperparameter tuning, and engineer time are counted. The training run itself is rarely the line item that breaks a budget.
The Ongoing Inference Premium on Fine-Tuned Models

The line item that does break budgets is the inference premium. Hosted fine-tuned models typically cost more per token to run than the equivalent base model, because the provider has to serve a custom checkpoint instead of a shared one. That premium compounds with volume. A fine-tuned model handling millions of requests a month carries that premium on every single call, for as long as the model stays in production. A TCO model that only accounts for the training run and skips this ongoing premium will consistently understate the real cost of fine-tuning.

Hidden Costs: Dataset Preparation and Retraining Cycles

Dataset preparation is the cost most teams underestimate. Building a fine-tuning dataset that actually improves the model, rather than one that overfits to a handful of examples, takes subject-matter expert time to write, review, and label examples. That cost repeats every time the underlying knowledge changes enough to require retraining, and retraining also means re-running evaluation to confirm the new checkpoint has not regressed on cases the old one handled correctly.

Approach Cost Structure Best Fit
Fine-tuning Higher upfront training cost, ongoing inference premium, retraining cost when data changes Stable domain knowledge, strict output format or tone requirements
RAG Lower upfront cost, ongoing vector database and per-query token cost Frequently changing knowledge bases, need for source citations
Hybrid (RAFT-style) Combines training cost with retrieval infrastructure cost Domain-specific reasoning that also needs current, grounded facts

What RAG Deployment Actually Costs

RAG deployment total cost of ownership sits mostly in infrastructure that keeps running after launch, not in a one-time setup fee. The three cost centers are the vector database itself, per-query token costs, and the pipeline work that keeps retrieval accurate.

Vector Database Infrastructure and Ongoing Storage Costs

Vector database spend is a recurring line item, and the category is growing fast enough that pricing models are still shifting. MarketsandMarkets projects the vector database market growing from roughly $2.65 billion in 2025 to $8.95 billion by 2030, a 27.5% compound annual growth rate (MarketsandMarkets). For a TCO model, that pace of growth means storage and hosting costs are unlikely to settle into a predictable flat rate any time soon, so a RAG deployment budget needs a review point, not a one-time estimate.

Per-Query Token Costs and Why They Keep Falling

Per-query costs are the one line item in this comparison moving consistently in the buyer’s favor. Epoch AI’s analysis of LLM inference prices at a fixed performance level found the cost to reach a given benchmark score falling by a median of roughly 40 to 50 times per year, with the range spanning 9x to 900x depending on the task (Epoch AI). That decline directly lowers RAG’s per-query token cost over time, since a RAG call typically includes both the retrieved context and the model’s response in the token count.

Retrieval Pipeline Maintenance Costs

Falling token prices do not remove the work of keeping retrieval accurate. Chunking strategy, embedding model choice, and re-ranking logic all need periodic review as the underlying knowledge base grows, and a pipeline that worked well at launch can degrade quietly as documents pile up unless someone is checking retrieval quality on a schedule. This maintenance work rarely shows up in an initial RAG cost estimate, and it is the RAG equivalent of fine-tuning’s retraining cost.

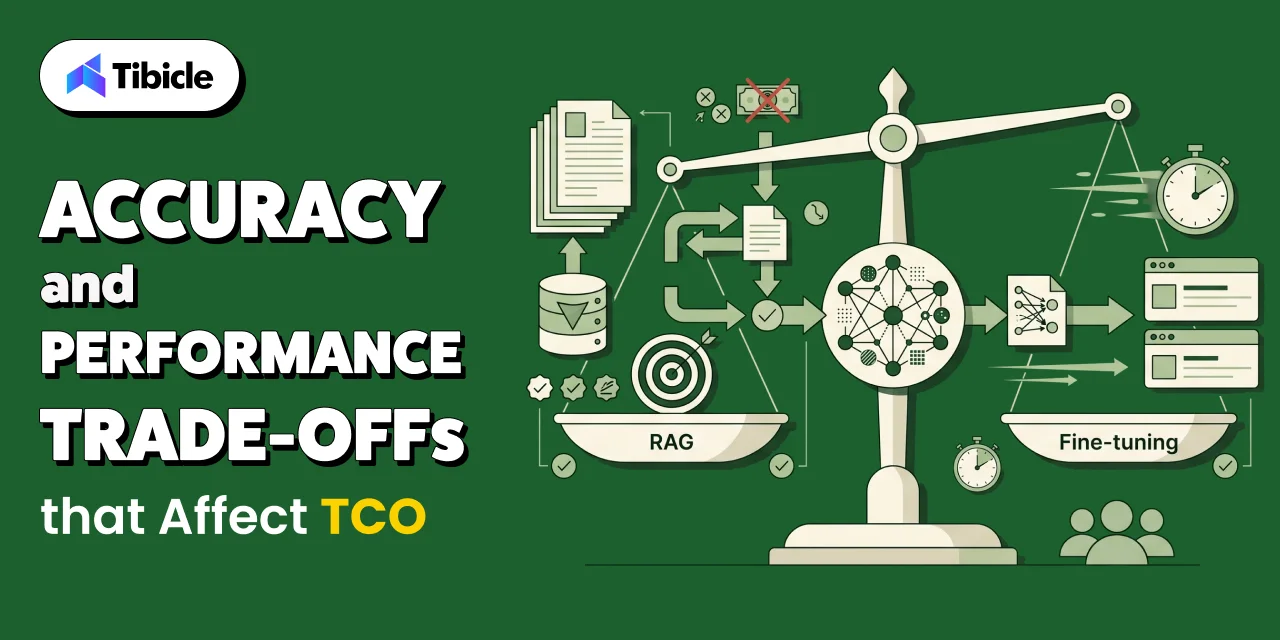
Accuracy and Performance Trade-offs That Affect TCO

custom llm fine tuning services cost

Cost alone does not decide this comparison, because the two approaches fail differently, and the cost of a wrong answer belongs in the TCO calculation.

Why RAG Typically Wins on Factual Accuracy

RAG grounds its answers in retrieved source documents, which gives it a natural advantage when facts change frequently or when a user needs to see where an answer came from. A fine-tuned model can only reflect what it saw during training, so anything that changed since the last fine-tuning cycle is invisible to it unless the request also includes retrieved context.

Why Fine-Tuning Wins on Latency and Output Consistency

Fine-tuning wins on latency and output consistency because there is no retrieval step to wait on and no risk of an irrelevant document changing the model’s tone or format mid-response. For applications with strict formatting requirements, such as generating structured reports or matching a specific brand voice, a fine-tuned model tends to hold that consistency more reliably than prompting alone.

RAFT: Combining Fine-Tuning and Retrieval

Retrieval Augmented Fine Tuning, or RAFT, is a training recipe from UC Berkeley researchers that fine-tunes a model on a mix of relevant and irrelevant retrieved documents, training it to ignore the irrelevant ones and cite the useful ones directly (Zhang et al., UC Berkeley). The paper reports consistent performance gains across PubMed, HotpotQA, and Gorilla, three domain-specific RAG benchmarks, which makes RAFT a practical middle path for teams that need both grounded facts and fine-tuned output behavior.

  • Model the cost of being wrong, not just the cost of the API call, when weighing RAG’s accuracy advantage
  • Treat fine-tuning as a tone and format tool first, a knowledge tool second
  • Budget retrieval quality testing separately from model selection, since poor chunking can undo an otherwise sound RAG architecture
  • Revisit the TCO comparison whenever a provider changes fine-tuning availability or pricing, not just once at project kickoff

A TCO Framework for Choosing Between Fine-Tuning and RAG

The deciding factor in most TCO comparisons is not raw cost, it is how often the underlying data changes, set against a market that is increasingly buying AI capability rather than building it.

When the Data Changes Frequently, RAG Usually Wins on TCO

If the knowledge base updates weekly or daily, retraining a fine-tuned model on that cadence is rarely affordable. RAG’s ability to pull from an updated index without a training run makes it the lower-TCO option whenever freshness matters more than output consistency.

When Fine-Tuning’s Upfront Cost Pays Off

Fine-tuning’s upfront cost pays off when the underlying knowledge is stable and the requirement is really about behavior, such as matching a specific tone, output format, or reasoning style across thousands of similar requests. That shift toward buying rather than building extends beyond the fine-tuning decision itself. Menlo Ventures’ 2025 State of Generative AI in the Enterprise report found the enterprise build-to-buy ratio moving from 47% built and 53% purchased in 2024 to 24% built and 76% purchased in 2025 (Menlo Ventures). That trend supports treating fine-tuning as a targeted, well-scoped investment rather than a default customization strategy.

Modeling Break-Even Between the Two Approaches

A break-even model needs a time horizon and a query volume estimate. Divide fine-tuning’s one-time training cost plus its ongoing inference premium, projected over that horizon, against RAG’s vector database and per-query costs over the same horizon and volume. The approach with the lower total at the chosen horizon wins on TCO, though the accuracy and latency trade-offs above should still weigh into the final call.

Common TCO Mistakes Enterprises Make

volume

Most first-time comparisons between fine-tuning and RAG make one of three predictable errors.

Comparing Training Cost Against Per-Query Cost Without a Time Horizon

A one-time training cost and a per-query cost are not directly comparable numbers until a time horizon and volume estimate turn the per-query cost into a total. Comparing them as-is produces a number that looks meaningful and is not.

Ignoring the Fine-Tuned Inference Premium in the Ongoing Budget

Budgets that account for training cost but not the ongoing inference premium consistently underestimate fine-tuning’s real TCO, especially at high request volume.

Underbudgeting Retrieval Quality Work in a RAG Deployment

Teams frequently budget the vector database and the per-query cost and skip the ongoing labor of chunking review, re-ranking tuning, and retrieval evaluation, then wonder why a RAG system that scored well in testing performs worse in production six months later.

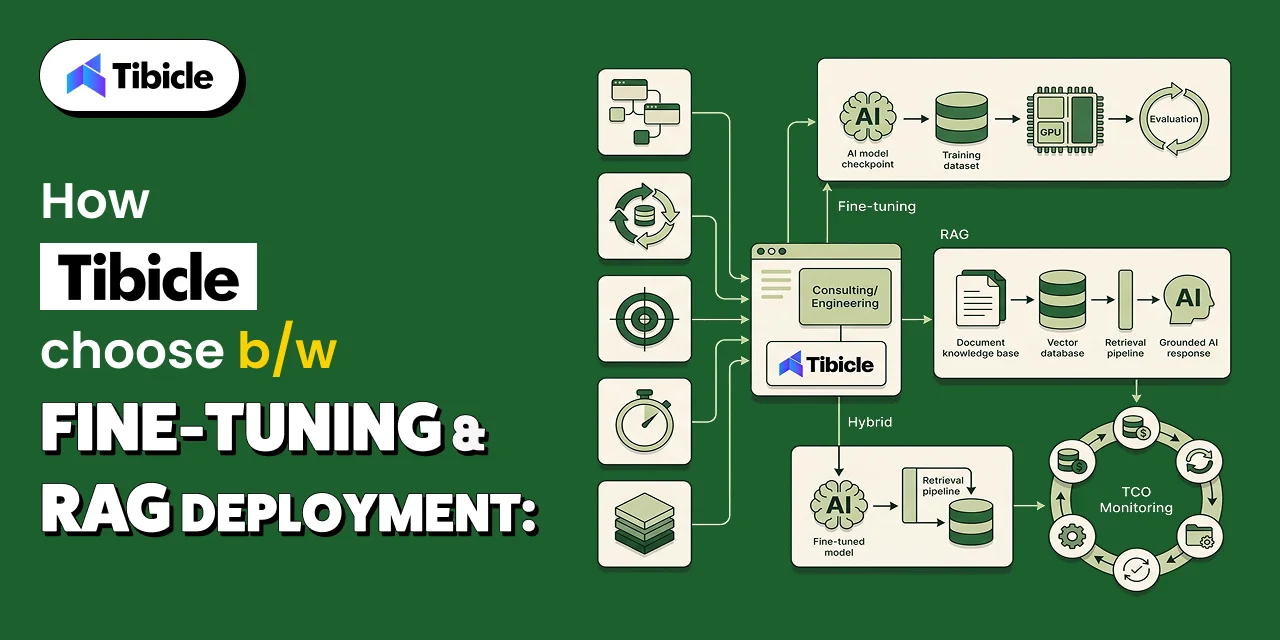
How Tibicle Helps Enterprises Choose Between Fine-Tuning and RAG

volume

TCO Modeling Before Any Architecture Decision

Tibicle builds a TCO model specific to the request volume, data change frequency, and accuracy requirements of each project before recommending fine-tuning, RAG, or a hybrid approach, so the architecture decision follows the numbers instead of a default preference.

Implementation of Fine-Tuning, RAG, or a Hybrid Approach

Once the model points to an approach, Tibicle handles the build, whether that means a fine-tuning pipeline with proper dataset preparation and evaluation, a RAG system with a tested retrieval pipeline, or a RAFT-style hybrid that combines both.

Ongoing Cost Monitoring and Model Updates

Because both provider pricing and platform availability keep shifting, Tibicle reviews the TCO model on a set schedule after launch and flags when a provider change, such as OpenAI’s fine-tuning wind-down, affects the original cost assumptions.

Key Takeaways for Teams Budgeting Enterprise AI

Custom LLM fine-tuning services cost now needs to account for provider platform risk, not just training and inference pricing. RAG’s total cost of ownership sits in ongoing vector database and per-query costs, both of which are shifting fast in opposite directions. Fine-tuning wins on latency and output consistency, RAG wins on factual accuracy and freshness, and most enterprise systems end up needing both in some combination. A TCO comparison needs a time horizon: comparing a one-time training cost against a per-query cost without one produces a number that means nothing. 

Book a call with Tibicle to model your TCO.

FAQ

What does custom LLM fine-tuning services cost typically include beyond the training run itself?
Beyond the training run, the real total includes dataset preparation, the ongoing inference premium on fine-tuned models, evaluation after each retraining cycle, and the labor cost of subject-matter experts reviewing training examples.

Is RAG cheaper than fine-tuning for an enterprise AI application?
It depends on data change frequency and query volume. RAG tends to win on TCO when the knowledge base updates often, while fine-tuning can be cheaper over time for stable knowledge at very high query volume, since it avoids a retrieval step on every call.

Does OpenAI winding down its fine-tuning API affect enterprises that already have a fine-tuned model?
Not immediately. Inference on existing fine-tuned models continues until the underlying base model is deprecated. The impact shows up at the next retraining cycle, when the organization needs to confirm it still qualifies to start a new fine-tuning job under OpenAI’s tightening eligibility window.

Can fine-tuning and RAG be combined in the same application?
Yes. RAFT, a training recipe from UC Berkeley researchers, fine-tunes a model to work with retrieved documents directly, and many production systems use a similar hybrid pattern to get both grounded facts and consistent output behavior.

How do we calculate the break-even point between fine-tuning and RAG?
Pick a time horizon and a query volume estimate, then compare fine-tuning’s training cost plus its ongoing inference premium over that horizon against RAG’s vector database and per-query costs over the same horizon and volume.

Does Tibicle help enterprises choose and implement between fine-tuning and RAG deployment?
Yes. Tibicle builds a TCO model specific to each project before recommending an architecture, then implements fine-tuning, RAG, or a hybrid approach and reviews the cost model on a set schedule after launch.

Migrate Web AI App to Electron Desktop via Electron

What This Guide Covers

Who this is for

CTOs, VP Engineering, and technical founders at companies running an AI feature inside a web app who are weighing whether to migrate their web AI app to Electron desktop. This applies most directly to teams where the AI workflow is central to the product, not a side feature, and where engineering leadership needs to decide between a quick Electron wrapper, a hybrid rebuild, or
holdingoff entirely.

Search Intent

Someone searching “migrate web ai app to electron desktop” is past the exploratory stage. They already run a web-based AI product, they’ve likely hit a real performance or resource complaint from users, and they’re looking for a decision framework: is this worth doing, which technical path fits their situation, and what will it cost in time and budget. They want data to justify the call internally, not a general explainer on what Electron is.  
What you will walk away with:

By the end of this guide you’ll know whether your AI feature’s performance problems actually stem from the browser or from something else entirely, backed by measured latency data comparing in-browser and native inference. You’ll understand the three realistic migration paths (thin wrapper, hybrid shell, and partial rebuild), which one fits an AI-heavy product like yours, and the specific architecture changes each one requires, including how to keep your existing backend APIs and avoid building a second authentication system. You’ll also leave with realistic cost and timeline ranges pulled from industry pricing data, so you can set expectations with your team and stakeholders before committing to a build.


migrate web ai app to electron desktop
Introduction  

A quarter of people who use browser tabs report their browser or computer has crashed from having too many open at once, according to a Carnegie Mellon University CHI 2021 study. That statistic matters more than it used to. AI features now run inference, hold model state, and stream responses inside the same browser tab competing for that memory.

Deciding to migrate a web AI app to Electron desktop used to be a product preference. It is now a resource math problem. When an AI feature needs consistent latency and local compute, the browser sandbox becomes the constraint, not the UI framework. This guide walks through why that ceiling appears, what the performance data actually shows, and how a CTO should sequence a migration: which path to choose, what changes in the architecture, and what it costs.


Why Browser-Based AI Workflows Hit a Ceiling Before You Migrate a Web AI App to Electron Desktop

Tab Overload and Resource Contention in the Browser

Modern knowledge workers keep dozens of tabs open across research, communication, and work tools. Each tab shares one process pool, one memory ceiling, and one GPU context with every other tab in the window. A Carnegie Mellon study on tab usage found that people rarely close tabs even as the number becomes unmanageable, because closing one risks losing information they can’t easily recover. That behavior means AI features don’t get a clean, dedicated environment. They compete for CPU cycles and memory against a browser session that was never built to isolate a single demanding workload.

What Happens When an AI Feature Competes for Browser Memory

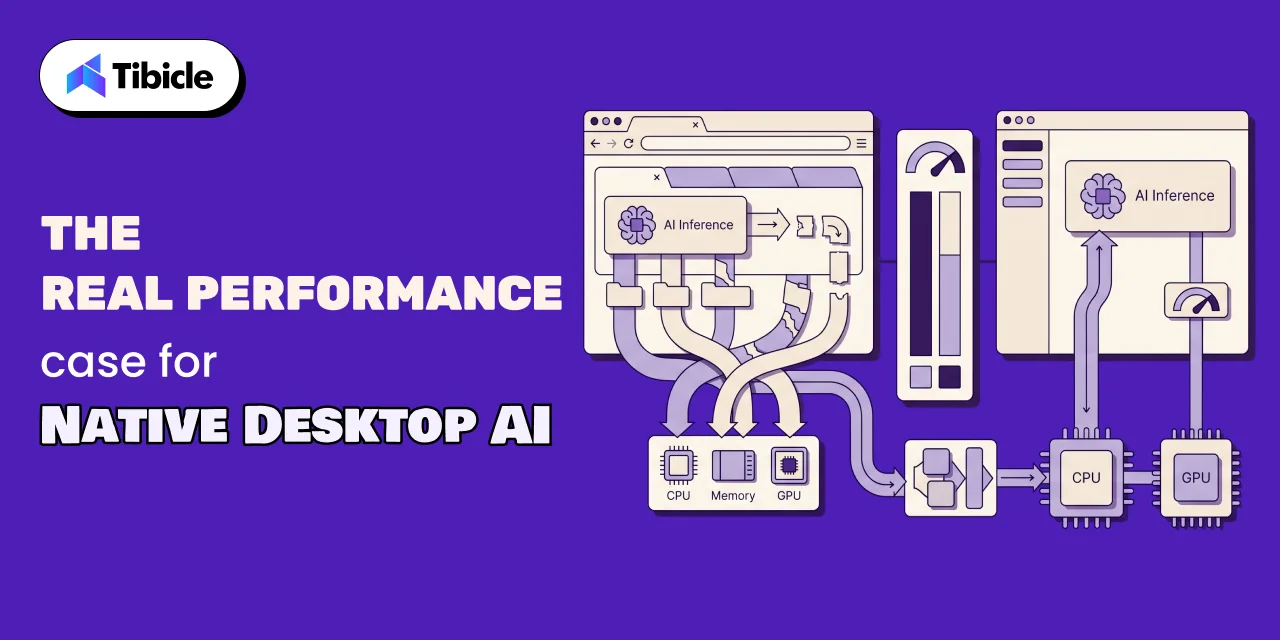
Inference workloads load model weights, run repeated forward passes, and often need low, predictable latency between input and output. In a browser, all of that shares the same process space as every other open tab, extension, and background script. Garbage collection pauses, extension overhead, and inconsistent tab throttling all sit between the AI feature and the hardware. The result isn’t a fixed slowdown. It’s variability: an AI response that took 400ms on a fresh tab can take several seconds once the same session has accumulated the normal clutter of a workday. For a chat interface, that variability is tolerable. For anything closer to real-time (voice, live transcription, on-device generation) it starts to define whether the product feels usable.

The Real Performance Case to Migrate a Web AI App to Electron Desktop

migrate web ai app to electron desktop

In-Browser Inference vs Native: What the Research Actually Shows

The clearest data point on this gap comes from a 2024 measurement study covering 9 deep learning models across 50 PC devices, published as “Anatomizing Deep Learning Inference in Web Browsers” in ACM Transactions on Software Engineering and Methodology. The researchers found in-browser inference runs 16.9 times slower on CPU and 4.9 times slower on GPU than native inference on the same hardware. On mobile devices the gaps were 15.8 times and 7.8 times, respectively. The same study measured memory use exceeding 334 times the model’s own size in some cases, and a 67.2% increase in the time it takes GUI components to render during inference. This is not a marginal overhead. It’s a structural limitation of running inference inside a browser sandbox.

Where WebGPU Has Closed the Gap and Where It Hasn’t

WebGPU gives browser-based inference direct access to GPU compute in a way WebGL never did, and it’s the reason the GPU-side gap (4.9x) is smaller than the CPU-side gap (16.9x) in the same study. It helps most with workloads that are already GPU-bound, like transformer inference with batched matrix multiplication. It does less for CPU-bound preprocessing, tokenization, and the browser’s own runtime overhead, including the Wasm virtual machine layer identified as a contributing factor in the same research. So WebGPU narrows the performance case for migrating, but it doesn’t remove it, particularly for CPU-heavy or latency-sensitive workflows.

When the Performance Gap Doesn’t Matter Enough to Migrate Your Web AI App to Electron Desktop

Not every AI feature needs this fix. If the product calls a cloud API and simply renders the response, the browser isn’t the bottleneck, the network round trip is, and Electron won’t change that. The performance case for native desktop applies specifically to local or on-device inference, offline requirements, or workflows where sub-second, consistent latency is part of the product’s value. A CTO should treat this migration as targeted, not automatic: match the fix to the actual bottleneck before committing engineering time to it.

A CTO’s Migration Roadmap: Wrapper, Hybrid, or Rebuild

migrate web ai app to electron desktop

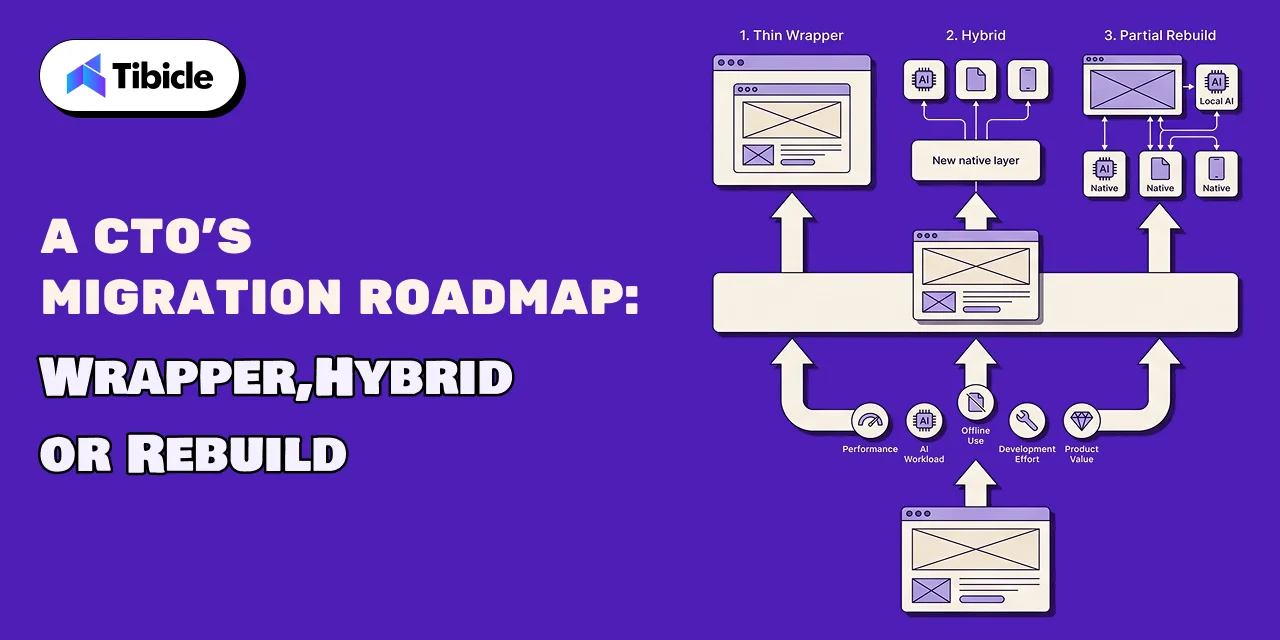
The Thin Wrapper: Fastest Path, Least Native Benefit

Loading the existing web app inside an Electron window is the fastest way to ship a desktop icon. AI calls stay cloud-based, and the browser-based inference limitations above still apply, because the underlying rendering engine hasn’t changed. This path works for validating desktop demand or for products where AI performance was never the bottleneck.

The Hybrid Shell: Reusing Frontend Code With Native AI Modules

A hybrid shell keeps the existing frontend code and adds a native Electron main process that handles local inference, file system access, and hardware-level tasks. This is the path most AI-heavy web apps end up choosing, because it avoids a full frontend rewrite while still solving the actual performance problem: moving inference out of the browser sandbox.

When a Partial Rebuild Is Actually Worth It to Migrate a Web AI App to Electron Desktop

A partial rebuild, where AI-heavy screens are rebuilt specifically to call native modules and local inference directly, makes sense when AI latency or offline access is the core product value, not a supporting feature. This is the highest-cost path and should be reserved for products where the AI workflow is the reason customers pay.

Path What It Involves Best Fit
Thin wrapper Load the existing web app in an Electron window; AI calls stay cloud-based Fast validation with no native performance requirement
Hybrid shell Reuse frontend code; add a native main process for local inference and file access Most AI-heavy web apps moving to desktop
Partial rebuild Rebuild the AI-heavy screens to use native modules and local inference directly Products where AI latency or offline access is the core value

Architecture Changes Specific to a Web AI App to Electron Desktop Migration

Moving Inference From Browser JS to the Electron Main Process

The core architectural change in any hybrid or partial-rebuild migration is relocating model loading and inference calls out of the renderer process (which still behaves like a browser tab) and into the Electron main process or a native module. This is what actually captures the performance gains described above, because it removes the Wasm and browser-runtime overhead entirely rather than optimizing around it.

Reusing Existing Backend APIs While Adding Local Inference

The existing REST or GraphQL backend doesn’t need to be replaced. It stays the source of truth for account data, sync, and any cloud-based model calls, while local inference is added as a supplement for tasks that benefit from on-device speed or offline access. This keeps the migration scoped to the AI workflow rather than turning into a full backend rewrite.

Data Sync Between the Web App and the New Desktop Client

Most companies run the web and desktop versions in parallel during the transition, so the desktop client needs to read and write through the same data model the web app already uses. Building a separate desktop-only data layer creates two sources of truth and doubles the maintenance surface for no real benefit.

Key architecture changes to plan for:

  • Keep the existing REST or GraphQL API as the source of truth; add local inference as a supplement, not a replacement
  • Move model loading and inference calls out of the renderer process into the main process or a native module
  • Reuse authentication tokens from the web app instead of building a separate desktop login flow
  • Plan for users running both the web and desktop versions during the transition period

Electron Adoption Context: Who’s Already Doing This

authentication

Image-Prompt:A subtle grid or network illustration made up of simple abstract application-window icons (represented as generic rounded rectangles with minimal UI lines, not real logos) connected by thin lines to suggest a broad ecosystem of adoption. One icon in the center is slightly larger and highlighted to represent a featured example, surrounded by smaller uniform icons in a soft radial layout. Flat vector style, muted corporate palette (slate, navy, off-white) with a single accent color, conveying scale and widespread industry use without naming any specific company or brand. 16:9 aspect ratio. 

Companies Already Shipping AI Features in Electron

Electron is used in production by 6.5% of all developers and 6.3% of professional developers, according to the 2024 Stack Overflow Developer Survey. That places it ahead of several purpose-built native toolkits in the same “other frameworks and libraries” category, and it reflects years of production use across chat, IDE, and productivity software before AI features became part of the pitch.

What Changes for the Engineering Team Day to Day

Frontend engineers keep working in the same component code most of the time. What’s new is a main process layer that handles native calls, file access, and inference, plus a build pipeline that produces signed, distributable binaries instead of a single deployed URL. Code review starts to include process-boundary questions: does this feature belong in the renderer or the main process?

Skills Gap: Web Engineers Learning Native Packaging

The gap most teams underestimate isn’t inference code, it’s packaging: code signing certificates, notarization for macOS, auto-update pipelines, and platform-specific installer formats. None of this is hard individually, but it’s unfamiliar territory for a team that has only ever shipped to a browser, and it takes real calendar time to get right the first time.

Budgeting and Timeline for the Migration

Realistic Cost Ranges by Migration Path

Clutch’s Software Development Company Pricing Guide puts most software development projects on its platform in the $10,000 to $49,000 range, with typical hourly rates between $24 and $49 per hour, and an average project cost of $132,480 across all project sizes tracked. A thin wrapper migration sits at the low end of that range. A hybrid shell or partial rebuild with native inference work sits well above the average, closer to a full product build than a simple porting task.

Timeline Expectations for Each Migration Path

A thin wrapper can ship in a few weeks. A hybrid shell typically runs two to four months, depending on how much native module work the local inference requires. A partial rebuild of AI-heavy screens can run four to eight months or longer, closer to the 13-month average project timeline Clutch reports across its dataset.
What Extends a Migration Beyond the Original Estimate

The most common source of delay isn’t the inference code itself, it’s platform-specific packaging: code signing failures, notarization rejections, and auto-update edge cases that only appear once the app is in front of real users on real machines. Teams that budget time for this phase separately from feature development tend to hit their estimates more consistently than teams that treat packaging as a final, quick step.

How Tibicle Helps You Migrate a Web AI App to Electron Desktop

authentication

Migration Readiness Audit and Architecture Planning

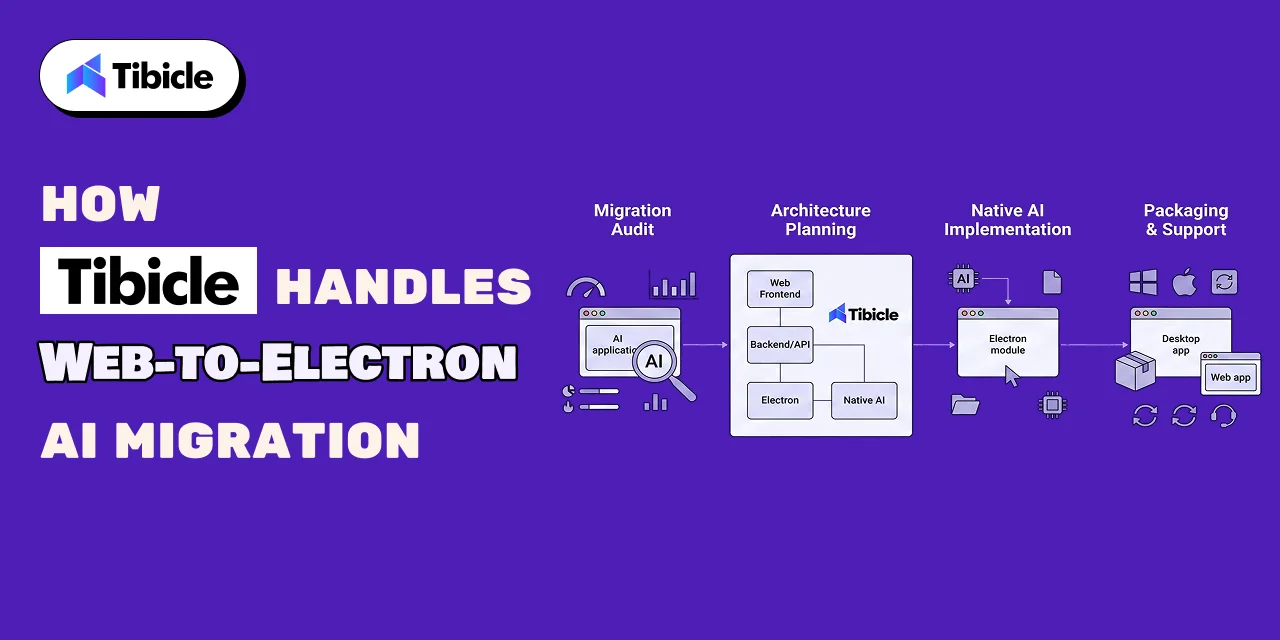
Before writing any Electron code, we run a short audit of the existing web app’s AI workflows to identify which features actually hit the browser performance ceiling and which don’t. That audit produces an architecture plan showing exactly what moves to the main process, what stays cloud-based, and which migration path (wrapper, hybrid, or rebuild) fits the product.
Implementation With Native AI Inference Built In

Implementation reuses the existing frontend code wherever the architecture plan allows it, and adds native modules for inference, file access, and hardware calls where the performance case justifies it. The existing backend APIs stay in place, so the web and desktop clients read from the same source of truth throughout the build.

Packaging, Rollout, and Long-Term Support

We handle code signing, auto-update pipeline setup, and platform-specific packaging for macOS, Windows, and Linux as a dedicated phase, not an afterthought. Rollout is staged so the web version keeps running for users who aren’t ready to switch, and long-term support covers OS updates, Electron version upgrades, and native module maintenance after launch.

Key Takeaways for CTOs Planning to Migrate a Web AI App to Electron Desktop

  • Deciding to migrate a web AI app to Electron desktop should be driven by a measurable performance or resource ceiling, not general momentum toward desktop apps
  • In-browser inference carries a real, measured latency gap against native, even with WebGPU acceleration in play
  • A hybrid shell that reuses existing frontend code while adding native inference fits most AI-heavy migrations better than a full rebuild
  • Budget and timeline estimates should account for the migration path chosen, since a thin wrapper and a partial rebuild are very different projects

Ready to scope your migration? Book a call with Tibicle to get an architecture plan specific to your AI workflow.

FAQ

How much faster is native AI inference compared to running it in a browser?
Measured across 50 PC devices, native inference runs about 16.9 times faster than in-browser inference on CPU and 4.9 times faster on GPU, based on the ACM TOSEM study cited above.

Do we need to rebuild our entire web app to migrate an AI workflow to Electron?
No. Most AI-heavy web apps fit a hybrid shell approach: the existing frontend code stays largely intact, with a native main process added specifically for inference and hardware access.

Can we reuse our existing backend APIs after migrating to a desktop app?
Yes. The existing REST or GraphQL API stays the source of truth for account data and cloud-based features, while local inference is added as a supplement rather than a replacement.

How long does a typical web-to-Electron AI migration take?
A thin wrapper can ship in a few weeks. A hybrid shell usually takes two to four months. A partial rebuild of AI-heavy screens can run four to eight months or more.

What happens to users still on the web version during the migration?
Most companies run both versions in parallel, with the desktop client reading and writing through the same data model as the web app to avoid creating two sources of truth.

Does Tibicle handle migrations from web-based AI apps to Electron desktop applications?
Yes. Tibicle runs a migration readiness audit, plans the architecture, implements the native inference layer, and handles packaging and long-term support after launch.


Building Private local AI Desktop App Development

What This Guide Covers

Who this is for: US tech firms, SaaS companies, startups, CTOs, engineering managers, and product teams looking for experienced Electron.js developers for ongoing private local AI desktop app development and custom desktop application development.

Search intent: Hiring and decision. This guide covers where to find Electron.js developers, how to evaluate their technical skills, and how dedicated developers compare with freelancers and in-house hires.

What you will walk away with: A practical hiring framework covering Electron architecture, native modules, cross-platform packaging, security, sourcing channels, technical screening, regional rates, onboarding, and long-term team management.

Introduction

private local ai desktop app development (target density: 2%)

The global edge AI market is projected to grow from $30.0 billion in 2026 to $118.7 billion by 2033. This represents a 21.7% compound annual growth rate. Data privacy is a key growth driver, alongside real-time processing and IoT expansion (Grand View Research ).This growth reflects a shift already underway in enterprises. Businesses are moving AI features from the cloud to local devices. This approach helps sensitive data stay within the organization.

For Electron software teams, this shift raises an important engineering question: How do you build desktop AI features with zero API reliance? The goal is to avoid hybrid apps that fall back to the cloud when features become complex.This guide explores private local AI desktop app development, covering architecture, hardware budgeting, model selection, compliance, and costs. It helps IT and engineering teams plan fully local AI solutions from the start, rather than addressing compliance gaps later.

Why Enterprises Are Moving Toward Private Local AI Desktop App Development

private local ai desktop app development (target density: 2%)

Enterprises evaluating AI features for desktop software increasingly rule out cloud APIs before comparing models. The reason is architectural, not preferential. Once a feature sends any user data to a third-party endpoint, that data falls under a vendor’s retention policy, breach history, and jurisdiction. For regulated industries or IP-sensitive workflows, that single dependency can disqualify an otherwise strong product.

What “No API Reliance” Actually Means in Practice

No API reliance means the AI feature runs entirely on the user’s machine, with no outbound network call required for it to function. The model, the inference runtime, and the data it processes stay local. This differs from “offline mode,” which usually means the app degrades gracefully without internet access. A fully local architecture has no degraded state to fall back from, because there was never a cloud dependency to lose.

The Cost of Getting Data Handling Wrong

The financial argument for local-only architecture has gotten harder to ignore. The global average cost of a data breach reached $4.99 million in 2026, up 12% year over year and the highest figure IBM’s Cost of a Data Breach Report has recorded (IBM). Every API call to a third-party AI provider is a potential point of exposure that this figure now prices in. A desktop app that never transmits user data to an external inference endpoint removes an entire category of breach vector, along with the vendor-risk assessments, data processing agreements, and downstream liability that come with sending data off-device in the first place. For compliance teams building a business case, that cost avoidance is often the argument that gets a fully local architecture funded over a cheaper hybrid build.

Architecting a Local-Only Electron App With No Cloud Fallback

A genuinely local-only Electron app is a design decision made before the first line of inference code is written, not a setting toggled later.

Designing for Zero Network Dependency From the Start

Zero network dependency should be a build constraint, not just a feature flag. Model weights should be included in the installer or an offline update bundle. The inference engine should run through a native module or bundled binary. Core AI functionality must not rely on external endpoints.

Treating local-first AI as a runtime preference can leave hidden cloud dependencies in the application. These dependencies often appear in complex features that teams initially find difficult to run on-device. Defining zero-API requirements during development helps ensure every AI feature follows the same local architecture.

Where Local Inference Actually Runs in the Electron Process Model

Inference belongs in the main process or a dedicated utility process, not the renderer. Running a quantized model directly in the renderer blocks the UI thread and complicates memory management under Chromium’s sandboxing rules. A utility process, communicating over IPC, keeps inference isolated, restartable, and easier to profile for memory and CPU load without freezing the interface the user is looking at.

What Breaks When Teams Assume “Local-First” Means “Local-Sometimes”

The most common failure occurs when a feature works locally during development but quietly switches to a cloud endpoint in production. This often happens when certain tasks seem too complex to run on the device, such as long-context summarization, large embedding models, or translation.

These exceptions can reintroduce the data exposure that a local-first architecture is designed to prevent. They may also go unnoticed during an initial security review if the primary chat feature genuinely runs locally. Every AI feature and fallback path must be tested to ensure the application maintains its zero-API requirement in production.

Approach Network Dependency Best Fit
Cloud-dependent Requires a live connection for every AI feature Consumer apps with no data sensitivity constraints
Hybrid with fallback Prefers local, falls back to cloud when needed Apps balancing capability against occasional connectivity
Fully local, no API Zero outbound calls for any AI feature, by design Regulated, air-gapped, or IP-sensitive enterprise environments

Model Selection for Fully Private, High-Quality Local Inference

private local ai desktop app development (target density: 2%)

Choosing a model for a fully local app comes down to one question: how much capability can a quantized model retain once there is no cloud model to fall back on for the hard cases.

Why Quantization Matters Even More When There’s No Cloud Fallback

When cloud fallback is unavailable, quantization becomes more than a way to reduce model size. It becomes an important factor in maintaining AI output quality. Research evaluating models ranging from 0.5B to 14B parameters across seven post-training quantization methods found that heavily quantized larger models consistently outperformed smaller, high-precision models. The study also identified a performance threshold of approximately 3.5 effective bits per weight (“A Systematic Evaluation of On-Device LLMs,” arXiv, 2025).

For fully local AI applications, teams should evaluate quantization alongside model size, memory usage, and output quality. Testing different configurations helps identify the right balance between performance and hardware requirements.

Below that threshold, output quality drops sharply. Above it, a larger quantized model beats a smaller full-precision one on most tasks. For a fully local Electron app, that means choosing the largest model a target machine can run at or above 3.5 BPW, not the smallest model that technically fits.

Matching Model Capability to What Enterprise Users Actually Need

Enterprise AI features rarely need general-purpose reasoning at the scale of a frontier cloud model. Document summarization, structured data extraction, and domain-specific classification all run well on smaller local models fine-tuned or prompted for the specific task. Scoping the model to the actual feature set, instead of picking the largest model available, keeps memory and latency in a range that ordinary business laptops can handle.

Updating Models Without Ever Touching the Network at Runtime

A fully local app still needs a model update path that never requires a live connection during normal operation. The standard approach ships model updates through the same installer or update mechanism used for the application binary itself, verified with a checksum before the new weights replace the old ones. This keeps model versioning under the same release process as the rest of the app, with no separate always-on connection to a model registry.

Data Sovereignty, Compliance, and Air-Gapped Deployment

versioning

Data Residency Requirements That Rule Out Cloud APIs

Regulations covering healthcare records, financial data, and government workloads frequently require that data never leave a specific jurisdiction, or never leave the device at all. A cloud API call, even to a provider with regional data centers, still creates a data transfer event that has to be documented and justified under GDPR and similar frameworks. A fully local architecture sidesteps that documentation burden entirely, since there is no transfer to justify.

Air-Gapped and Restricted-Network Deployment Scenarios

Some enterprise environments, such as defense, industrial control, and financial trading, operate on networks without external internet access. In these settings, cloud-dependent AI features may not function. A fully local Electron app can bundle its AI model and runtime within the installer. This enables deployment in air-gapped environments without requiring continuous internet connectivity. However, teams must plan for offline updates, security policies, and environment-specific configurations to ensure reliable deployment.

Audit Evidence for a System That Never Calls Out

Proving a system never calls out is different from proving it uses encryption or access controls. It requires logging and monitoring built for absence, not activity.

  • Log every model invocation locally, since there is no API provider dashboard to fall back on for audit evidence
  • Test the app with networking disabled at the OS level, not just with API keys removed
  • Document exactly what “no data leaves the device” means for auto-update, crash reporting, and telemetry, not just the AI feature
  • Package the model and runtime for install in a network-restricted or air-gapped environment from day one

Hardware Budgeting for Private Local AI Desktop App Development With Zero-API-Reliance Deployment

Removing the cloud from the architecture moves the compute cost somewhere else: onto every user’s machine.

Why Local-Only Private Local AI Desktop App Development Means Every User’s Machine Is the Infrastructure

Cloud APIs handle inference on the provider’s servers, while fully local apps rely on the employee’s hardware for AI processing. This makes hardware procurement an essential part of the AI budget.The device’s processing power and memory directly affect local AI performance. As a result, minimum system requirements can determine which employees have access to the feature. Teams should consider hardware costs alongside AI development and deployment expenses.

Memory Pricing and What It Means for Minimum Specs in Private Local AI Desktop App Development in 2026

Minimum system requirements are being defined during a period of significant memory price increases. TrendForce raised its Q1 2026 forecast for conventional DRAM contract prices to a 90%–95% quarter-over-quarter increase, up from its earlier estimate of 55%–60%. AI and data center demand are contributing to supply constraints in the consumer hardware market (TrendForce ).

For enterprises planning laptop purchases to support local AI features, rising memory prices can influence the choice between a 16GB and 32GB RAM minimum. Teams should evaluate model performance, memory requirements, and hardware costs together when defining deployment specifications. This approach helps balance application performance with hardware budgets.

Setting a Realistic Minimum Spec for Private Local AI Desktop App Development Without Alienating Users

The minimum system requirements should match the smallest model that delivers acceptable quality, rather than the largest model the team wants to deploy. Testing the quantized model on mid-range hardware helps establish realistic specifications. Relying solely on a developer’s workstation can lead to inaccurate requirements. Requirements that are too high may exclude many users. Without proper testing, performance issues can remain hidden until the application reaches production.

What Privacy-First Electron Development Actually Costs

A fully local build costs more upfront than a hybrid one, for reasons that are specific to removing the cloud, not general software complexity.

Engineering Cost of a Fully Local Architecture vs a Hybrid One

Software development companies listed on Clutch charge between $24 and $49 per hour. Reviewed projects typically range from $10,000 to $49,000, depending on the project scope (Clutch ). Fully local AI features may require additional development work, including model quantization, offline update packaging, and air-gapped testing. These requirements can increase costs compared to hybrid solutions that rely on cloud infrastructure.The additional investment supports data sovereignty and compliance requirements. It also helps businesses maintain greater control over how AI features process and manage sensitive data.

Ongoing Costs Without a Cloud Bill to Offset Them

A hybrid app trades engineering cost for an ongoing API bill. A fully local app has no equivalent recurring line item, but it does carry ongoing costs of its own: model retraining or re-quantization as better open models become available, update packaging for each release, and support for the wider range of hardware configurations a local-only feature has to run on.

Where Enterprises Overspend on “Private AI” Projects

The biggest overspending often happens when teams build a hybrid architecture, market it as private, and later discover cloud dependencies during a compliance review. Retrofitting a fully local solution can require significant additional development work. Defining the fully local, zero-API requirement at the beginning of the project helps avoid these unexpected costs. Establishing the architecture and security requirements early can prevent teams from rebuilding the same features twice.

How Tibicle Builds Privacy-First Local AI Desktop Software

versioning

Tibicle designs and builds Electron desktop applications for enterprises that need AI features with a verified zero-API architecture, not a hybrid app marketed as private.

Compliance and Architecture Assessment for Private Local AI Desktop App Development Before Any Code

Every engagement begins with a review of the project’s data residency, GDPR, and air-gapped requirements. These requirements are then mapped to the technical architecture needed to meet them. This process identifies which features can run fully locally from day one. It also highlights potential model and hardware trade-offs before development begins.

Implementation of Private Local AI Desktop Apps With Zero Outbound Dependency Verified

Development includes OS-level network-disabled testing, not just removing API keys. This ensures the finished app makes no outbound calls for any AI feature. The verification results are documented as part of the delivery, providing compliance teams with audit evidence that cloud-dependent solutions may not offer.

Ongoing Support and Air-Gapped Model Updates for Private Local AI Desktop App Development

Post-launch support includes model updates delivered through the same offline-compatible process as application updates. This allows the AI model to improve over time without requiring a live runtime connection. The approach supports restricted networks and air-gapped environments while maintaining offline deployment requirements.

Key Takeaways for Enterprise IT and Compliance Teams: Private Local AI Desktop App Development

  • Private local AI desktop app development means zero outbound calls by design, not just a cloud fallback that is rarely used
  • Quantization matters more here than in a hybrid app, since there is no cloud model to fall back on when local quality falls short
  • Data residency and air-gapped deployment requirements should shape the architecture from day one, not get retrofitted after a compliance review
  • Every user’s device becomes part of the infrastructure budget once there is no cloud compute to absorb the cost

Book a compliance and architecture assessment call with Tibicle.

FAQ

What does “no API reliance” actually mean for a private local AI desktop app?

It means the AI feature makes zero outbound network calls to function. The model and inference runtime run entirely on the user’s device, with no cloud endpoint the app depends on even as a fallback.

Can a fully local Electron app match the quality of a cloud-connected AI feature?

For scoped tasks like summarization and extraction, yes, when the model runs above roughly 3.5 effective bits per weight. General-purpose reasoning at frontier-model scale still favors the cloud, which is why scoping the feature to what local hardware can handle matters.

How does private local AI desktop app development support GDPR or data residency requirements?

Since no data ever transfers to a third-party endpoint, there is no cross-border transfer event to document under GDPR. This removes an entire category of compliance work that a cloud API architecture requires.

Can this kind of app run in an air-gapped or network-restricted environment?

Yes. Because the model and runtime ship inside the installer, a fully local app deploys the same way on an air-gapped network as it does on a connected machine, with no configuration change needed.

What hardware should we require from users for a fully local AI desktop app?

The minimum spec should be set by testing the actual quantized model on mid-range hardware, not a developer workstation, and should account for 2026 memory pricing pressure when budgeting RAM requirements.

Does Tibicle build privacy-first, fully local AI desktop software for enterprises?

Yes. Tibicle assesses compliance and architecture requirements before development, verifies zero outbound dependency with network-disabled testing, and supports air-gapped model updates after launch.

AI Integration Company for B2B SaaS Guide

What This Guide Covers

This guide examines how to choose an AI integration company for B2B SaaS when comparing offshore and nearshore engineering teams. It covers the factors that go beyond hourly rates, including talent access, time zone overlap, communication speed, and collaboration requirements for iterative AI projects.

You will learn how to compare offshore and nearshore AI engineering teams. You will also learn how to evaluate technical experience and structure a proof of concept. The guide covers data security, IP ownership, compliance, and access control. The guide also explains when staff augmentation, dedicated teams, or fixed-scope engagements make the most sense, along with the red flags that can indicate a weak AI integration partner.

By the end, you will have a practical framework for evaluating whether an offshore, nearshore, or another engineering model best fits your B2B SaaS product and AI roadmap.

Introduction

integration company for B2B SaaSai

The global IT services outsourcing market was valued at $744.6 billion in 2024 and is expected to reach $1,219.31 billion by 2030, growing at an 8.6% CAGR, according to Grand View Research’s IT Services Outsourcing Market Report. That growth is being driven by something more specific than general cost savings.

Choosing an AI integration company for B2B SaaS has become a talent-access decision as much as a budget decision. AI engineering skills are scarce enough right now that most product teams cannot simply hire their way to a production-ready integration in-house on a reasonable timeline. That scarcity shapes the choice between offshore and nearshore engineering, not just the hourly rate on a proposal.

This guide breaks down what actually changes between offshore and nearshore AI engineering teams, how to vet an AI integration company regardless of where it’s based, and the security, IP, and engagement-model questions that determine whether a partnership reaches production or stalls in pilot.

Why Companies Are Rethinking How They Choose an AI Integration Company for B2B SaaS

integration company for B2B SaaSai

From Cost Arbitrage to Talent Access

Outsourcing decisions used to start with a rate card. A company compared hourly costs across regions, picked the cheapest viable option, and treated engineering talent as broadly interchangeable within a given price tier. That model breaks down for AI integration work, where the pool of engineers who can actually take a retrieval-augmented generation system or a fine-tuned model from prototype to production is small relative to demand. The question has shifted from “where is this cheapest” to “where can I actually find and retain the specific skill set this project needs.”

The AI Skills Shortage Behind the Offshore vs Nearshore Decision

An ai integration company for B2B SaaS is competing for talent in one of the tightest hiring markets on record. Seventy-two percent of employers globally report difficulty filling open roles, and for the first time, AI skills have overtaken traditional engineering and IT capabilities as the hardest to find, according to ManpowerGroup’s 2026 Global Talent Shortage Survey.

That shortage doesn’t disappear because a company decides to look offshore or nearshore instead of hiring locally. It just changes shape. Offshore markets in South and Southeast Asia have deep benches of AI engineering talent but limited overlap with US working hours. Nearshore markets in Latin America have smaller but growing AI talent pools with far more schedule overlap. Neither location magically solves the underlying scarcity, which is exactly why vetting matters more than geography, a point this guide returns to in the next section.

Offshore vs Nearshore: What Actually Changes for an AI Integration Company for B2B SaaS Project

integration company for B2B SaaSai

Time Zone Overlap and Its Effect on AI Project Velocity

AI integration work is iterative in a way that a lot of traditional software development isn’t. Prompt behavior, retrieval quality, and model output all need to be reviewed against real examples, and those reviews are faster live than over an asynchronous ticket thread. Offshore teams in South or Southeast Asia typically offer limited same-day overlap with US business hours, which pushes review cycles onto a next-day cadence. Nearshore teams in Latin America generally overlap 4 to 8 hours with US working hours, which keeps daily standups, live debugging sessions, and rapid prompt-iteration cycles inside a single working day instead of stretching them across two.

Cost Differences Between Offshore and Nearshore AI Engineering Teams

Cost still matters, and the gap between offshore and nearshore rates is real, just smaller than it used to be as nearshore markets mature. The Latin America IT services outsourcing market generated $70.85 billion in revenue in 2024 and is projected to reach $126.32 billion by 2030 at a 10.1% CAGR, according to Grand View Research’s Latin America IT Services Outsourcing Outlook. That growth reflects rising demand for exactly this kind of nearshore engineering capacity, even at rates that sit above traditional offshore pricing.

In practical terms, offshore engagements still deliver the largest cost reduction against US in-house rates. Nearshore delivers a moderate reduction, positioned between offshore and onshore pricing, in exchange for the overlap advantage described above.

Communication and Cultural Alignment on Technical Reviews

Time zone overlap is only part of what makes a technical review effective. Nearshore teams working closely with US product organizations tend to develop closer alignment on how feedback gets delivered, how urgency gets communicated, and how much context gets assumed versus spelled out in a written brief. None of this is impossible to build with an offshore team, but it usually takes longer to establish and depends heavily on which specific people are assigned to the account, not just which country they’re in.

Model Typical Overlap and Cost Best Fit
Offshore(e.g. South/Southeast Asia) Limited same-day overlap, largest cost reduction Well-scoped, well-documented work with less need for live collaboration
Nearshore(e.g. Latin America) 4-8 hours of overlap with US business hours, moderate cost reduction AI integration work needing frequent live review and iteration
Onshore Full overlap, highest cost Leadership roles or highly regulated in-person work

Vetting an AI Integration Company for B2B SaaS Regardless of Location

integration company for B2B

Why Most AI Integration Company for B2B SaaS Projects Never Reach Production

Location is a smaller factor in project success than most procurement checklists suggest. About 95% of enterprise generative AI pilots deliver no measurable profit-and-loss impact, according to MIT NANDA’s “The GenAI Divide” report. That failure rate holds across offshore, nearshore, and onshore engagements alike, which means the

offshore-versus-nearshore decision matters less than most vendor evaluations assume. What separates the projects that reach production is scoping discipline, realistic evaluation criteria, and an engineering team that has actually shipped something similar before, not the time zone the team sits in.

Questions to Ask About Past AI Integration Work

Ask for the specific system architecture behind a past project, not just the outcome. What retrieval strategy did they use, and why that one over the alternatives? How did they handle hallucination or low-confidence outputs in production? What did the evaluation pipeline look like before the feature shipped? An AI integration company that has genuinely done this work will answer in specifics. One that hasn’t will drift back toward marketing language about “cutting-edge AI solutions” within a question or two.

Requesting a Scoped Proof of Concept Before Committing

A short, clearly scoped proof of concept, typically two to four weeks against a single well-defined use case, tells you more than any reference call. It shows how the team actually communicates, how quickly they surface problems instead of hiding them until the next milestone, and whether their estimate of effort was close to reality. Any vendor unwilling to structure a paid proof of concept before a longer commitment is asking you to skip the one step that would validate everything else in their pitch.

Security, IP, and Compliance Considerations Across Borders

integration company for B2B

Data Residency and Access Control With a Distributed Team

Governance gaps around AI access are common and expensive. Shadow AI now accounts for 43% of security incidents, more than double the prior year, and 92% of organizations that experienced an AI-related breach lacked proper AI access controls at the time, according to IBM’s Cost of a Data Breach Report 2026. A distributed engineering team, whether offshore or nearshore, adds another layer to this problem unless access is explicitly scoped and logged. Before any engineer touches production data, confirm exactly which systems they can reach, whether that access is role-based or blanket, and how it gets revoked when the engagement ends.

IP Assignment and Confidentiality Across Jurisdictions

A contract governed by US law doesn’t automatically mean the IP assignment clause is enforceable wherever the engineer actually lives and works. IP law varies by jurisdiction, and some countries require additional local documentation for a work-for-hire or assignment clause to hold up. This is worth confirming directly with the vendor rather than assuming the contract’s governing law clause covers it, particularly for any AI integration work that touches proprietary training data, prompts, or model configurations.

SOC 2 and Compliance Alignment With Your AI Integration Company for B2B SaaS Partner

SOC 2 compliance, or an equivalent framework, signals that a vendor has documented security practices rather than informal ones. But a claim of compliance and verified compliance are different things. Ask for the actual audit report or attestation, not just a badge on a website, and confirm it covers the specific team or subsidiary that will be working on your project rather than a parent company that carries the certification on paper only.

Confirm IP assignment terms are enforceable in the engineer’s home jurisdiction, not just in the contract’s governing law clause

Require a signed data processing agreement before any production access is granted

Ask which specific individuals will have access to production systems, not just which company

Verify SOC 2 or equivalent compliance status directly rather than accepting a claim at face value

Engagement Models: Staff Augmentation vs Dedicated AI Integration Company for B2B SaaS Team

Staff Augmentation for a Single AI Feature

Staff augmentation works well when your product team already has AI architecture decisions in place and needs additional engineering hands to implement a specific, well-defined feature. You retain ownership of design decisions; the augmented engineers execute against your existing roadmap and codebase conventions.

A Dedicated Team for Ongoing AI Roadmap Work

A dedicated team fits when AI integration isn’t a one-off feature but an ongoing part of the product roadmap: new model capabilities, expanding use cases, and continuous evaluation work that never really finishes. This structure gives the team context that compounds over time, since the same engineers carry institutional knowledge from one iteration to the next instead of relearning your system with every new project.

Fixed-Scope Projects and Where They Fall Short

Fixed-scope contracts work when requirements are genuinely stable, but AI integration work rarely stays that stable once real evaluation data starts coming in. Model behavior in production frequently reveals gaps that weren’t visible in the original scope, and a fixed-price contract without a change-order process either forces the vendor to cut corners to hit the original budget, or forces you into a slow renegotiation right when momentum matters most. Treat fixed-scope as a fit for narrow, well-understood integrations, not for exploratory AI roadmap work.

Red Flags When Evaluating an AI Integration Company for B2B SaaS

Vague Case Studies and No Named Technical References

Case studies that describe outcomes in general terms, “improved efficiency” or “streamlined operations”, without naming the client, the specific system built, or the engineer who led it, are a warning sign. Credible vendors can usually offer at least one reference call with an engineer who worked the project directly, not just an account manager summarizing it secondhand.

No Clear Answer on Data Handling or Model Training

Ask directly whether your data or prompts will be used to train or fine-tune any model, including models used for other clients. A vendor that hedges or gives an inconsistent answer across two different people on the same call hasn’t actually settled this internally, which means you’re the one absorbing that risk later.

Pricing That Doesn’t Map to a Defined Scope

A single lump-sum number with no breakdown by role, hours, or milestone makes it impossible to tell what you’re actually paying for, or to catch scope creep before it becomes a budget problem. A credible quote maps cost to defined deliverables and shows who is doing the work at each stage.

No engineer on the call can speak to a specific past RAG or LLM integration in technical detail

Vague answers about whether client data or prompts are used to train or fine-tune any model

A quote with no breakdown by role, hours, or milestone

No proposed proof-of-concept phase before a long-term contract is signed

How Tibicle Works as a Nearshore-Friendly AI Integration Company for B2B SaaS

Time Zone and Communication Fit for US Product Teams

Tibicle structures engagements around direct, senior-engineer access rather than routing every technical question through an account manager. That structure matters more for AI integration work than for standard feature development, since prompt tuning and evaluation review benefit from short, frequent feedback loops rather than long async threads. For B2B SaaS teams weighing an offshore vs nearshore AI engineering team decision, this kind of direct communication structure is what actually determines whether daily overlap translates into faster iteration.

AI Integration Process From Scoping to Production

Tibicle starts with a scoping phase. The team maps the AI capability to your existing architecture before coding begins. Next, the team runs a bounded proof of concept using real data. Only after that validation does the engagement move into full build, with evaluation criteria and success metrics defined upfront so both sides know what “production-ready” actually means before the sprint clock starts.

Ongoing Support and Team Scaling

Once an AI feature reaches production, the work doesn’t stop. Model behavior drifts, new use cases surface, and evaluation pipelines need maintenance. Tibicle keeps the same engineers on an account for ongoing roadmap work. The team can also scale as your AI roadmap expands. This avoids restarting the vetting process for each phase.

Key Takeaways for B2B SaaS Teams

Choosing an AI integration company for B2B SaaS is now a talent-access decision as much as a cost decision, given how scarce AI engineering skills are

Nearshore teams trade some cost savings for meaningfully more overlap with US working hours, which matters most on fast-iterating AI work

Vetting quality matters more than location. Most AI integration projects fail from weak scoping, not from where the engineers sit

IP assignment, data access, and compliance terms need to be settled before production access is granted, not after

Ready to talk through your AI roadmap? Book a call with Tibicle.

FAQ Section

What should a company look for in an AI Integration Company for B2B SaaS?

Look for engineers with specific AI integration experience. Ask how your data will be used. Review IP assignment terms in the engineer’s jurisdiction. Also, consider starting with a scoped proof of concept.

Is nearshore or offshore better for an ongoing AI Integration Company for B2B SaaS project?

Nearshore generally fits ongoing AI integration work better because of the daily overlap it provides for live review and iteration. Offshore can still work well for well-documented, well-scoped work that needs less real-time collaboration. Neither location guarantees success on its own; vetting quality matters more than the choice between the two.

How much time zone overlap do I actually need for AI engineering work?

Four to eight hours of overlap, the typical range for nearshore teams in Latin America, is usually enough to run daily standups and live technical reviews within a single working day. Less overlap pushes most feedback onto a next-day cycle, which slows iteration on prompt tuning and evaluation work specifically.

What questions should I ask about IP ownership and data handling before signing a contract?

Ask whether IP assignment is enforceable in the engineer’s home jurisdiction, not just under the contract’s governing law. Ask directly whether your data or prompts will be used to train or fine-tune any model. And require a signed data processing agreement before any production access is granted, not after the engagement starts.

Should I start with staff augmentation or a dedicated AI Integration Company for B2B SaaS team?

Staff augmentation fits a single, well-defined AI feature where your team already owns the architecture decisions. A dedicated team fits ongoing AI roadmap work where context and institutional knowledge need to compound across multiple projects over time.

Does Tibicle offer a nearshore-friendly AI Integration Company for B2B SaaS?

Yes. Tibicle works with B2B SaaS teams on AI integration projects with a structure built around direct senior-engineer access and daily overlap with US working hours, from initial scoping through a bounded proof of concept and into ongoing production support. Book a call to discuss a specific project.

Custom AI Chatbot Development Services

What This Guide Covers

Who this is for:
CIOs, CTOs, AI leaders, operations executives, customer support teams, and enterprise technology decision-makers evaluating custom AI chatbot development services for internal knowledge access, customer support, helpdesk automation, or other business-critical use cases. It is particularly relevant for organisations with proprietary knowledge bases, sensitive data, complex access controls, and requirements that extend beyond the capabilities of standard no-code chatbot platforms.

Search intent:
Commercial investigation and solution evaluation. The reader is not looking for a basic explanation of how AI chatbots work. They are evaluating whether to build a custom AI chatbot, use an off-the-shelf platform, or adopt a hybrid approach. The key decision factors are enterprise RAG chatbot architecture, hallucination control, data security, access control, system integration, build and maintenance costs, and measurable ROI before moving from pilot to production.

What you will walk away with:
A practical framework for evaluating and implementing a production-ready enterprise AI chatbot, including the differences between no-code, custom, and hybrid chatbot approaches; RAG architecture and retrieval pipeline design; knowledge base management; PII redaction and role-based access control; multi-channel and CRM integration; build and ongoing maintenance costs; and the key metrics required to measure ROI. You will also have a clearer basis for deciding what architecture your organisation needs and what must be in place before an enterprise chatbot is deployed against real company data.

Introduction

custom ai chatbot development services

The market for custom AI chatbot development services is expanding faster than most enterprise technology budgets anticipated. The global conversational AI market was valued at $13.2 billion in 2024 and is projected to grow at a compound annual growth rate of 23.7% through 2030, according to Grand View Research’s Conversational AI Market Report. Behind that number is a specific shift in what enterprises are buying: not scripted bots that match keywords to canned responses, but AI assistants that reason over a company’s actual knowledge base and return answers grounded in real internal documents.

That shift is architectural. The scripted bot model breaks when the number of edge cases in a real business environment exceeds what any decision tree can handle. Retrieval-augmented generation — RAG — replaces the decision tree with a retrieval pipeline that pulls relevant source documents at query time, feeds them to a language model, and grounds the answer in content the company actually controls.

This guide covers the architecture decisions, data security requirements, deployment patterns, cost structures, and ROI metrics that determine whether a custom AI chatbot development project reaches production or stalls in pilot.

Why Enterprises Are Investing in Custom AI Chatbot Development Services

The case for custom AI chatbot development services in enterprise settings is no longer being made by innovation teams alone. It is being made by CFOs and operations leaders who can see a direct line between chatbot deployment and labor cost reduction at scale.

custom ai chatbot development services

From Scripted Bots to RAG-Grounded Enterprise Assistants

Scripted bots defined the first generation of enterprise chatbot deployment. They worked well inside narrow, predictable query spaces: password resets, order status lookups, simple FAQ deflection. They stopped working the moment a user asked something the decision tree hadn’t been programmed to anticipate, which, in an enterprise environment with thousands of employees or customers, happens constantly.

Enterprise RAG chatbot architecture addresses that failure mode at the structural level. Instead of matching keywords to pre-written responses, a RAG-grounded assistant retrieves the most relevant passages from a defined knowledge base at the time of each query, passes those passages to a language model as context, and generates an answer that is grounded in current, approved source documents. The chatbot’s answer quality is bounded by the quality of what it retrieves, which makes retrieval pipeline design the most important engineering decision in the project.

The Labor Cost Case for Custom AI Chatbot Development Services

Gartner projected that conversational AI would reduce contact center agent labor costs by $80 billion by 2026, according to a Gartner press release on conversational AI cost impact. That figure reflects deflection at scale: queries that previously required a human agent handled entirely by an AI assistant without agent involvement.

The internal labor cost case for enterprise teams follows the same logic. Support ticket deflection, internal knowledge search, HR policy lookup, and IT helpdesk automation all represent query volumes that currently consume human time. A custom chatbot grounded in the company’s own documentation handles those queries without agent involvement, and unlike a scripted bot, it handles variants and edge cases without requiring a developer to write a new rule for each one. The ROI calculation starts with deflection rate and average handle time, not with feature counts.

Off-the-Shelf Chatbot Builders vs Custom AI Chatbot Development Services

The build-versus-buy question for a chatbot project is not abstract. It resolves quickly once an enterprise team tries to connect a no-code chatbot builder to a proprietary knowledge base that changes regularly, has multi-level access controls, and needs to produce answers the compliance team will sign off on.

Where No-Code Chatbot Builders Fall Short

No-code builders are designed for breadth: they support a wide range of generic use cases and ship fast. The trade-off is depth. Connecting to a proprietary knowledge base with custom indexing logic, applying access controls that scope what each user is allowed to retrieve, and implementing PII redaction before content reaches the language model are all outside the configuration surface of most no-code platforms. The fallback is manually encoding FAQs into the platform, which reintroduces the same maintenance problem that made scripted bots obsolete in the first place.

What Separates Chatbot Projects That Reach Production

MIT NANDA’s “The GenAI Divide” report found that a significant share of enterprise generative AI pilots fail to reach production or deliver measurable P&L impact. The primary failure modes are not model quality issues — they are data integration failures, access control gaps, and user trust problems that surface when a chatbot returns confidently wrong answers it cannot source to an approved document. Custom AI chatbot development services address these failure modes at the architecture level, before deployment, rather than as patches after go-live.

When a Hybrid Approach Makes Sense

A hybrid build, starting with a vendor chatbot platform and layering custom retrieval and orchestration on top, is the practical answer for enterprise teams that have already invested in a platform they are not ready to replace. The vendor platform handles channel management and basic session logic; the custom layer handles retrieval quality, access scoping, and response grounding. This approach shortens the initial build timeline and preserves existing vendor contracts while addressing the knowledge-base retrieval gaps that prevent most off-the-shelf chatbots from reaching production quality.

Use the table below to map the three approaches to your specific situation:

Approach What It Involves Best Fit
No-code chatbot builder Configure a third-party platform with scripted flows and minimal customisation Simple FAQ deflection, fast validation
Custom AI chatbot development services Build RAG retrieval, orchestration, and access control around the company’s own data Customer-facing or internal assistants tied to real knowledge bases
Hybrid build Start with a vendor platform, add custom retrieval and orchestration on top Teams with an existing chatbot that has outgrown its platform

RAG Architecture for Enterprise  Custom AI Chatbot  Development Services

The architecture decisions that determine whether a custom AI chatbot answers from a company’s actual documents, or from the language model’s general training data sit entirely inside the retrieval pipeline. Getting retrieval right is the engineering work that separates a production-ready enterprise assistant from a demo.

custom ai chatbot development services

How Retrieval-Augmented Generation Grounds Chatbot Answers in Your Data

Retrieval-augmented generation works by inserting retrieved document passages into the language model’s context window at query time. The model generates its response based on what it retrieves, not on what it learned during training. Research published at NAACL 2024 by Bechard & Marquez Ayala (ACL Anthology) found that RAG significantly reduces hallucination in real enterprise chatbot applications, meaning that when retrieval finds the relevant source document, the model stops generating content from general training data and grounds its answer in the retrieved text instead.

The critical design point: hallucination reduction is a retrieval quality problem, not a model quality problem. A more powerful language model running against a poorly designed retrieval pipeline will still hallucinate; it will just produce more fluent-sounding hallucinations. Retrieval pipeline design, chunking strategy, embedding model selection, and re-ranking logic all directly determine answer accuracy.

Vector Database and Knowledge Base Design

A vector database stores document chunks as numerical embeddings,  dense vector representations that capture semantic meaning rather than keyword matching. When a user submits a query, the retrieval system embeds the query using the same model, searches the vector store for the nearest document chunks, and returns the most semantically relevant passages. The engineering decisions that matter most at this layer are chunking strategy,  how documents are split before embedding, and the embedding model’s ability to represent domain-specific content accurately.

Most enterprise knowledge bases are not static. Policies change, product documentation updates, and personnel records evolve. The vector store must be designed to reflect those changes, which means incremental indexing pipelines and document versioning are not optional infrastructure. A chatbot trained on stale embeddings produces confidently outdated answers that are harder to catch than obviously wrong ones.

Keeping Answers Current as Source Documents Change

Source document currency is an operational problem as much as an architecture problem. Knowledge base grounding requires that the retrieval index reflects the current state of the company’s documents at all times, not the state they were in on the day the chatbot launched. Automated ingestion pipelines that monitor document repositories, detect changes, re-chunk updated content, and refresh embeddings without manual intervention are the infrastructure layer that keeps a deployed enterprise chatbot from drifting toward stale answers over time.

For regulated industries, financial services, healthcare, and legal, document currency is also a compliance requirement. An answer grounded in a policy that has since been revised is not just a user experience problem. It is a liability exposure that an audit log will surface.

Enterprise Data Security for Custom AI Chatbot  Development Services

The governance gap in enterprise chatbot deployments is predictable: pilots ship fast, access controls are added later, and by the time a security review happens, the chatbot has already touched data it was never supposed to see. Enterprise chatbot data security is an architecture problem that needs to be solved before the first query, not after the first audit.

 architecture

Preventing Shadow AI and Unsanctioned Chatbot Use

IBM’s Cost of a Data Breach Report 2026 identified shadow AI, unsanctioned AI tools used by employees outside formal IT governance, as a growing source of data breach incidents, with a significant share of AI-related breaches missing basic access controls at the point of data retrieval. Shadow AI chatbot risk is not theoretical: employees who cannot get answers from approved internal tools will use consumer AI tools instead, feeding proprietary documents, customer data, and internal communications into systems the company does not control.

The preventive measure is not restriction alone; it is providing a sanctioned alternative that is genuinely useful. A custom AI chatbot that answers accurately from approved knowledge bases removes the incentive to use unsanctioned tools. The security architecture access controls, audit logging, and session isolation exists inside the sanctioned system rather than being bypassed by it.

PII Redaction and Access Control Inside Chatbot Responses

PII redaction in a chatbot access control architecture belongs at the retrieval layer, not the response layer. Redacting sensitive content from the final answer after the language model has already processed it addresses only part of the exposure. If the model ingests a retrieved document chunk containing customer PII before the answer is generated, that data has already entered the model’s context, which creates a logging and compliance risk even when the final response is clean.

Access scoping, limiting what each user can retrieve based on their role, team, and permissions, works on the same principle. The retrieval query must be filtered by the requesting user’s access rights before the vector store is searched, not after results are returned. Row-level security models in the vector database are the standard implementation pattern.

Audit Logging and Compliance Documentation

A SOC 2-compliant chatbot requires audit logs that capture not just that a query occurred, but what source documents were retrieved to generate the answer, which version of those documents was current at query time, and what the user’s access scope was at the time of retrieval. These four requirements form the compliance documentation layer that a security audit or regulatory review will ask for.

Non-negotiable requirements before a custom enterprise chatbot touches company data:

  • Redact or mask PII before it reaches the language model, not just in the final response
  • Scope the chatbot’s data access to what the requesting user is actually permitted to see
  • Chatbot audit logging: log the source documents behind every answer, not just that a query occurred
  • Route any question the chatbot cannot ground in an approved source to a human, instead of letting it guess

Multi-Channel custom AI chatbot Development Services and Integration

A custom AI chatbot that only lives in one channel is solving one problem. Most enterprise deployments require the same underlying assistant to surface across multiple product interfaces, internal tools, and communication platforms, each with its own session management and handoff requirements.

 architecture

Embedding the Chatbot Into Existing Product Surfaces

The chatbot integration layer handles channel-specific rendering: a web widget on the product site, an iframe embed inside a SaaS dashboard, a Slack or Teams integration for internal knowledge access, a WhatsApp channel for customer support. Each surface requires channel-specific session management and UI adaptation, but the retrieval pipeline, access controls, and LLM orchestration layer are shared across all of them. Building that shared core first and treating channel adapters as a separate layer on top is the architectural pattern that makes multi-surface deployment manageable.

Connecting to CRM, Helpdesk, and Internal Systems

An order management system, CRM, or helpdesk integration allows the chatbot to pull live data, not just static documents at query time. A customer support assistant that can retrieve the user’s open ticket history from Zendesk, or the customer’s account status from Salesforce, produces answers that are grounded in current transaction data rather than generalised policy text. These integrations require authenticated API connections with the same access scoping principles that apply to document retrieval: the chatbot queries the CRM on behalf of the requesting user, scoped to what that user is permitted to see.

Handoff to Human Agents When the Bot Hits Its Limits

A custom AI chatbot that cannot ground an answer should not guess. The handoff condition the point at which the chatbot transfers the session to a human agent is an architecture decision, not a UX afterthought. Triggering conditions include: retrieval confidence below a defined threshold, a query category that falls outside the approved knowledge base scope, a user who has explicitly escalated, and any query that touches regulated content the chatbot is not permitted to interpret.

The handoff mechanism must pass session context, the full conversation history, and the retrieval attempts made to the receiving agent. An agent inheriting a handoff with no context starts the interaction from zero, which produces exactly the friction that the chatbot was deployed to reduce.

Cost, Maintenance, and Measuring Custom Chatbot AI Development Service ROI

The cost structure of a custom enterprise chatbot spans build, infrastructure, and ongoing maintenance and the ongoing costs are the ones that most project budgets underestimate. Understanding all three before the first contract is signed is what separates a sustainable deployment from one that gets abandoned six months after launch.

What a Custom Enterprise Chatbot Actually Costs

Build costs for custom AI chatbot development services at the enterprise level typically range from $40,000 to $200,000 depending on scope, data complexity, and integration requirements. A focused internal knowledge assistant with a single document source and one channel sits at the lower end. A multi-channel customer-facing assistant with CRM integration, multi-tenant access scoping, PII redaction, and SOC 2 audit logging sits at the upper end. The variable that has the most impact on build cost is data readiness: how many source systems need ingestion pipelines, how clean the source documents are, and how much custom access control logic is required.

Ongoing Costs: Retraining, Monitoring, and Model Updates

Infrastructure costs post-launch include LLM API consumption, vector database storage and query costs, and embedding refresh compute for document updates. For most mid-market deployments, these run $500 to $3,000 a month depending on query volume and the LLM provider’s pricing tier. Beyond infrastructure, LLM orchestration maintenance, prompt updates as the language model’s behaviour changes across provider versions, retrieval pipeline tuning as the knowledge base grows, and access control updates as org structures change require ongoing engineering time. Plan for 10 to 20 hours of development time per month for a production chatbot with active query volume.

Metrics That Prove the Custom AI Chatbot development service Is Working

Four metrics translate chatbot performance into financial language:

  • Deflection rate — the percentage of queries handled without human escalation, the primary labor cost driver
  • Answer grounding rate — the percentage of responses that cite a specific source document, the proxy for hallucination control
  • User-reported resolution rate — whether the user’s question was actually answered, separate from whether the chatbot gave a confident response
  • Cost per resolved query — total operating cost divided by grounded, resolved queries; the benchmark for comparing against human agent cost

Measuring only deflection rate without answer grounding rate produces misleading ROI figures: a chatbot that deflects 80% of queries but hallucinates 40% of its answers is not a cost reduction it is a liability.

How Tibicle Builds Custom AI Chatbot Development Services

Tibicle’s custom AI chatbot development services are structured around three phases: discovery and architecture planning, implementation with security built in from the start, and post-launch support that keeps the knowledge base current and the retrieval pipeline accurate as the company’s data evolves.

Discovery and RAG Architecture Planning

The discovery phase maps the enterprise’s data landscape before any code is written: which knowledge bases need ingestion pipelines, what the access control model looks like across user roles, which channels the chatbot needs to surface on, and what the compliance requirements are for the industry and data types involved. The output of discovery is a RAG architecture specification: chunking strategy, embedding model selection, vector store design, re-ranking logic, and orchestration framework that the build phase implements against. Skipping discovery and going straight to a build phase is the most common reason enterprise chatbot projects miss their production quality targets.

Implementation With Security and Access Control Built In

Tibicle’s implementation approach treats enterprise chatbot data security as a first-class engineering requirement rather than a post-launch configuration task. PII redaction is implemented at the retrieval layer. Access scoping is applied before the vector store query, not after. Audit logging captures source documents at the time of retrieval, not just query events. The result is a chatbot that arrives at its compliance review with the access control architecture already in place, rather than requiring a security retrofit before it can go live with sensitive data.

For teams evaluating how a custom build compares to their current stack, Tibicle’s approach to enterprise RAG chatbot architecture integrates with existing CRM, helpdesk, and identity management systems rather than requiring a wholesale infrastructure replacement.

Ongoing Support and Knowledge Base Maintenance

A custom AI chatbot is not a static deployment. As the company’s knowledge base evolves new policies, updated product documentation, personnel changes the retrieval index needs to stay current. Tibicle’s post-launch support covers automated ingestion pipeline monitoring, embedding refresh scheduling, prompt updates as LLM provider versions change, and retrieval quality reviews that catch drift before it affects answer accuracy in production.

The support model is designed for teams without a dedicated AI engineering function: structured monthly reviews, defined escalation paths for retrieval quality issues, and access to the same engineering team that built the system rather than a tiered support queue that has no context on the original architecture.

Key Takeaways for Enterprise Teams

Custom AI chatbot development services succeed or fail on retrieval quality, not on which language model generates the final answer. The most important engineering decisions in a chatbot project sit inside the retrieval pipeline: chunking strategy, embedding model, access scoping, and re-ranking logic.

  • No-code chatbot builders rarely survive contact with a real knowledge base; most stall before production because they cannot implement the access controls and PII redaction a compliance team requires
  • PII redaction and access scoping belong inside the retrieval pipeline, not bolted onto the response afterward
  • A chatbot that cannot ground an answer should hand off to a human, not guess
  • Measure answer grounding rate alongside deflection rate; hallucination reduction is the metric that determines whether the chatbot is actually reducing liability or just shifting it

Ready to scope a custom AI chatbot for your enterprise? Book a discovery call with Tibicle’s team; the session maps your knowledge base, access requirements, and deployment channels before any architecture decisions are made.

Frequently Asked Questions

What are custom AI chatbot development services, and how are they different from a chatbot builder platform?

Custom AI chatbot development services build the retrieval pipeline, access control layer, and LLM orchestration logic around a company’s specific knowledge base and compliance requirements. A chatbot builder platform provides a configurable interface for scripted flows and generic FAQ deflection. The structural difference is retrieval: a custom-built assistant retrieves answers from the company’s own documents at query time; a platform bot returns pre-written responses that must be manually maintained.

How does RAG architecture reduce hallucination in an enterprise chatbot?

Retrieval-augmented generation reduces hallucination by inserting retrieved source documents into the language model’s context window before the answer is generated. The model produces its response based on what it retrieves, not on general training data. Research from NAACL 2024 confirms this approach significantly reduces hallucination in real enterprise applications. The mechanism: when a relevant source document is retrieved, the model uses it; when no relevant document is found, a well-designed system routes the query to a human instead of guessing.

What data security measures does an enterprise chatbot need before it can access company data?

At minimum: PII redaction at the retrieval layer before content reaches the language model, role-based access scoping applied before the vector store is queried, audit logging that captures source documents behind every answer, and a defined handoff protocol for queries the chatbot cannot ground in approved content. For regulated industries, SOC 2 audit trail requirements apply to the logging architecture as well.

Can custom AI chatbot development services integrate with our existing CRM or helpdesk software?

Yes. Integration with Salesforce, HubSpot, Zendesk, Freshdesk, and similar platforms is a standard component of enterprise chatbot architecture. The integration layer pulls live CRM or ticket data at query time — scoped to the requesting user’s access rights — and combines it with document retrieval to produce answers grounded in both static knowledge and current transactional data.

How much does a custom AI chatbot development services cost to build and maintain?

Build costs typically range from $40,000 to $200,000 depending on data source complexity, channel count, and access control requirements. Ongoing infrastructure costs run $500 to $3,000 per month at mid-market query volumes, plus 10 to 20 hours of development time per month for pipeline maintenance and retrieval quality monitoring.

Does Tibicle build custom AI chatbots development services with RAG architecture and enterprise data security?

Yes. Tibicle’s custom AI chatbot development services cover the full delivery scope: discovery and RAG architecture planning, implementation with PII redaction and access control built in from the start, multi-channel deployment, and post-launch support that keeps the knowledge base current as the company’s data evolves. Every engagement starts with a structured discovery session that maps data sources, access requirements, and compliance obligations before any architecture decisions are made.

Custom Computer Vision Software Development Company

Who this is for: Engineering leads, product owners, and operations heads at B2B enterprises evaluating a custom computer vision software development company for a real visual-data workflow rather than a demo.

Search intent: Commercial evaluation with a technical backbone. The reader has moved past “what is computer vision” and wants architecture choices, accuracy data, and a build-vs-buy comparison before briefing a vendor.

What you will walk away with: What a production computer vision and multimodal AI build actually requires, current market and accuracy data from Gartner, Grand View Research, and a UC-affiliated benchmark study, a build-vs-buy comparison table, and how Tibicle structures custom computer vision and multimodal AI application development for B2B enterprise.

computer vision software development company

Introduction

A custom computer vision software development company builds systems that read pixels and turn them into business decisions. It does not just label a photo and stop there. Gartner projects that 80% of enterprise software and applications will be multimodal by 2030, up from less than 10% in 2024. That shift changes what a B2B enterprise actually needs from a computer vision software development company. 

A generic vision API can tag a photo. However, a production system has to do more. For example, it must catch a hairline defect on a moving line, read a document buried inside a video frame, or flag an anomaly in real time. In addition, it then has to route that decision to the right person or system, without a human reviewing every frame. The gap between a vision demo and a system an enterprise can run in production sits in the architecture, not the model. 

Therefore, that means data pipelines, fusion across image, text, and sensor inputs, and a deployment plan that respects where the data can live. This guide covers what custom computer vision and multimodal AI development actually requires, and where it creates real enterprise value. It also covers why general-purpose vision APIs fall short on domain-specific data. And it covers how Tibicle structures custom computer vision and multimodal AI application development for B2B enterprise.

Why B2B Enterprises Need a Custom Computer Vision Software Development Company, Not a Vision API

computer vision software development company

From Single-Purpose Vision APIs to Multimodal Enterprise Systems

A stock vision API returns labels: this is a box, this is a face, this is a forklift. A B2B enterprise workflow needs more context than that. It needs to combine what a camera sees with what a sensor reports, what a document says, and what a business rule requires. It then acts on all three together. That combination is what multimodal AI application development actually means in practice. It is also why a computer vision software development company builds a pipeline, not a single model call.

The Market Shift Behind This Demand

Enterprise investment in visual AI is accelerating in a way that reflects this shift. Grand View Research values the global computer vision market at $23.6 billion in 2025. The firm projects growth to $28.2 billion in 2026 and $101.5 billion by 2033, a 20.1% compound annual growth rate. It attributes a meaningful share of that growth to the move toward multimodal AI models. These models combine visual, textual, and contextual data for more accurate analysis. A computer vision software development company sits right at that intersection. It builds the fusion layer generic tools do not provide out of the box.

What Custom Computer Vision Software Development and Multimodal AI Actually Requires

Data Pipelines: Capture, Labeling, and Model Training

A production vision system starts with a data pipeline, not a model. Cameras or sensors capture raw footage. A labeling process marks what matters for the specific task. A training loop then fine-tunes a model against that labeled set. Skipping the labeling step and relying on a general pretrained model instead is the single most common reason a computer vision pilot never reaches production.

Fusing Vision With Text, Sensor, and Structured Data

Multimodal AI application development means combining an image with the data around it. Think a timestamp, a sensor reading, a work order number, or a compliance rule stored as text. A system that flags a defect but cannot tie it to the right batch record only does half the job. The fusion layer, not the vision model alone, makes the output usable by another system or person.

Edge vs Cloud Custom Computer Vision Software Development Inference for Real-Time Decisions

A quality-control camera on a production line cannot wait on a round trip to a cloud API when the line moves faster than that latency allows. Edge inference keeps the decision local and fast. Cloud inference trades some latency for easier updates and more compute. A computer vision software development company picks this split based on the actual line speed and network reliability, not by default.

Where Custom Computer Vision Software Development Creates Enterprise Value: Manufacturing, Healthcare, and Retail

computer vision software development company

Manufacturing: Defect Detection and Quality Control

Manufacturing and IT functions report measurable cost benefits from AI use cases. Quality control and predictive maintenance are consistently among the strongest, according to McKinsey’s 2025 State of AI survey. A camera on the line that catches a surface defect before it reaches packaging replaces a manual inspection step. That manual step scales poorly and tires over an eight-hour shift. Tibicle’s IoT & Smart Solutions work covers the sensor and real-time monitoring layer this kind of inspection system depends on.

Healthcare: Medical Imaging and Diagnostic Support

Medical imaging is the single largest category of FDA-authorized AI and machine learning medical devices. A 2024 analysis found the agency cleared 168 machine-learning-enabled Class II devices that year. Radiology accounted for roughly 74% of them. That concentration reflects how mature computer vision has become for structured image analysis. It also reflects how much regulatory scrutiny a healthcare-facing build has to clear before launch. Tibicle’s HealthTech industry work covers this compliance layer directly.

Retail and Logistics: Shelf Monitoring and Inventory Accuracy

A camera that reads shelf gaps, verifies planogram compliance, or counts inventory at a dock door removes a manual audit step. That manual audit otherwise happens once a day at best. Tibicle’s Retail & E-Commerce work applies this same computer vision and multimodal AI pattern to shelf and inventory monitoring.

General-Purpose Multimodal APIs vs a Custom Computer Vision Software Development Company

Development

Where General-Purpose Vision APIs Are the Right Call

A general-purpose multimodal API handles common, well-represented tasks well: reading a receipt, tagging a product photo, moderating uploaded images. For those tasks, building custom is rarely worth the cost.

Why Accuracy Drops on Domain-Specific Visual Data

Accuracy drops fast once the task moves to specialized visual data the model never trained on. The MMAD benchmark tests multimodal large language models on industrial anomaly detection. Researchers built it specifically for that purpose. It found that GPT-4o, the strongest commercial model tested, reached only 74.9% average accuracy across defect and anomaly questions. The researchers note this falls far short of what industrial inspection actually requires. General-purpose models train on broad internet imagery, not the specific texture of a welded seam or a printed circuit board. That gap does not close on its own.

The Case for a Custom Computer Vision Software Development Build

A computer vision software development company closes that gap. It fine-tunes on the enterprise’s own visual data instead of relying on a general-purpose model’s out-of-the-box accuracy.

Factor General-Purpose Vision APIs Custom Computer Vision Development
Setup speed Live in days Live in weeks, scoped to the specific visual task
Accuracy on domain data Drops on specialized or unfamiliar imagery Fine-tuned on the enterprise’s own labeled data
Data control Images often processed through the vendor’s cloud Data and models stay inside your infrastructure by design
Latency Depends on network round trip Can run at the edge for real-time decisions
Cost at scale Per-call fees grow with image volume Fixed build cost, no recurring per-call fee
Best fit Common, well-represented visual tasks Specialized, regulated, or high-volume visual workflows

For workflow bots that need to run on a user’s own machine, the same architecture questions apply to a desktop shell rather than a browser tab. Tibicle’s guide on running local LLMs in Electron covers the process-model constraints that shape an on-device agent build.

Data Privacy, Compliance, and Governance for Visual and Biometric Data

When Visual Data Becomes Regulated Biometric Data

Not every image is ordinary personal data. Under GDPR, facial recognition footage at an access point counts as biometric data. This kind of footage falls under Article 9’s special category rules (ICO). Those rules carry a higher legal bar than standard personal data. A computer vision software development company needs to know which parts of a visual pipeline cross that line. That scoping has to happen before the first camera goes live, not after.

On-Prem and Edge Deployment for Sensitive Computer Vision Software Development Data

Keeping inference on-site or at the edge is often the simplest way to reduce this exposure. It beats routing every frame through a third-party cloud API. It also removes a dependency on an external vendor’s uptime for a workflow that cannot pause.

Human Review Checkpoints for High-Stakes Visual Decisions

Any visual decision with legal, safety, or diagnostic consequences needs a human checkpoint before it becomes final. A confidence score attached to an automated action is not enough on its own. Building that checkpoint into the workflow from day one costs far less than retrofitting it after an incorrect automated decision.

Common Reasons Custom Computer Vision Software Development Projects Fail to Reach Production

The pattern behind stalled computer vision projects repeats across industries:

  • The pilot used a small, clean dataset that does not reflect real production conditions, lighting, or camera angles
  • No labeling pipeline existed to keep the training data current as the visual task changed
  • The team evaluated the model on accuracy alone, without a plan for what happens when confidence is low
  • The team discovered edge or latency requirements only after building the cloud-based architecture
  • The team identified biometric or regulated visual data only after the system had already started collecting it

How Tibicle Delivers Custom Computer Vision Software Development and Multimodal AI Development

Development

Data and Model Scoping

Tibicle starts by auditing the actual visual task. That includes what the camera or sensor captures today, and what a labeled dataset needs to include. It also covers whether the workflow needs edge inference or can run in the cloud. This scoping stage draws on Tibicle’s AI & Automation Consulting practice.

Build: Model Training, Fusion, and Integration

The build phase fine-tunes a vision model against the enterprise’s own data. It also fuses that model with the text, sensor, and structured inputs the workflow depends on. Tibicle delivers this through its AI Development and Integration services.

Deployment and Monitoring

After launch, Tibicle monitors accuracy against production data, not just the original test set. The team retrains the model as the visual task or environment drifts.

Conclusion

A custom computer vision and multimodal AI system earns its cost once three things start to matter more than demo speed. Those three things: accuracy on real production data, latency, and data governance. All three come down to architecture decisions a team makes before training starts. Building a computer vision system for a real enterprise workflow? Talk to the Tibicle team.

Frequently Asked Questions

What does a custom computer vision software development company actually build, compared to a vision API?
A vision API returns labels for a single image. A computer vision software development company builds the full pipeline instead. That pipeline covers data capture, labeling, model training, fusion with other data sources, and deployment tuned to the enterprise’s latency and compliance needs.

How accurate are general-purpose multimodal AI models on specialized enterprise visual tasks?
Benchmark research on industrial anomaly detection found the strongest commercial multimodal model reached only 74.9% accuracy. That falls well short of what industrial inspection requires. This gap is why domain-specific fine-tuning matters for specialized visual tasks.

Does custom computer vision software development need to run on-site instead of through a cloud API?
It depends on latency and data sensitivity. Real-time production-line decisions often need edge or on-prem deployment. So does regulated visual data, such as biometric identification, rather than a round trip to a cloud API.

What industries get the most value from custom computer vision software development?
Manufacturing, healthcare, and retail show the clearest documented value today, covering defect detection, medical imaging analysis, and shelf or inventory monitoring.

When does visual data become regulated biometric data for custom computer vision software development?
Under GDPR, facial recognition footage at an access point counts as biometric data. Article 9’s special category rules cover this kind of data. Those rules require a stronger legal basis than ordinary personal data.

Does Tibicle offer custom computer vision software development and multimodal AI development for B2B enterprises?
Yes. Tibicle builds custom computer vision and multimodal AI applications for enterprise clients, covering data pipeline design, model fine-tuning, fusion with existing systems, and post-launch monitoring.

Cross-Platform Desktop Application Development: Electron

What This Guide Covers

Who this is for: SaaS companies, enterprise product teams, CTOs, engineering leaders, and product managers evaluating cross platform desktop application development for Windows, macOS, and Linux.

Search intent: Implementation and decision. This guide explains why Electron remains a practical cross-platform desktop Application Development for enterprise SaaS, where it fits against native development, Tauri, and .NET MAUI, and which architecture decisions matter before deployment.

What you will walk away with: A practical view of Electron’s business and technical advantages, including one-codebase development, talent availability, release speed, enterprise integrations, security, offline workflows, and long-term application management.

cross platform desktop application development

Introduction

The global cross-platform software market is projected to grow from $104.6 billion in 2025 to $121.04 billion in 2026, representing a 15.7% CAGR, according to The Business Research Company. The report also identifies unified codebase development and enterprise cross-platform solutions among the trends shaping the market.

For SaaS companies, the approach is straightforward: why maintain three separate desktop codebases when one can serve Windows, macOS, and Linux?

Native development still has situations where it makes sense, particularly for deeply platform-specific software. But for enterprise SaaS products, the ability to reuse application logic, frontend skills, testing workflows, and release processes can change the economics considerably.

Electron packages Chromium and Node.js into a desktop application, allowing teams to use JavaScript, HTML, and CSS while targeting Windows, macOS, and Linux from one codebase. 

The Enterprise Case for Cross-Platform Desktop Application Development in 2026

Desktop software is returning to SaaS roadmaps because browser applications do not always provide the operating-system integration or offline reliability that enterprise users need.

The broader application development software market is also expanding rapidly. Fortune Business Insights projects the market to grow from $172.94 billion in 2026 to $826.48 billion by 2034, with North America holding a 33.60% share in 2025.

Why SaaS Companies Are Adding Desktop Clients Again

A desktop client can provide capabilities that are harder to reproduce consistently inside a browser tab.

Common reasons include:

  • Offline access for field or remote teams with unreliable internet
  • Deeper operating system integration through system trays, notifications, and keyboard shortcuts
  • Higher engagement than a browser tab competing with dozens of others
  • Lower support load through automatic updates instead of manual refreshes

For productivity software, developer tools, communication platforms, and internal enterprise systems, these capabilities can make a dedicated desktop experience worth maintaining alongside the web application.

What “Enterprise-Grade” Actually Requires From a Desktop App

Enterprise software needs more than a packaged application that launches successfully.

A production desktop client should support:

  • Security review covering code signing, sandboxing, and a documented update process
  • Uptime and support commitments aligned with the SaaS contract
  • Compatibility across company-managed Windows, macOS, and Linux devices
  • Centralized deployment through IT rather than individual downloads

Electron provides the foundation, but these operational requirements need to be designed around the product before deployment.

Why Electron Leads Cross-Platform Desktop Application Development for SaaS Teams

cross platform desktop application development

Electron’s main advantage is not simply that it uses JavaScript. It combines a familiar web development environment with a desktop runtime built around Chromium and Node.js.

That gives SaaS teams a way to reuse frontend skills and application logic while adding desktop-specific capabilities.

Cross-Platform Desktop Application Development With One Codebase

Electron allows developers to maintain one JavaScript codebase while creating applications for Windows, macOS, and Linux. This is one of its strongest advantages for SaaS companies supporting multiple enterprise environments.

Instead of maintaining separate application architectures for each operating system, teams can share much of the interface, business logic, testing, and release process.

Platform-specific code is still sometimes required, but the overall development model remains unified.

The Chromium and Node.js Architecture Enterprise Teams Already Trust

Electron embeds Chromium and Node.js into its application runtime. Chromium provides the rendering environment, while Node.js gives applications access to the broader JavaScript ecosystem and desktop capabilities.

This matters for enterprise teams because developers can use familiar web technologies, npm packages, TypeScript, React, testing tools, and established CI/CD workflows.

The result is a desktop architecture that feels closer to the SaaS stack teams already know.

Cross-Platform Desktop Application Development and Faster Release Cycles

A shared codebase can simplify the release process when the same feature needs to reach every supported platform.

The practical benefits include:

  • One QA cycle instead of three
  • One changelog and version number across platforms
  • Faster patch turnaround when a security fix needs to reach every user

Cross-platform desktop application development research cited by Research2Guidance indicates that cross-platform tools can save more than 30% of development time compared with native development.

The exact saving varies by application, but reducing duplicated platform work remains one of Electron’s strongest business arguments.

Why US SaaS Leaders Choose Electron for Cross-Platform Desktop Application Development

cross platform desktop application development

Technology decisions at enterprise scale are influenced by more than framework capabilities.

Hiring availability, development costs, existing engineering skills, and the availability of proven production applications all affect whether a framework is practical for a growing SaaS company.

Talent Availability: JavaScript Teams vs OS-Specific Specialists

JavaScript remains one of the most widely used technologies among professional developers. The 2025 Stack Overflow Developer Survey reports JavaScript usage at 68.8% among professional developers.

That matters when SaaS companies need to build or expand a desktop engineering team.

An organization can often reuse developers familiar with React, Node.js, TypeScript, and web tooling rather than building separate teams around Swift, Objective-C, C++, and Windows-specific technologies.

The larger talent pool can reduce hiring friction and simplify long-term maintenance.

Cross-Platform Desktop Application Development Cost Per Platform

The biggest cost advantage of Electron comes from reducing duplicated engineering work.

A native strategy may require separate implementation, testing, release, and maintenance work across multiple operating systems. Cross-platform development can centralize much of that effort.

Research2Guidance data cited by industry analysis indicates that cross-platform tools can save more than 30% of development time compared with native approaches.

For a small application, that difference may be modest. Across a multi-year SaaS roadmap with frequent releases, the savings can become significant.

Enterprise Products Already Running on Electron

Electron’s production ecosystem is one reason enterprise teams are comfortable evaluating it.

Product Company Primary Use Case
Microsoft Teams Microsoft Enterprise communication and collaboration
Postman Postman Inc. API development and testing
GitHub Desktop GitHub Source control client for engineering teams

Electron’s official showcase lists Microsoft Teams, Postman, and GitHub Desktop among applications built with Electron.

The broader application development software market also has a strong North American presence. Fortune Business Insights reports that North America accounted for 33.60% of the application development software market in 2025.

Core Architecture Decisions for Cross-Platform Desktop Application Development

application

Choosing Electron is only the starting point.

Enterprise applications need an architecture that addresses security, performance, offline workflows, packaging, updates, and long-term maintenance before the application reaches thousands of managed devices.

Security, Code Signing, and Auto-Update Pipelines

A desktop application can execute code directly on a user’s machine, so its distribution pipeline needs strong controls.

Enterprise teams should consider code signing certificates, sandboxed renderer processes, restricted privileges, secure IPC, and a documented update process.

Electron’s security guidance recommends practices such as context isolation, sandboxing, secure content, and keeping Electron current. Packaging and publishing can also be managed through tools such as Electron Forge.

Performance Optimization for Chromium-Based Apps at Scale

Chromium provides a consistent rendering environment, but enterprise applications still need careful performance engineering.

Common practices include:

  • Lazy-loading views instead of rendering the full interface at launch
  • Limiting the number of active renderer processes per window
  • Offloading heavy computation to native modules written in C++ or Rust where needed

The goal is not to avoid Chromium. It is to ensure that the application uses its resources deliberately as the feature set grows.

Cross-Platform Desktop Application Development for Offline-First Data Sync

Enterprise teams working in remote offices, field locations, or unreliable networks may need applications that continue operating without constant connectivity.

An offline-first architecture should define what data is cached, how changes are synchronized, how conflicts are handled, and when local information expires.

The design should also consider encryption and authentication so offline functionality does not become an uncontrolled local data store.

Electron vs Tauri vs .NET MAUI

Framework Typical Install Size Talent Pool Best Enterprise Fit
Electron Larger, since Chromium ships with every app Largest, JavaScript and React developers SaaS dashboards, productivity tools, internal platforms
Tauri Smaller, uses the operating system’s native WebView Smaller, requires Rust for native modules Lightweight utilities, security-conscious teams
.NET MAUI Smaller on Windows, native UI per platform Moderate, C# and .NET developers Windows-first enterprise tools with cross-platform needs

The right choice depends on the application’s performance requirements, existing engineering team, operating-system targets, and product roadmap. Electron is strongest when web technologies and a broad talent pool are priorities.

Connecting Enterprise Systems to Cross-Platform Desktop Application Development

Enterprise desktop applications rarely operate as isolated products.

They often need to connect with identity platforms, internal APIs, legacy systems, cloud services, and other business infrastructure.

SSO and Identity Management

Enterprise users expect desktop applications to work with the same identity systems used elsewhere in the organization.

SSO can connect the application to providers such as Microsoft Entra ID, Okta, or other enterprise identity platforms. The architecture should handle authentication securely while allowing organizations to apply centralized access policies.

Connecting to Internal APIs and Legacy Systems

A desktop application may need to communicate with internal REST APIs, GraphQL services, databases, or older enterprise systems.

The desktop client should not become a replacement for the organization’s security layer. Sensitive operations should remain protected by backend authorization, while the client uses secure authentication and controlled API communication.

Data Compliance Considerations for US and EU Teams

Enterprise SaaS products operating across regions may need to consider different requirements for data handling, retention, access, and residency.

US and EU deployments can therefore require different policies even when the desktop application is largely identical.

The architecture should identify where data is processed, where local information is stored, which services receive it, and what controls apply to each deployment environment.

Addressing the Common Enterprise Objections to Electron

Electron is not the right choice for every desktop application.

Enterprise reviewers commonly question resource usage, security, and long-term version management. These concerns are valid, but they can be addressed through architecture and operational discipline.

Memory and Resource Usage at Scale

Chromium adds runtime overhead compared with a lightweight native application.

For enterprise applications, the answer is usually optimization rather than abandoning Electron. Teams can reduce unnecessary renderer work, lazy-load large views, manage background processes carefully, and avoid loading the entire product at startup.

Electron’s architecture also provides access to performance tooling that can help identify memory leaks and expensive operations before they become production problems.

Reducing the Security Surface Area

Electron applications need active security maintenance because they combine a browser engine with desktop capabilities.

Teams should focus on:

  • Staying current on Electron version updates
  • Disabling Node.js integration in renderers that do not need it
  • Maintaining a documented patch process tied to CVE monitoring

Electron’s security guidance specifically recommends context isolation, sandboxing, secure content, current versions, and careful control of IPC and navigation.

Long-Term Version Management Across Windows, macOS, and Linux

Supporting three operating systems does not mean ignoring their differences.

Teams still need to manage OS-specific packaging, signing certificates, permissions, installers, update channels, and testing.

The advantage is that the core application can remain shared while platform-specific requirements are isolated where necessary.

That makes long-term maintenance more manageable than maintaining three completely separate product architectures.

How Tibicle Plans and Delivers Cross-Platform Desktop Application Development Projects

application

Enterprise desktop development requires more than converting an existing web application into a desktop package.

Tibicle approaches Electron projects around the product requirements, architecture, user workflows, and deployment environment.

Discovery, Architecture, and UI/UX Planning

We begin by understanding the existing SaaS product, target operating systems, user workflows, integrations, offline requirements, and enterprise security expectations.

The architecture is then planned around Electron’s process model, APIs, authentication, data handling, packaging, and update requirements.

Development, QA, and Packaging Across Operating Systems

Development focuses on reusable application components while isolating platform-specific behavior where necessary.

QA covers Windows, macOS, and Linux builds, including application functionality, integrations, packaging, permissions, performance, and update behavior.

Electron’s tooling supports packaging applications and generating platform-specific installers for distribution.

Deployment, Monitoring, and Long-Term Support

Launching the application is only one part of the project.

Tibicle can support deployment workflows, application updates, monitoring, bug fixes, performance improvements, dependency upgrades, and ongoing feature development as the desktop product evolves.

The goal is to create a maintainable desktop application that continues to fit the SaaS product as its user base grows.

Key Takeaways for SaaS and Enterprise Teams

  • One codebase: Electron supports Windows, macOS, and Linux with shared development.
  • Broader talent pool: JavaScript skills make hiring and maintenance easier.
  • Faster releases: Cross-platform development reduces duplicated engineering work.
  • Native has its place: Platform-specific needs may still justify native development.
  • Enterprise-ready: Security, signing, updates, deployment, and maintenance should be planned from the start.

Ready to build your enterprise cross-platform desktop application? Book a call with Tibicle.

FAQs

What does cross platform desktop application development mean for enterprise SaaS products?
It means building one desktop application architecture that can run across operating systems such as Windows, macOS, and Linux. For SaaS companies, this can reduce duplicated development work while providing users with a dedicated desktop experience and operating-system integration.

Is Electron secure enough for enterprise cross platform desktop application development?
Electron can be used for enterprise applications when security is designed into the architecture. Teams should follow Electron’s security practices, including context isolation, sandboxing, secure content loading, controlled IPC, current Electron versions, code signing, and a documented update process.

How much does Electron app development cost compared to native apps?
There is no fixed percentage because cost depends on application complexity, integrations, operating systems, security requirements, and team structure. Cross-platform research cited by Research2Guidance indicates that cross-platform tools can save more than 30% of development time compared with native development, mainly by reducing duplicated platform work.

Can an Electron desktop app connect to enterprise systems like SSO and internal APIs?
Yes. Electron applications can integrate with enterprise identity providers, SSO systems, REST APIs, GraphQL services, internal platforms, and legacy systems. The important consideration is keeping authentication, authorization, and sensitive business logic protected rather than relying solely on the desktop client.

How long does it take to build an enterprise-grade Electron desktop application?
The timeline depends on the product scope. A lightweight internal desktop utility can take significantly less time than a multi-platform SaaS client with SSO, offline synchronization, enterprise integrations, automated updates, and security requirements. Discovery and architecture planning are important for producing a realistic estimate.

Does Tibicle handle Electron desktop application projects end to end?
Yes. Tibicle can support Electron projects from discovery and architecture through UI/UX, development, cross-platform QA, packaging, deployment, updates, monitoring, and ongoing maintenance. The exact delivery model depends on the application’s requirements, existing SaaS infrastructure, and target operating systems.

The Product Manager’s Guide to Electron Enterprise App Distribution (MSI, DMG, and Apple Notarization)

What This Guide Covers

Who this is for:
Product Managers, engineering leads, and founders shipping for desktop Electron enterprise app distribution customers, and who need to plan Windows and macOS packaging, code signing, and Apple notarization into a release timeline instead of leaving it to engineering the week before launch.

Search intent:
Informational and planning. This guide is for PMs who already know an enterprise release needs an MSI installer, a signed DMG, and Apple notarization, but want a clear picture of what each approval actually requires, how long it takes, and where it belongs on a project timeline. Instead of a general Electron packaging tutorial, it breaks distribution into the certificates, approvals, and deployment channels a PM needs to plan for.

What you will walk away with:
A practical breakdown of MSI and DMG packaging requirements, the Apple notarization process and its typical turnaround time, what a Windows EV code signing certificate costs the release calendar, how enterprise IT departments deploy Electron apps through Intune, SCCM, and Jamf, and a sample release timeline you can adapt for your own launch.

electron enterprise app distribution

Introduction

The application development software market is on track to grow from $172.94 billion in 2026 to $826.48 billion by 2034, a compound annual growth rate of 21.60%, according to Fortune Business Insights. Enterprise buyers evaluating that growing pool of software now expect a desktop app to install through their existing IT tooling, not through a downloaded .exe that triggers a security warning. Electron enterprise app distribution is not a packaging afterthought. It is a roadmap item with its own approvals, lead times, and dependencies, and a PM who plans for it early avoids the most common reason enterprise launch dates slip. This guide walks through MSI packaging, DMG and notarization on macOS, certificate planning, enterprise deployment channels, and a release timeline you can build your own launch calendar around.

Why Distribution Planning Belongs on a Product Manager’s Roadmap

Electron app packaging for enterprise involves more approvals than a consumer download link. A Windows build needs an MSI installer that enterprise IT can push silently. A macOS build needs a Developer ID signature and a notarization ticket from Apple before Gatekeeper lets it run without warnings. Neither of those steps sits inside a normal sprint. They depend on external parties: a certificate authority, Apple’s notary service, and the customer’s own IT review process. When a PM treats them as engineering’s problem to solve at build time, the approvals surface late, and the launch date moves to absorb them.

What Happens When Distribution Is Planned Too Late

A team that discovers the EV certificate requirement during release week loses one to three weeks waiting on issuance. A team that submits for Apple notarization without testing the hardened runtime setting gets a rejection, then resubmits, then waits again. Each of these delays is avoidable on its own, but stacked together in the final week before launch, they routinely push a release by two to four weeks. The fix is not more engineering effort. It is moving the certificate and notarization steps onto the project plan months earlier.

The Three Approvals a Desktop Release Needs Before Launch

Every enterprise Electron release clears three separate approvals: a code signing certificate for each platform, Apple’s notarization for macOS, and the customer’s own IT review before rollout. The first two are vendor-side and largely under the PM’s control once budgeted for. The third depends on the customer’s procurement and security review cycle, and it is often the longest of the three. Treating all three as roadmap items, with owners and lead times attached, keeps distribution off the critical path instead of becoming it.

Windows Distribution: Building an MSI Installer for Enterprise IT

electron enterprise app distribution

A standard .exe installer works for an individual downloading an app on their own machine. It does not work for an IT department managing thousands of endpoints. Enterprise IT departments deploy software through management tools that expect a specific installer format, predictable exit codes, and silent operation. That format is the Windows Installer package, commonly called an MSI.

MSI vs a Standard .exe Installer

Microsoft’s own documentation describes Windows Installer as an installation and configuration service built into Windows that gives customers better corporate deployment and a standard format for managing software components. A raw .exe installer does not offer that standard format. It can bundle any installation logic the developer chooses, which means IT tools cannot reliably predict how it behaves, whether it can run silently, or how to detect a completed install. An MSI exposes a consistent structure that management tools can query, repackage, and deploy the same way across every application in the fleet.

What Enterprise IT Actually Checks in an MSI Package

Before approving a rollout, IT administrators check that the MSI installs and uninstalls without a UI prompt, that it exposes a proper product code and version number for detection rules, that it supports per-machine installation for shared devices, and that it does not require a restart mid-install. These checks exist because IT teams manage installs at scale through scripts and policies, not by clicking through a wizard on each device. An MSI that fails any of these checks gets rejected during IT review, which is exactly the kind of delay a PM wants to catch before it reaches the customer.

Building an MSI From an Electron App

Electron does not produce an MSI by default. Teams typically use electron-builder or Electron Forge with a WiX-based maker to generate the MSI from the packaged app, then sign the resulting installer as a separate step from signing the app binary itself. The build pipeline needs to produce both artifacts, the signed app and the signed installer, before either reaches an IT admin for testing. Budgeting engineering time for this pipeline setup, rather than assuming the default Electron build output is enterprise-ready, is one of the simplest ways to avoid a late surprise.

macOS Distribution: DMG Packaging and the Apple Notarization Process

electron enterprise app distribution

macOS distribution follows a different path than Windows, but it carries the same lesson: the approval step is not optional, and it has its own timeline.

DMG vs PKG: Choosing a macOS Distribution Format

A DMG is a disk image that a user mounts and drags into their Applications folder. A PKG is a guided installer that can run scripts and place files in system locations beyond a single drag-and-drop. Most Electron apps distribute as a DMG because the app is self-contained and does not need install-time scripting. Enterprise deployment through Jamf Pro can wrap either format, but a DMG keeps the packaging simpler for teams that do not need PKG’s install-time scripting.

What Apple Notarization Actually Checks for electron enterprise app distribution

Apple’s own documentation describes notarization as a way to give users confidence in macOS software distributed outside the Mac App Store, by submitting it for an automated security scan before release. The notary service checks the binary for known malware signatures, confirms the code signature is valid and complete, and verifies the app was built with security protections enabled. A notarized app carries a ticket that Gatekeeper checks the first time the app runs, either online or from a locally stapled copy, before letting it open without a warning.

How Long Notarization Takes and What Blocks It

Apple’s automated scan usually completes in minutes, though it can take longer during periods of high submission volume, and Apple has noted that unpublished software processed through Xcode’s export flow typically finishes in under an hour. Submissions get rejected, not delayed, when a requirement is missing. Build the following into the release checklist so a rejection does not happen the week of launch:

  • A Developer ID certificate and an active Apple Developer Program membership
  • The hardened runtime enabled at build time
  • A secure timestamp included with the code signature
  • Stapling the notarization ticket to the app after approval

Code Signing Certificates: What a PM Needs to Budget and Plan For

Certificates are the part of Electron enterprise app distribution most likely to catch a PM off guard, because the cost and lead time changed significantly in recent years.

Windows EV Code Signing Certificates

Electron’s own documentation states that Microsoft has required software to be signed with an extended validation, or EV, code signing certificate since June 2023, replacing the older and cheaper authenticode certificates that Windows now treats as unsigned. EV certificates must live on a hardware storage module or a cloud-based signing service rather than a downloadable file, which changes how a CI pipeline handles signing and adds a procurement step most teams have not budgeted for before their first enterprise release.

Apple Developer Program Enrollment and Renewal

An Apple Developer Program membership is required for both code signing and notarization on macOS, and it renews annually. Enrollment for an existing account with documents ready typically completes in a day or two, but a new organization enrollment can take longer while Apple verifies the business. A PM shipping a first macOS enterprise release should confirm enrollment status months ahead of the target date, not weeks.

Building Certificate Lead Time Into the Release Calendar

Certificate issuance is the single easiest distribution delay to remove from a launch timeline, because it does not depend on the app itself being finished. A Windows EV certificate can take one to three weeks to issue depending on the vendor and verification requirements. Ordering it as soon as the release is scoped, rather than when code freeze approaches, removes an entire category of risk from the schedule.

Enterprise Deployment Channels: Intune, SCCM, and Jamf

Notarization

Enterprise IT does not install software one device at a time. It pushes a signed installer through a management platform to hundreds or thousands of managed devices at once, and each platform has its own packaging expectations.

Silent Install Requirements for Managed Deployment for electron enterprise app distribution

Microsoft’s documentation states plainly that Intune does not support interactive application installations, and that Win32 apps deployed through Intune must install silently without dialog boxes, prompts, or any UI input during the process. An MSI that pops a license agreement screen or a custom wizard step will fail Intune deployment even if it installs perfectly when a user double-clicks it manually. Testing the silent install command directly, not just testing the interactive install, is a required step before handing the package to a customer’s IT team.

Packaging Considerations for SCCM and Jamf

SCCM, used widely in larger Windows enterprise environments, expects the same silent-install behavior as Intune, plus predictable detection logic based on registry keys or file versions. Jamf Pro, the standard macOS management platform in enterprise IT, wraps a signed and notarized DMG or PKG into a policy that pushes to managed Macs, and it depends entirely on the app already being properly signed and notarized before it reaches Jamf.

What IT Will Ask Before Approving a Rollout for electron enterprise app distribution

Expect the customer’s IT team to ask for the exact silent install command, the detection method they should use to confirm a successful install, whether the app phones home to any external service, and how updates get delivered after the initial rollout. Having clear answers to all four ready before the first IT conversation shortens the review considerably.

Planning Your Release Timeline Around Signing and Notarization Lead Times

Notarization

Distribution does not need to be the reason a launch date slips. It needs a realistic calendar built around the lead times above.

A Sample Timeline From Code Freeze to Enterprise-Ready Build

A workable pattern starts certificate procurement and Apple Developer Program renewal at project kickoff, well before code freeze. Once the app reaches feature-complete, the team builds and signs the MSI and DMG, submits the macOS build for notarization, and runs a full silent-install test against Intune or Jamf in a sandbox tenant. That sequence, run in parallel across platforms, typically fits inside a two-week window once certificates are already in hand.

Buffer Time for Notarization Rejections and Resubmission for electron enterprise app distribution

Even a well-prepared submission can get rejected for something small, like a missing entitlement or an unsigned embedded framework. Build at least one resubmission cycle into the calendar rather than assuming the first submission passes. A rejection plus a rebuild plus a resubmission can add a day or two, which is manageable if the calendar already expects it and costly if it does not.

Coordinating With Customer IT Teams Before Rollout for electron enterprise app distribution

Customer IT review is the step least within a vendor’s control and often the longest. Starting that conversation as soon as the enterprise-ready build exists, rather than after internal QA finishes, gives the customer’s security team time to run its own review in parallel with final testing instead of after it.

Table: Sample Distribution Timeline

Milestone Typical Lead Time Owner
Apple Developer Program enrollment 1 to 2 days once documents are ready Engineering or IT admin
Windows EV certificate issuance 1 to 3 weeks depending on vendor and verification Engineering or IT admin
Code signing and packaging 1 to 2 days per platform Engineering
Apple notarization Minutes to a few hours, longer if rejected Engineering
Customer IT review before rollout 1 to 4 weeks depending on the account Product and customer success

This table gives a PM a rough planning reference, not a guaranteed timeline. Actual lead times vary by certificate vendor, Apple’s submission queue, and each customer’s internal review process.

How Tibicle Manages Electron Distribution for Enterprise Releases for electron enterprise app distribution

Distribution planning gets easier with a pipeline that already handles signing, notarization, and packaging as a repeatable process instead of a one-off task for every release.

Packaging and Signing Pipeline Setup for electron enterprise app distribution

Tibicle sets up the build pipeline to produce a signed MSI and a signed, notarized DMG from the same codebase, with certificate handling wired into CI so signing does not depend on a single engineer’s local machine. This is part of Tibicle’s broader Electron desktop app development work for clients moving from a prototype to an enterprise-ready release.

Notarization, MSI Builds, and Release Automation for electron enterprise app distribution

The pipeline submits macOS builds for notarization automatically as part of the release process, staples the ticket, and validates the silent install command for both platforms before a build is marked ready for customer IT review. This removes the manual, error-prone steps that most commonly cause rejected notarization submissions or failed Intune deployments.

Ongoing Release Support and Enterprise IT Coordination for electron enterprise app distribution

Beyond the initial release, Tibicle supports the auto-update pipeline and coordinates directly with customer IT teams during rollout, including answering the detection-method and silent-install questions IT admins ask before approving a deployment. Teams building compliance-sensitive Electron apps often pair this distribution work with the data-handling practices covered in Tibicle’s guide to building GDPR-compliant desktop apps with Electron.

Key Takeaways for Product Managers for electron enterprise app distribution

  • MSI and DMG are not optional extras. Most enterprise IT teams require them before they will approve a rollout.
  • Certificate issuance and notarization both have lead times that belong on the project timeline, not just the engineering backlog.
  • Windows now requires an EV code signing certificate, which changes both cost and issuance time compared to older certificate types.
  • Customer IT review is often the longest step in the whole distribution timeline. Plan for it early.

Ready to plan your enterprise release calendar? Book a call with Tibicle to walk through your distribution timeline.

FAQs

Why does enterprise IT require an MSI installer instead of a regular .exe?
IT teams manage software at scale through tools that expect a standard, queryable installer format. An MSI exposes version and product information those tools can read; a generic .exe does not.

How long does Apple notarization actually take?
The automated scan usually finishes in minutes to under an hour. Delays happen mostly from rejections, not queue time, so build in a buffer for at least one resubmission.

What does an EV code signing certificate cost, and why does Windows require one now?
Costs vary by vendor and typically run several hundred dollars a year. Microsoft moved to requiring EV certificates in June 2023 because standard certificates no longer prevent Windows security warnings.

Can an Electron app be deployed silently through Intune or SCCM?
Yes, but only if the installer supports a true silent install command with no dialog boxes. Test this directly before handing the package to a customer’s IT team.

How far in advance should a PM plan for code signing and notarization?
Start certificate procurement and Apple Developer Program setup at project kickoff. Certificates alone can take one to three weeks, and customer IT review can take up to a month.

Does Tibicle handle the full distribution pipeline for enterprise Electron releases?
Yes. Tibicle sets up signing, MSI and DMG packaging, notarization, and ongoing release support as part of its Electron desktop app development work.