
Custom AI Chatbot Development Services

Sep 22, 2026

Read in 8 Minutes
Table of Contents
- What This Guide Covers
- Introduction
- Why Enterprises Are Investing in Custom AI Chatbot Development Services
- Off-the-Shelf Chatbot Builders vs Custom AI Chatbot Development Services
- RAG Architecture for Enterprise Custom AI Chatbot Development Services
- Enterprise Data Security for Custom AI Chatbot Development Services
- Multi-Channel custom AI chatbot Development Services and Integration
- Cost, Maintenance, and Measuring Custom Chatbot AI Development Service ROI
- How Tibicle Builds Custom AI Chatbot Development Services
- Key Takeaways for Enterprise Teams
- Frequently Asked Questions
What This Guide Covers
Who this is for:
CIOs, CTOs, AI leaders, operations executives, customer support teams, and enterprise technology decision-makers evaluating custom AI chatbot development services for internal knowledge access, customer support, helpdesk automation, or other business-critical use cases. It is particularly relevant for organisations with proprietary knowledge bases, sensitive data, complex access controls, and requirements that extend beyond the capabilities of standard no-code chatbot platforms.
Search intent:
Commercial investigation and solution evaluation. The reader is not looking for a basic explanation of how AI chatbots work. They are evaluating whether to build a custom AI chatbot, use an off-the-shelf platform, or adopt a hybrid approach. The key decision factors are enterprise RAG chatbot architecture, hallucination control, data security, access control, system integration, build and maintenance costs, and measurable ROI before moving from pilot to production.
What you will walk away with:
A practical framework for evaluating and implementing a production-ready enterprise AI chatbot, including the differences between no-code, custom, and hybrid chatbot approaches; RAG architecture and retrieval pipeline design; knowledge base management; PII redaction and role-based access control; multi-channel and CRM integration; build and ongoing maintenance costs; and the key metrics required to measure ROI. You will also have a clearer basis for deciding what architecture your organisation needs and what must be in place before an enterprise chatbot is deployed against real company data.
Introduction
The market for custom AI chatbot development services is expanding faster than most enterprise technology budgets anticipated. The global conversational AI market was valued at $13.2 billion in 2024 and is projected to grow at a compound annual growth rate of 23.7% through 2030, according to Grand View Research’s Conversational AI Market Report. Behind that number is a specific shift in what enterprises are buying: not scripted bots that match keywords to canned responses, but AI assistants that reason over a company’s actual knowledge base and return answers grounded in real internal documents.
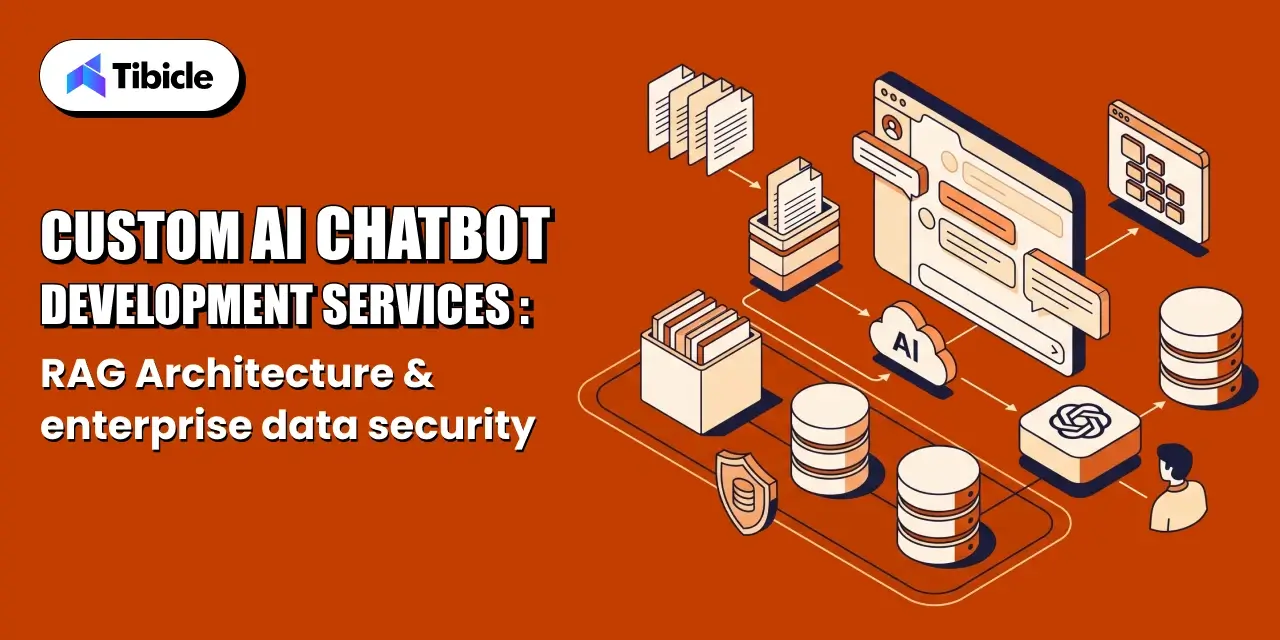
That shift is architectural. The scripted bot model breaks when the number of edge cases in a real business environment exceeds what any decision tree can handle. Retrieval-augmented generation — RAG — replaces the decision tree with a retrieval pipeline that pulls relevant source documents at query time, feeds them to a language model, and grounds the answer in content the company actually controls.
This guide covers the architecture decisions, data security requirements, deployment patterns, cost structures, and ROI metrics that determine whether a custom AI chatbot development project reaches production or stalls in pilot.
Why Enterprises Are Investing in Custom AI Chatbot Development Services
The case for custom AI chatbot development services in enterprise settings is no longer being made by innovation teams alone. It is being made by CFOs and operations leaders who can see a direct line between chatbot deployment and labor cost reduction at scale.
From Scripted Bots to RAG-Grounded Enterprise Assistants
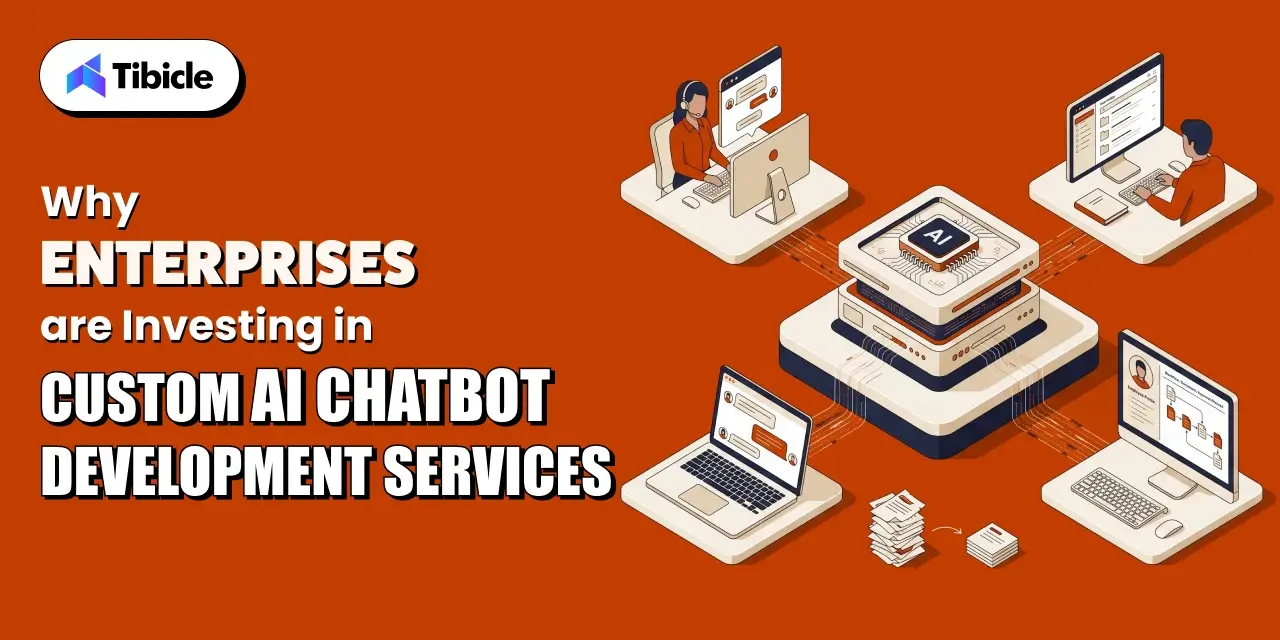
Scripted bots defined the first generation of enterprise chatbot deployment. They worked well inside narrow, predictable query spaces: password resets, order status lookups, simple FAQ deflection. They stopped working the moment a user asked something the decision tree hadn’t been programmed to anticipate, which, in an enterprise environment with thousands of employees or customers, happens constantly.
Enterprise RAG chatbot architecture addresses that failure mode at the structural level. Instead of matching keywords to pre-written responses, a RAG-grounded assistant retrieves the most relevant passages from a defined knowledge base at the time of each query, passes those passages to a language model as context, and generates an answer that is grounded in current, approved source documents. The chatbot’s answer quality is bounded by the quality of what it retrieves, which makes retrieval pipeline design the most important engineering decision in the project.
The Labor Cost Case for Custom AI Chatbot Development Services
Gartner projected that conversational AI would reduce contact center agent labor costs by $80 billion by 2026, according to a Gartner press release on conversational AI cost impact. That figure reflects deflection at scale: queries that previously required a human agent handled entirely by an AI assistant without agent involvement.
The internal labor cost case for enterprise teams follows the same logic. Support ticket deflection, internal knowledge search, HR policy lookup, and IT helpdesk automation all represent query volumes that currently consume human time. A custom chatbot grounded in the company’s own documentation handles those queries without agent involvement, and unlike a scripted bot, it handles variants and edge cases without requiring a developer to write a new rule for each one. The ROI calculation starts with deflection rate and average handle time, not with feature counts.
Off-the-Shelf Chatbot Builders vs Custom AI Chatbot Development Services
The build-versus-buy question for a chatbot project is not abstract. It resolves quickly once an enterprise team tries to connect a no-code chatbot builder to a proprietary knowledge base that changes regularly, has multi-level access controls, and needs to produce answers the compliance team will sign off on.
Where No-Code Chatbot Builders Fall Short
No-code builders are designed for breadth: they support a wide range of generic use cases and ship fast. The trade-off is depth. Connecting to a proprietary knowledge base with custom indexing logic, applying access controls that scope what each user is allowed to retrieve, and implementing PII redaction before content reaches the language model are all outside the configuration surface of most no-code platforms. The fallback is manually encoding FAQs into the platform, which reintroduces the same maintenance problem that made scripted bots obsolete in the first place.
What Separates Chatbot Projects That Reach Production
MIT NANDA’s “The GenAI Divide” report found that a significant share of enterprise generative AI pilots fail to reach production or deliver measurable P&L impact. The primary failure modes are not model quality issues — they are data integration failures, access control gaps, and user trust problems that surface when a chatbot returns confidently wrong answers it cannot source to an approved document. Custom AI chatbot development services address these failure modes at the architecture level, before deployment, rather than as patches after go-live.
When a Hybrid Approach Makes Sense
A hybrid build, starting with a vendor chatbot platform and layering custom retrieval and orchestration on top, is the practical answer for enterprise teams that have already invested in a platform they are not ready to replace. The vendor platform handles channel management and basic session logic; the custom layer handles retrieval quality, access scoping, and response grounding. This approach shortens the initial build timeline and preserves existing vendor contracts while addressing the knowledge-base retrieval gaps that prevent most off-the-shelf chatbots from reaching production quality.
Use the table below to map the three approaches to your specific situation:
| Approach | What It Involves | Best Fit |
| No-code chatbot builder | Configure a third-party platform with scripted flows and minimal customisation | Simple FAQ deflection, fast validation |
| Custom AI chatbot development services | Build RAG retrieval, orchestration, and access control around the company’s own data | Customer-facing or internal assistants tied to real knowledge bases |
| Hybrid build | Start with a vendor platform, add custom retrieval and orchestration on top | Teams with an existing chatbot that has outgrown its platform |
RAG Architecture for Enterprise Custom AI Chatbot Development Services
The architecture decisions that determine whether a custom AI chatbot answers from a company’s actual documents, or from the language model’s general training data sit entirely inside the retrieval pipeline. Getting retrieval right is the engineering work that separates a production-ready enterprise assistant from a demo.
How Retrieval-Augmented Generation Grounds Chatbot Answers in Your Data
Retrieval-augmented generation works by inserting retrieved document passages into the language model’s context window at query time. The model generates its response based on what it retrieves, not on what it learned during training. Research published at NAACL 2024 by Bechard & Marquez Ayala (ACL Anthology) found that RAG significantly reduces hallucination in real enterprise chatbot applications, meaning that when retrieval finds the relevant source document, the model stops generating content from general training data and grounds its answer in the retrieved text instead.
The critical design point: hallucination reduction is a retrieval quality problem, not a model quality problem. A more powerful language model running against a poorly designed retrieval pipeline will still hallucinate; it will just produce more fluent-sounding hallucinations. Retrieval pipeline design, chunking strategy, embedding model selection, and re-ranking logic all directly determine answer accuracy.
Vector Database and Knowledge Base Design
A vector database stores document chunks as numerical embeddings, dense vector representations that capture semantic meaning rather than keyword matching. When a user submits a query, the retrieval system embeds the query using the same model, searches the vector store for the nearest document chunks, and returns the most semantically relevant passages. The engineering decisions that matter most at this layer are chunking strategy, how documents are split before embedding, and the embedding model’s ability to represent domain-specific content accurately.
Most enterprise knowledge bases are not static. Policies change, product documentation updates, and personnel records evolve. The vector store must be designed to reflect those changes, which means incremental indexing pipelines and document versioning are not optional infrastructure. A chatbot trained on stale embeddings produces confidently outdated answers that are harder to catch than obviously wrong ones.
Keeping Answers Current as Source Documents Change
Source document currency is an operational problem as much as an architecture problem. Knowledge base grounding requires that the retrieval index reflects the current state of the company’s documents at all times, not the state they were in on the day the chatbot launched. Automated ingestion pipelines that monitor document repositories, detect changes, re-chunk updated content, and refresh embeddings without manual intervention are the infrastructure layer that keeps a deployed enterprise chatbot from drifting toward stale answers over time.
For regulated industries, financial services, healthcare, and legal, document currency is also a compliance requirement. An answer grounded in a policy that has since been revised is not just a user experience problem. It is a liability exposure that an audit log will surface.
Enterprise Data Security for Custom AI Chatbot Development Services
The governance gap in enterprise chatbot deployments is predictable: pilots ship fast, access controls are added later, and by the time a security review happens, the chatbot has already touched data it was never supposed to see. Enterprise chatbot data security is an architecture problem that needs to be solved before the first query, not after the first audit.
Preventing Shadow AI and Unsanctioned Chatbot Use
IBM’s Cost of a Data Breach Report 2026 identified shadow AI, unsanctioned AI tools used by employees outside formal IT governance, as a growing source of data breach incidents, with a significant share of AI-related breaches missing basic access controls at the point of data retrieval. Shadow AI chatbot risk is not theoretical: employees who cannot get answers from approved internal tools will use consumer AI tools instead, feeding proprietary documents, customer data, and internal communications into systems the company does not control.
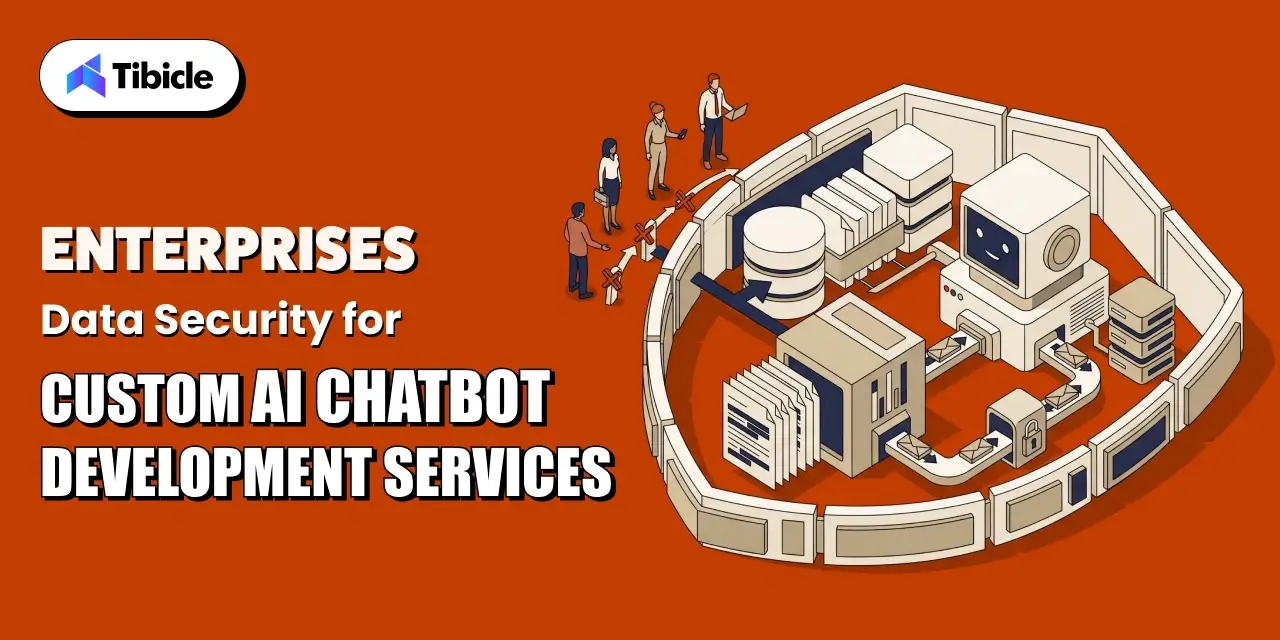
The preventive measure is not restriction alone; it is providing a sanctioned alternative that is genuinely useful. A custom AI chatbot that answers accurately from approved knowledge bases removes the incentive to use unsanctioned tools. The security architecture access controls, audit logging, and session isolation exists inside the sanctioned system rather than being bypassed by it.
PII Redaction and Access Control Inside Chatbot Responses
PII redaction in a chatbot access control architecture belongs at the retrieval layer, not the response layer. Redacting sensitive content from the final answer after the language model has already processed it addresses only part of the exposure. If the model ingests a retrieved document chunk containing customer PII before the answer is generated, that data has already entered the model’s context, which creates a logging and compliance risk even when the final response is clean.
Access scoping, limiting what each user can retrieve based on their role, team, and permissions, works on the same principle. The retrieval query must be filtered by the requesting user’s access rights before the vector store is searched, not after results are returned. Row-level security models in the vector database are the standard implementation pattern.
Audit Logging and Compliance Documentation
A SOC 2-compliant chatbot requires audit logs that capture not just that a query occurred, but what source documents were retrieved to generate the answer, which version of those documents was current at query time, and what the user’s access scope was at the time of retrieval. These four requirements form the compliance documentation layer that a security audit or regulatory review will ask for.
Non-negotiable requirements before a custom enterprise chatbot touches company data:
- Redact or mask PII before it reaches the language model, not just in the final response
- Scope the chatbot’s data access to what the requesting user is actually permitted to see
- Chatbot audit logging: log the source documents behind every answer, not just that a query occurred
- Route any question the chatbot cannot ground in an approved source to a human, instead of letting it guess
Multi-Channel custom AI chatbot Development Services and Integration
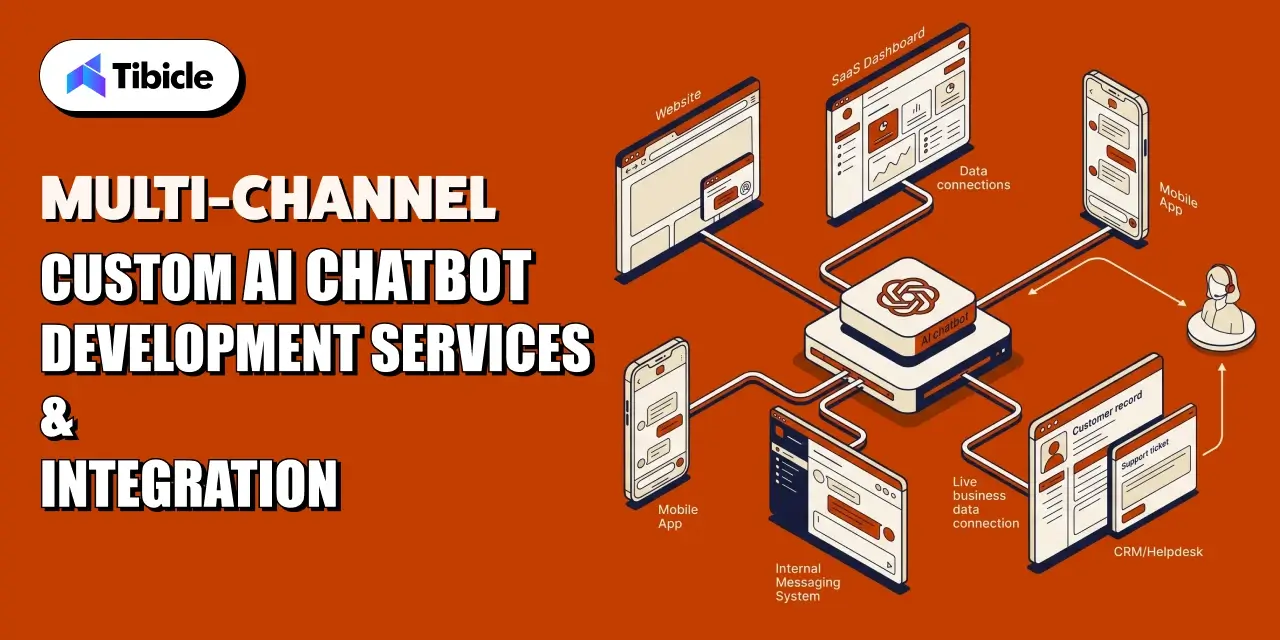
A custom AI chatbot that only lives in one channel is solving one problem. Most enterprise deployments require the same underlying assistant to surface across multiple product interfaces, internal tools, and communication platforms, each with its own session management and handoff requirements.
Embedding the Chatbot Into Existing Product Surfaces
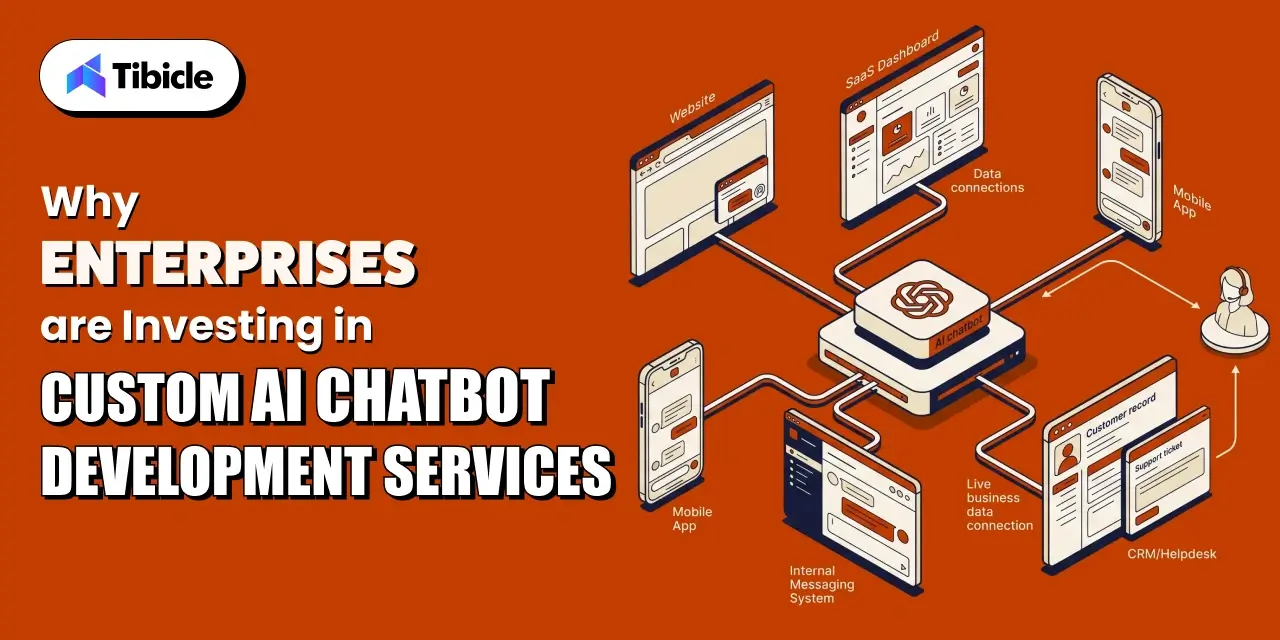
The chatbot integration layer handles channel-specific rendering: a web widget on the product site, an iframe embed inside a SaaS dashboard, a Slack or Teams integration for internal knowledge access, a WhatsApp channel for customer support. Each surface requires channel-specific session management and UI adaptation, but the retrieval pipeline, access controls, and LLM orchestration layer are shared across all of them. Building that shared core first and treating channel adapters as a separate layer on top is the architectural pattern that makes multi-surface deployment manageable.
Connecting to CRM, Helpdesk, and Internal Systems
An order management system, CRM, or helpdesk integration allows the chatbot to pull live data, not just static documents at query time. A customer support assistant that can retrieve the user’s open ticket history from Zendesk, or the customer’s account status from Salesforce, produces answers that are grounded in current transaction data rather than generalised policy text. These integrations require authenticated API connections with the same access scoping principles that apply to document retrieval: the chatbot queries the CRM on behalf of the requesting user, scoped to what that user is permitted to see.
Handoff to Human Agents When the Bot Hits Its Limits
A custom AI chatbot that cannot ground an answer should not guess. The handoff condition the point at which the chatbot transfers the session to a human agent is an architecture decision, not a UX afterthought. Triggering conditions include: retrieval confidence below a defined threshold, a query category that falls outside the approved knowledge base scope, a user who has explicitly escalated, and any query that touches regulated content the chatbot is not permitted to interpret.
The handoff mechanism must pass session context, the full conversation history, and the retrieval attempts made to the receiving agent. An agent inheriting a handoff with no context starts the interaction from zero, which produces exactly the friction that the chatbot was deployed to reduce.
Cost, Maintenance, and Measuring Custom Chatbot AI Development Service ROI
The cost structure of a custom enterprise chatbot spans build, infrastructure, and ongoing maintenance and the ongoing costs are the ones that most project budgets underestimate. Understanding all three before the first contract is signed is what separates a sustainable deployment from one that gets abandoned six months after launch.
What a Custom Enterprise Chatbot Actually Costs
Build costs for custom AI chatbot development services at the enterprise level typically range from $40,000 to $200,000 depending on scope, data complexity, and integration requirements. A focused internal knowledge assistant with a single document source and one channel sits at the lower end. A multi-channel customer-facing assistant with CRM integration, multi-tenant access scoping, PII redaction, and SOC 2 audit logging sits at the upper end. The variable that has the most impact on build cost is data readiness: how many source systems need ingestion pipelines, how clean the source documents are, and how much custom access control logic is required.
Ongoing Costs: Retraining, Monitoring, and Model Updates
Infrastructure costs post-launch include LLM API consumption, vector database storage and query costs, and embedding refresh compute for document updates. For most mid-market deployments, these run $500 to $3,000 a month depending on query volume and the LLM provider’s pricing tier. Beyond infrastructure, LLM orchestration maintenance, prompt updates as the language model’s behaviour changes across provider versions, retrieval pipeline tuning as the knowledge base grows, and access control updates as org structures change require ongoing engineering time. Plan for 10 to 20 hours of development time per month for a production chatbot with active query volume.
Metrics That Prove the Custom AI Chatbot development service Is Working
Four metrics translate chatbot performance into financial language:
- Deflection rate — the percentage of queries handled without human escalation, the primary labor cost driver
- Answer grounding rate — the percentage of responses that cite a specific source document, the proxy for hallucination control
- User-reported resolution rate — whether the user’s question was actually answered, separate from whether the chatbot gave a confident response
- Cost per resolved query — total operating cost divided by grounded, resolved queries; the benchmark for comparing against human agent cost
Measuring only deflection rate without answer grounding rate produces misleading ROI figures: a chatbot that deflects 80% of queries but hallucinates 40% of its answers is not a cost reduction it is a liability.
How Tibicle Builds Custom AI Chatbot Development Services
Tibicle’s custom AI chatbot development services are structured around three phases: discovery and architecture planning, implementation with security built in from the start, and post-launch support that keeps the knowledge base current and the retrieval pipeline accurate as the company’s data evolves.
Discovery and RAG Architecture Planning
The discovery phase maps the enterprise’s data landscape before any code is written: which knowledge bases need ingestion pipelines, what the access control model looks like across user roles, which channels the chatbot needs to surface on, and what the compliance requirements are for the industry and data types involved. The output of discovery is a RAG architecture specification: chunking strategy, embedding model selection, vector store design, re-ranking logic, and orchestration framework that the build phase implements against. Skipping discovery and going straight to a build phase is the most common reason enterprise chatbot projects miss their production quality targets.
Implementation With Security and Access Control Built In
Tibicle’s implementation approach treats enterprise chatbot data security as a first-class engineering requirement rather than a post-launch configuration task. PII redaction is implemented at the retrieval layer. Access scoping is applied before the vector store query, not after. Audit logging captures source documents at the time of retrieval, not just query events. The result is a chatbot that arrives at its compliance review with the access control architecture already in place, rather than requiring a security retrofit before it can go live with sensitive data.
For teams evaluating how a custom build compares to their current stack, Tibicle’s approach to enterprise RAG chatbot architecture integrates with existing CRM, helpdesk, and identity management systems rather than requiring a wholesale infrastructure replacement.
Ongoing Support and Knowledge Base Maintenance
A custom AI chatbot is not a static deployment. As the company’s knowledge base evolves new policies, updated product documentation, personnel changes the retrieval index needs to stay current. Tibicle’s post-launch support covers automated ingestion pipeline monitoring, embedding refresh scheduling, prompt updates as LLM provider versions change, and retrieval quality reviews that catch drift before it affects answer accuracy in production.
The support model is designed for teams without a dedicated AI engineering function: structured monthly reviews, defined escalation paths for retrieval quality issues, and access to the same engineering team that built the system rather than a tiered support queue that has no context on the original architecture.
Key Takeaways for Enterprise Teams
Custom AI chatbot development services succeed or fail on retrieval quality, not on which language model generates the final answer. The most important engineering decisions in a chatbot project sit inside the retrieval pipeline: chunking strategy, embedding model, access scoping, and re-ranking logic.
- No-code chatbot builders rarely survive contact with a real knowledge base; most stall before production because they cannot implement the access controls and PII redaction a compliance team requires
- PII redaction and access scoping belong inside the retrieval pipeline, not bolted onto the response afterward
- A chatbot that cannot ground an answer should hand off to a human, not guess
- Measure answer grounding rate alongside deflection rate; hallucination reduction is the metric that determines whether the chatbot is actually reducing liability or just shifting it
Ready to scope a custom AI chatbot for your enterprise? Book a discovery call with Tibicle’s team; the session maps your knowledge base, access requirements, and deployment channels before any architecture decisions are made.
Frequently Asked Questions
What are custom AI chatbot development services, and how are they different from a chatbot builder platform?
Custom AI chatbot development services build the retrieval pipeline, access control layer, and LLM orchestration logic around a company’s specific knowledge base and compliance requirements. A chatbot builder platform provides a configurable interface for scripted flows and generic FAQ deflection. The structural difference is retrieval: a custom-built assistant retrieves answers from the company’s own documents at query time; a platform bot returns pre-written responses that must be manually maintained.
How does RAG architecture reduce hallucination in an enterprise chatbot?
Retrieval-augmented generation reduces hallucination by inserting retrieved source documents into the language model’s context window before the answer is generated. The model produces its response based on what it retrieves, not on general training data. Research from NAACL 2024 confirms this approach significantly reduces hallucination in real enterprise applications. The mechanism: when a relevant source document is retrieved, the model uses it; when no relevant document is found, a well-designed system routes the query to a human instead of guessing.
What data security measures does an enterprise chatbot need before it can access company data?
At minimum: PII redaction at the retrieval layer before content reaches the language model, role-based access scoping applied before the vector store is queried, audit logging that captures source documents behind every answer, and a defined handoff protocol for queries the chatbot cannot ground in approved content. For regulated industries, SOC 2 audit trail requirements apply to the logging architecture as well.
Can custom AI chatbot development services integrate with our existing CRM or helpdesk software?
Yes. Integration with Salesforce, HubSpot, Zendesk, Freshdesk, and similar platforms is a standard component of enterprise chatbot architecture. The integration layer pulls live CRM or ticket data at query time — scoped to the requesting user’s access rights — and combines it with document retrieval to produce answers grounded in both static knowledge and current transactional data.
How much does a custom AI chatbot development services cost to build and maintain?
Build costs typically range from $40,000 to $200,000 depending on data source complexity, channel count, and access control requirements. Ongoing infrastructure costs run $500 to $3,000 per month at mid-market query volumes, plus 10 to 20 hours of development time per month for pipeline maintenance and retrieval quality monitoring.
Does Tibicle build custom AI chatbots development services with RAG architecture and enterprise data security?
Yes. Tibicle’s custom AI chatbot development services cover the full delivery scope: discovery and RAG architecture planning, implementation with PII redaction and access control built in from the start, multi-channel deployment, and post-launch support that keeps the knowledge base current as the company’s data evolves. Every engagement starts with a structured discovery session that maps data sources, access requirements, and compliance obligations before any architecture decisions are made.
Schedule A Developer Interview And Get 15 Days Risk-Free Trial
Schedule a Call

Relevant Blog
GraphRAG Implementation Services
Arjun Shinojiya

Enterprise AI Automation Development Agency
Arjun Shinojiya
Legacy Application AI Modernization Services
Arjun Shinojiya
Written by
Recent Blogs
Custom AI Chatbot Development Services
What This Guide Covers Who this is for: CIOs, CTOs, AI leaders, operations executives, customer support teams, and enterprise technology decision-makers evaluating custom AI chatbot development services for internal knowledge access, customer support, helpdesk automation, or other business-critical use cases. It is particularly relevant for organisations with proprietary knowledge bases, sensitive data, complex access controls, […]
GraphRAG Implementation Services
Who this is for: Engineering leads and product owners at enterprise SaaS companies evaluating GraphRAG implementation services for a knowledge base or retrieval system that vector search alone is not answering well. Search intent: Commercial evaluation with a technical backbone. The reader has moved past “what is GraphRAG” and wants to know when a knowledge […]
Enterprise AI Automation Development Agency
Who this is for: Operations leads, CTOs, and process owners evaluating an enterprise AI automation development agency for a full business process rather than a single bolted-on bot. Search intent: Commercial evaluation with a technical backbone. The reader has moved past “what is workflow automation” and wants to know why point-solution RPA plateaus, what end-to-end […]
Got an Idea? Get FREE Consultation
In our world, there's no such thing as having too many clients

