
Fine-Tuning vs. RAG Deployment: Total Cost of Ownership (TCO) for Enterprise AI Apps

Oct 05, 2026

Read in 6 Minutes
Table of Contents
- What This Guide Covers
- Introduction
- Why the Fine-Tuning vs RAG Cost Question Just Got More Complicated
- What Custom LLM Fine-Tuning Services Actually Cost
- What RAG Deployment Actually Costs
- Accuracy and Performance Trade-offs That Affect TCO
- A TCO Framework for Choosing Between Fine-Tuning and RAG
- Common TCO Mistakes Enterprises Make
- How Tibicle Helps Enterprises Choose Between Fine-Tuning and RAG
- FAQ
What This Guide CoversWho this is for
Commercial investigation. The reader is comparing two viable technical approaches before a budget or architecture decision, not looking for a definition of either term. They want numbers, a framework, and a clear answer on when each approach wins on cost.
Search intent
Enterprise engineering leads, ML platform teams, and technical decision-makers evaluating how to customize an LLM for a production application. Written for readers who already know what fine-tuning and RAG are and need to compare cost, not learn the basics.
What you will walk away with:
A working framework for comparing fine-tuning and RAG on total cost of ownership rather than sticker price alone, including where the hidden costs sit in each approach and how OpenAI’s fine-tuning platform wind-down changes the calculation for teams already in production. The guide breaks down one-time training cost, the ongoing inference premium on fine-tuned models, vector database and per-query costs for RAG, and the accuracy and latency trade-offs that affect the decision beyond price. It closes with a break-even model readers can apply to their own request volume and data change frequency, plus the most common budgeting mistakes to avoid when making the call.
Introduction
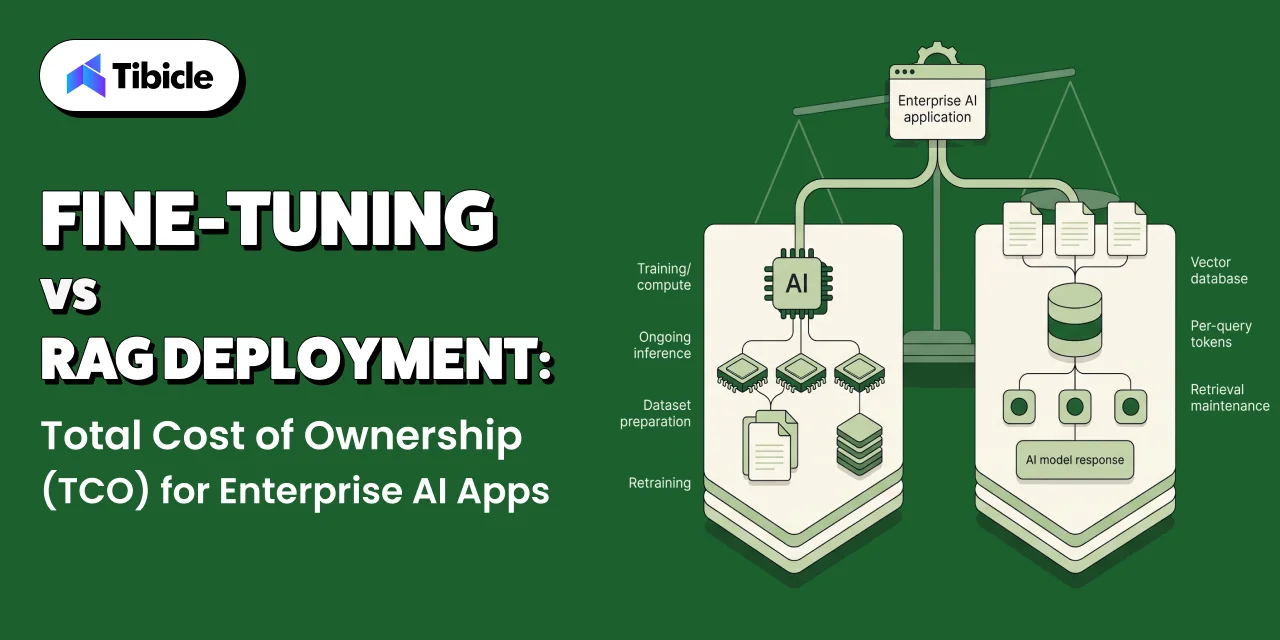
OpenAI’s decision to wind down self-serve fine-tuning has made the cost comparison between fine-tuning and RAG harder to get right with old assumptions. Enterprises that treated the fine-tuning API as a stable, always-available option now have to factor in platform risk alongside training and inference pricing, while RAG’s own costs keep shifting as vector database pricing and per-query token costs move in opposite directions. This guide lays out what each approach actually costs, where the estimates most teams use fall short, and how to build a TCO model that holds up regardless of which provider changes its pricing or availability next.
Why the Fine-Tuning vs RAG Cost Question Just Got More Complicated
OpenAI’s wind-down does not delete anything a team has already shipped. Inference on fine-tuned models keeps running until the underlying base model is deprecated (OpenAI). What changes is optionality. A team that assumed it could retrain a fine-tuned model whenever the underlying data shifted now has to check whether its organization still qualifies to start a new job, and that qualification window is shrinking on a fixed schedule. For a TCO model, that turns “retraining cost” from a variable a team controls into one partly controlled by the provider.
OpenAI Is Winding Down Self-Serve Fine-Tuning
OpenAI’s own deprecation notes confirm a three-stage schedule. Organizations with no prior fine-tuning history could not start new jobs after May 7, 2026. Starting July 2, 2026, organizations that have not run fine-tuned-model inference in the past 60 days lose the ability to start new jobs. On January 6, 2027, the ability to create new fine-tuning jobs closes for every remaining customer (OpenAI). Fine-tuned models already in production are not affected until their base model is deprecated separately.
What This Means for Enterprises Already Fine-Tuning
If a fine-tuned model is already live, nothing breaks this month. The practical exposure shows up at the next retraining cycle. A team that fine-tunes quarterly to reflect new product data needs to confirm its organization still qualifies to submit a new job, and needs a fallback plan for the point where OpenAI’s platform no longer accepts new jobs at all. That fallback is usually one of three things: fine-tuning through a different provider, moving to a hybrid RAG and fine-tuning setup, or shifting the customization work into the RAG layer entirely. Each option carries a different cost profile, which is the reason this comparison now needs updating more than once a year.
What Custom LLM Fine-Tuning Services Actually Cost
Custom LLM fine-tuning services cost has three components: a one-time training run, an ongoing inference premium, and a set of preparation and retraining costs that most estimates leave out. The training run is the easiest to quote and the smallest share of the real total.
One-Time Training Cost by Model Size
Training cost scales with model size and dataset size, not with how long the fine-tuning job runs on paper. A smaller open-weight model fine-tuned with LoRA on a few thousand examples can run into the low hundreds of dollars in compute. A larger proprietary model fine-tuned through a hosted API, or a full fine-tune of an open-weight model in the tens of billions of parameters, moves into the thousands to tens of thousands of dollars once GPU rental time, multiple training runs for hyperparameter tuning, and engineer time are counted. The training run itself is rarely the line item that breaks a budget.
The Ongoing Inference Premium on Fine-Tuned Models
The line item that does break budgets is the inference premium. Hosted fine-tuned models typically cost more per token to run than the equivalent base model, because the provider has to serve a custom checkpoint instead of a shared one. That premium compounds with volume. A fine-tuned model handling millions of requests a month carries that premium on every single call, for as long as the model stays in production. A TCO model that only accounts for the training run and skips this ongoing premium will consistently understate the real cost of fine-tuning.
Hidden Costs: Dataset Preparation and Retraining Cycles
Dataset preparation is the cost most teams underestimate. Building a fine-tuning dataset that actually improves the model, rather than one that overfits to a handful of examples, takes subject-matter expert time to write, review, and label examples. That cost repeats every time the underlying knowledge changes enough to require retraining, and retraining also means re-running evaluation to confirm the new checkpoint has not regressed on cases the old one handled correctly.
| Approach | Cost Structure | Best Fit |
| Fine-tuning | Higher upfront training cost, ongoing inference premium, retraining cost when data changes | Stable domain knowledge, strict output format or tone requirements |
| RAG | Lower upfront cost, ongoing vector database and per-query token cost | Frequently changing knowledge bases, need for source citations |
| Hybrid (RAFT-style) | Combines training cost with retrieval infrastructure cost | Domain-specific reasoning that also needs current, grounded facts |
What RAG Deployment Actually Costs
RAG deployment total cost of ownership sits mostly in infrastructure that keeps running after launch, not in a one-time setup fee. The three cost centers are the vector database itself, per-query token costs, and the pipeline work that keeps retrieval accurate.
Vector Database Infrastructure and Ongoing Storage Costs
Vector database spend is a recurring line item, and the category is growing fast enough that pricing models are still shifting. MarketsandMarkets projects the vector database market growing from roughly $2.65 billion in 2025 to $8.95 billion by 2030, a 27.5% compound annual growth rate (MarketsandMarkets). For a TCO model, that pace of growth means storage and hosting costs are unlikely to settle into a predictable flat rate any time soon, so a RAG deployment budget needs a review point, not a one-time estimate.
Per-Query Token Costs and Why They Keep Falling
Per-query costs are the one line item in this comparison moving consistently in the buyer’s favor. Epoch AI’s analysis of LLM inference prices at a fixed performance level found the cost to reach a given benchmark score falling by a median of roughly 40 to 50 times per year, with the range spanning 9x to 900x depending on the task (Epoch AI). That decline directly lowers RAG’s per-query token cost over time, since a RAG call typically includes both the retrieved context and the model’s response in the token count.
Retrieval Pipeline Maintenance Costs
Falling token prices do not remove the work of keeping retrieval accurate. Chunking strategy, embedding model choice, and re-ranking logic all need periodic review as the underlying knowledge base grows, and a pipeline that worked well at launch can degrade quietly as documents pile up unless someone is checking retrieval quality on a schedule. This maintenance work rarely shows up in an initial RAG cost estimate, and it is the RAG equivalent of fine-tuning’s retraining cost.
Accuracy and Performance Trade-offs That Affect TCO
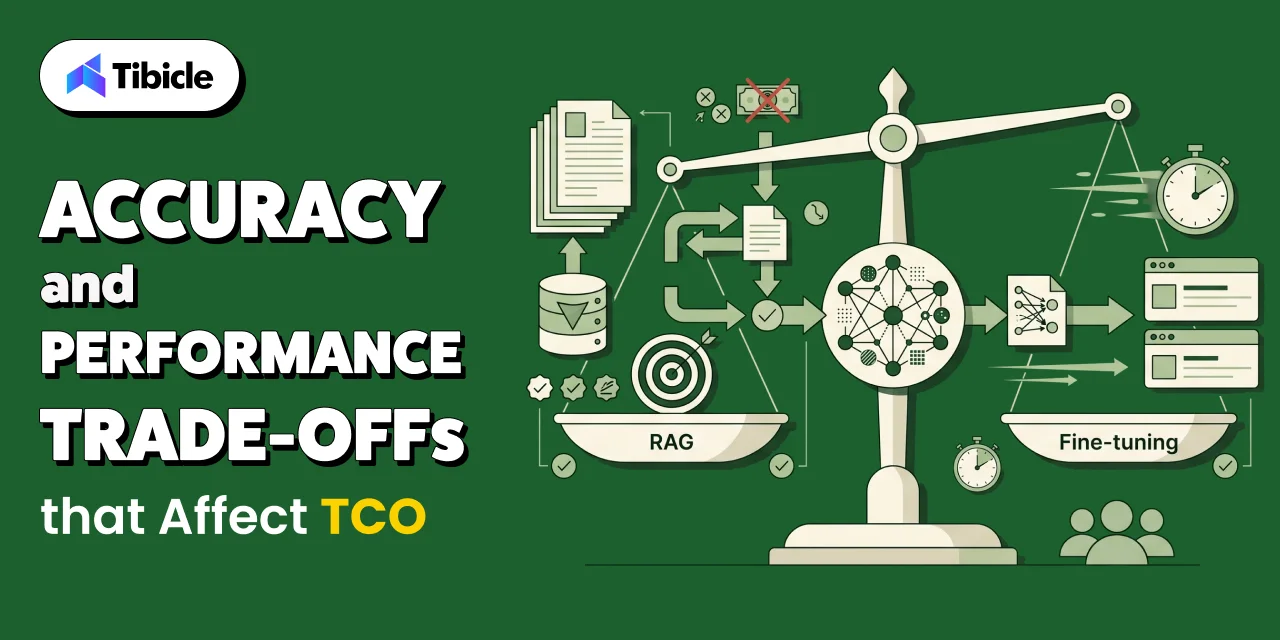
Cost alone does not decide this comparison, because the two approaches fail differently, and the cost of a wrong answer belongs in the TCO calculation.
Why RAG Typically Wins on Factual Accuracy
RAG grounds its answers in retrieved source documents, which gives it a natural advantage when facts change frequently or when a user needs to see where an answer came from. A fine-tuned model can only reflect what it saw during training, so anything that changed since the last fine-tuning cycle is invisible to it unless the request also includes retrieved context.
Why Fine-Tuning Wins on Latency and Output Consistency
Fine-tuning wins on latency and output consistency because there is no retrieval step to wait on and no risk of an irrelevant document changing the model’s tone or format mid-response. For applications with strict formatting requirements, such as generating structured reports or matching a specific brand voice, a fine-tuned model tends to hold that consistency more reliably than prompting alone.
RAFT: Combining Fine-Tuning and Retrieval
Retrieval Augmented Fine Tuning, or RAFT, is a training recipe from UC Berkeley researchers that fine-tunes a model on a mix of relevant and irrelevant retrieved documents, training it to ignore the irrelevant ones and cite the useful ones directly (Zhang et al., UC Berkeley). The paper reports consistent performance gains across PubMed, HotpotQA, and Gorilla, three domain-specific RAG benchmarks, which makes RAFT a practical middle path for teams that need both grounded facts and fine-tuned output behavior.
- Model the cost of being wrong, not just the cost of the API call, when weighing RAG’s accuracy advantage
- Treat fine-tuning as a tone and format tool first, a knowledge tool second
- Budget retrieval quality testing separately from model selection, since poor chunking can undo an otherwise sound RAG architecture
- Revisit the TCO comparison whenever a provider changes fine-tuning availability or pricing, not just once at project kickoff
A TCO Framework for Choosing Between Fine-Tuning and RAG
The deciding factor in most TCO comparisons is not raw cost, it is how often the underlying data changes, set against a market that is increasingly buying AI capability rather than building it.
When the Data Changes Frequently, RAG Usually Wins on TCO
If the knowledge base updates weekly or daily, retraining a fine-tuned model on that cadence is rarely affordable. RAG’s ability to pull from an updated index without a training run makes it the lower-TCO option whenever freshness matters more than output consistency.
When Fine-Tuning’s Upfront Cost Pays Off
Fine-tuning’s upfront cost pays off when the underlying knowledge is stable and the requirement is really about behavior, such as matching a specific tone, output format, or reasoning style across thousands of similar requests. That shift toward buying rather than building extends beyond the fine-tuning decision itself. Menlo Ventures’ 2025 State of Generative AI in the Enterprise report found the enterprise build-to-buy ratio moving from 47% built and 53% purchased in 2024 to 24% built and 76% purchased in 2025 (Menlo Ventures). That trend supports treating fine-tuning as a targeted, well-scoped investment rather than a default customization strategy.
Modeling Break-Even Between the Two Approaches
A break-even model needs a time horizon and a query volume estimate. Divide fine-tuning’s one-time training cost plus its ongoing inference premium, projected over that horizon, against RAG’s vector database and per-query costs over the same horizon and volume. The approach with the lower total at the chosen horizon wins on TCO, though the accuracy and latency trade-offs above should still weigh into the final call.
Common TCO Mistakes Enterprises Make
Most first-time comparisons between fine-tuning and RAG make one of three predictable errors.
Comparing Training Cost Against Per-Query Cost Without a Time Horizon
A one-time training cost and a per-query cost are not directly comparable numbers until a time horizon and volume estimate turn the per-query cost into a total. Comparing them as-is produces a number that looks meaningful and is not.
Ignoring the Fine-Tuned Inference Premium in the Ongoing Budget
Budgets that account for training cost but not the ongoing inference premium consistently underestimate fine-tuning’s real TCO, especially at high request volume.
Underbudgeting Retrieval Quality Work in a RAG Deployment
Teams frequently budget the vector database and the per-query cost and skip the ongoing labor of chunking review, re-ranking tuning, and retrieval evaluation, then wonder why a RAG system that scored well in testing performs worse in production six months later.
How Tibicle Helps Enterprises Choose Between Fine-Tuning and RAG
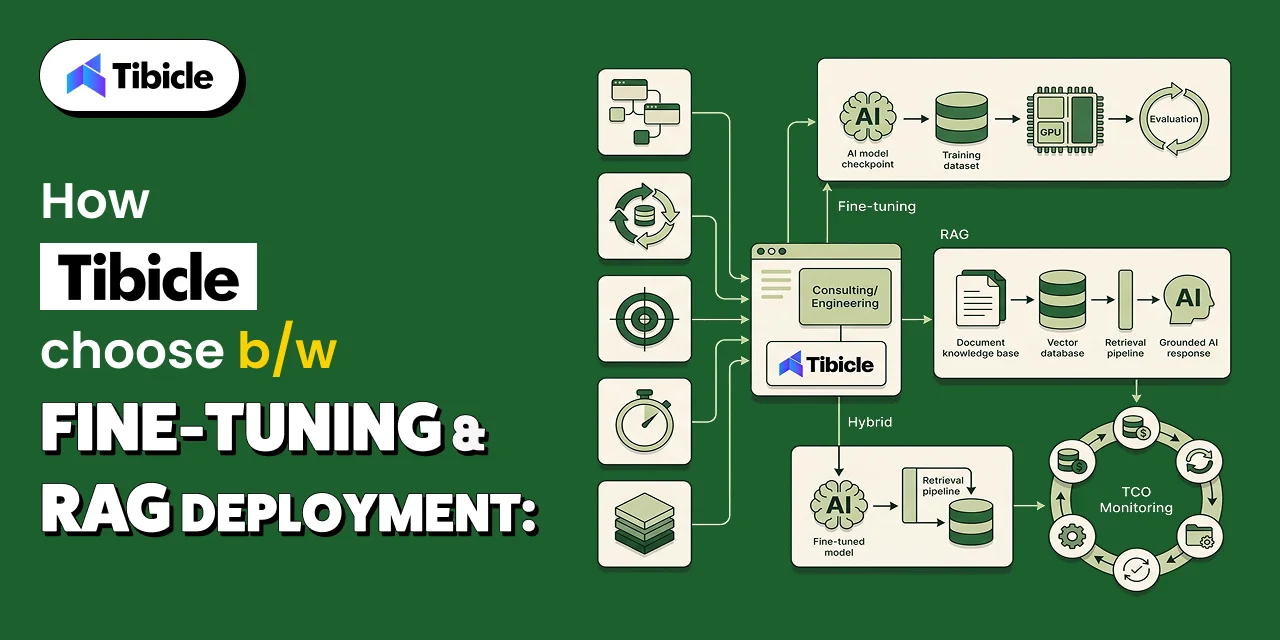
TCO Modeling Before Any Architecture Decision
Tibicle builds a TCO model specific to the request volume, data change frequency, and accuracy requirements of each project before recommending fine-tuning, RAG, or a hybrid approach, so the architecture decision follows the numbers instead of a default preference.
Implementation of Fine-Tuning, RAG, or a Hybrid Approach
Once the model points to an approach, Tibicle handles the build, whether that means a fine-tuning pipeline with proper dataset preparation and evaluation, a RAG system with a tested retrieval pipeline, or a RAFT-style hybrid that combines both.
Ongoing Cost Monitoring and Model Updates
Because both provider pricing and platform availability keep shifting, Tibicle reviews the TCO model on a set schedule after launch and flags when a provider change, such as OpenAI’s fine-tuning wind-down, affects the original cost assumptions.
Key Takeaways for Teams Budgeting Enterprise AI
Custom LLM fine-tuning services cost now needs to account for provider platform risk, not just training and inference pricing. RAG’s total cost of ownership sits in ongoing vector database and per-query costs, both of which are shifting fast in opposite directions. Fine-tuning wins on latency and output consistency, RAG wins on factual accuracy and freshness, and most enterprise systems end up needing both in some combination. A TCO comparison needs a time horizon: comparing a one-time training cost against a per-query cost without one produces a number that means nothing.
Book a call with Tibicle to model your TCO.
FAQ
What does custom LLM fine-tuning services cost typically include beyond the training run itself?
Beyond the training run, the real total includes dataset preparation, the ongoing inference premium on fine-tuned models, evaluation after each retraining cycle, and the labor cost of subject-matter experts reviewing training examples.
Is RAG cheaper than fine-tuning for an enterprise AI application?
It depends on data change frequency and query volume. RAG tends to win on TCO when the knowledge base updates often, while fine-tuning can be cheaper over time for stable knowledge at very high query volume, since it avoids a retrieval step on every call.
Does OpenAI winding down its fine-tuning API affect enterprises that already have a fine-tuned model?
Not immediately. Inference on existing fine-tuned models continues until the underlying base model is deprecated. The impact shows up at the next retraining cycle, when the organization needs to confirm it still qualifies to start a new fine-tuning job under OpenAI’s tightening eligibility window.
Can fine-tuning and RAG be combined in the same application?
Yes. RAFT, a training recipe from UC Berkeley researchers, fine-tunes a model to work with retrieved documents directly, and many production systems use a similar hybrid pattern to get both grounded facts and consistent output behavior.
How do we calculate the break-even point between fine-tuning and RAG?
Pick a time horizon and a query volume estimate, then compare fine-tuning’s training cost plus its ongoing inference premium over that horizon against RAG’s vector database and per-query costs over the same horizon and volume.
Does Tibicle help enterprises choose and implement between fine-tuning and RAG deployment?
Yes. Tibicle builds a TCO model specific to each project before recommending an architecture, then implements fine-tuning, RAG, or a hybrid approach and reviews the cost model on a set schedule after launch.
Schedule A Developer Interview And Get 15 Days Risk-Free Trial
Schedule a Call

Relevant Blog
Custom AI POS Software Development with Electron & IoT
Aditya Changlani

Migrate Web AI App to Electron Desktop via Electron
Aditya Changlani

Written by
Aditya Changlani
Business Development Executive
I’m Aditya Changlani, a Business Development Professional at Tibicle LLP, passionate about turning conversations into opportunities and ideas into impactful digital solutions. I work closely with businesses to understand their challenges, uncover growth opportunities, and connect them with the right technology across web, mobile, AI, and custom software development. For me, business development isn’t just about making a sale, it’s about understanding people, solving the right problems, building genuine relationships, and creating partnerships that deliver lasting value.
Related posts
Custom AI POS Software Development with Electron & IoT
What This Guide Covers Who this is for: CTOs, retail technology leaders, and product owners at retail chains, grocery and convenience operators, and POS vendors evaluating custom AI POS software development for an AI-enabled checkout or a terminal refresh. Search intent: Understand how custom AI POS software development works, including Electron architecture, IoT integration […]
06 Oct 2026 | Aditya Changlani
Migrate Web AI App to Electron Desktop via Electron
What This Guide Covers Who this is for CTOs, VP Engineering, and technical founders at companies running an AI feature inside a web app who are weighing whether to migrate their web AI app to Electron desktop. This applies most directly to teams where the AI workflow is central to the product, not a side […]
02 Oct 2026 | Aditya Changlani
Enterprise AI Application Development Services: Building Custom LLM Solutions for B2B SaaS
What this Guide Covers Who this is for Product managers, CIOs, and engineering leaders at B2B SaaS companies evaluating custom AI features. Teams comparing build vs buy vs hybrid approaches for LLM integration. Companies that shipped AI pilots and need guidance on reaching production. Organizations ready to invest in enterprise ai application development services but […]
30 Sep 2026 | Dhairya Dadhania
Got an Idea? Get FREE Consultation
In our world, there's no such thing as having too many clients

Email
tea@tibicle.com

Phone
+91 9724922880