
GraphRAG Implementation Services

Sep 21, 2026

Read in 4 Minutes
Table of Contents
- Introduction
- Why Enterprise SaaS Teams Need GraphRAG Implementation Services, Not Just a Vector Database
- GraphRAG vs Vector-Only RAG: What the Research Actually Shows
- What GraphRAG Implementation Actually Requires
- Full GraphRAG vs LazyGraphRAG vs Vector RAG: Choosing the Right Cost-Quality Tradeoff
- Common Reasons GraphRAG Projects Fail to Reach Production
- How Tibicle Delivers GraphRAG & Knowledge Graph Integration Services
- Conclusion
- Frequently Asked Questions
Who this is for: Engineering leads and product owners at enterprise SaaS companies evaluating GraphRAG implementation services for a knowledge base or retrieval system that vector search alone is not answering well.
Search intent: Commercial evaluation with a technical backbone. The reader has moved past “what is GraphRAG” and wants to know when a knowledge graph actually beats vector search, what implementation requires, and how the cost tradeoffs compare.
What you will walk away with: What the original GraphRAG research and follow-up studies actually show about graph versus vector retrieval, what a GraphRAG implementation requires, a cost-quality comparison across full GraphRAG, LazyGraphRAG, and vector RAG, and how Tibicle structures GraphRAG and knowledge graph integration services for enterprise SaaS.
Introduction
GraphRAG implementation services exist because vector search alone breaks down on one common question type. Some questions need an answer that pulls together an entire dataset. A single matching passage cannot answer them. Gartner names retrieval-augmented generation a cornerstone of enterprise GenAI deployment. Gartner tells organizations to evaluate vector search and graph technologies together when building RAG on existing data platforms. That pairing is the accurate framing, not a replacement.
A knowledge graph encodes explicit relationships between entities. Vector search finds semantically similar text instead. Enterprise SaaS products run into this gap constantly. Take two examples: “what are the main themes across our support tickets” and “how does this customer’s usage connect to their contract terms.”
Both need relationship reasoning, not similarity matching. This guide covers what the research shows about GraphRAG versus vector-only retrieval, and what a real implementation requires. It also covers the cost tradeoffs across GraphRAG variants, and how Tibicle structures these services for enterprise SaaS products.
Why Enterprise SaaS Teams Need GraphRAG Implementation Services, Not Just a Vector Database
From Similarity Search to Relationship-Aware Retrieval
A vector database finds text chunks that resemble the query. It has no sense of how those chunks relate to each other. That gap is fine for a direct factual lookup. It becomes a real limitation once a question spans the whole dataset. GraphRAG implementation services address this gap directly. The pipeline extracts entities and relationships from the source data. It organizes them into a queryable graph structure. A retrieval system can then reason across connections that a similarity score alone cannot see.
The Market and Priority Behind This Shift
The infrastructure behind this shift is scaling fast. Grand View Research values the vector database market at $1.66 billion in 2023. The firm projects it will reach $7.34 billion by 2030, a 23.7% compound annual growth rate. Gartner’s own guidance to enterprises building GenAI applications is explicit. Prioritize RAG technologies, including vector search, graph, and chunking, together. Do not treat them as competing choices. GraphRAG implementation services sit at exactly that intersection.
GraphRAG vs Vector-Only RAG: What the Research Actually Shows
Where GraphRAG Wins: Global and Multi-Hop Questions
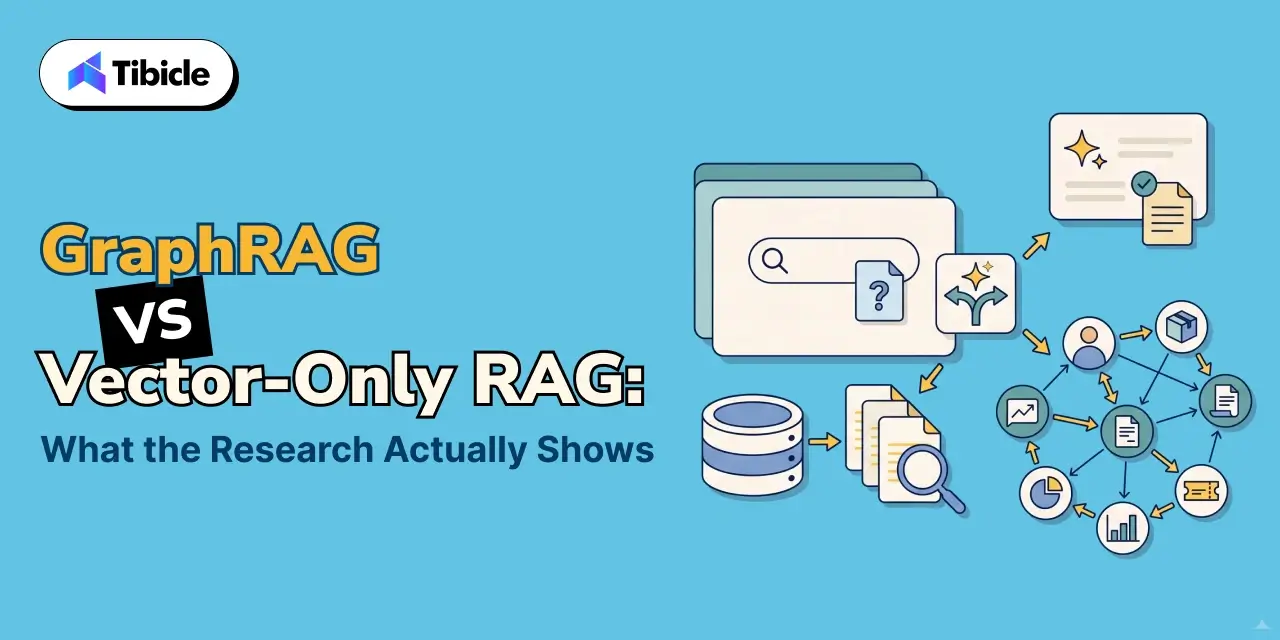
Microsoft’s own research team introduced GraphRAG. The team found that graph-based retrieval using community summaries beat naive vector RAG on comprehensiveness and diversity. The win rate ran roughly 70% to 80% on global, sense-making questions. These questions ask an AI system to synthesize themes across an entire dataset, not answer a single factual lookup. This is the specific class of question where a knowledge graph earns its complexity.
Where Vector Search Still Wins: Local, Factual Lookups
The same Microsoft research team is direct about the limits. Vector RAG remains the better tool for local queries, the “who,” “what,” “when,” and “where” questions. The answer to these sits inside a specific, findable text region. GraphRAG’s advantage shows up specifically on global queries that address the whole dataset instead. GraphRAG implementation services that skip this distinction end up graphing data that never needed it.
Why the Answer Is Usually Both, Not One or the Other
Most enterprise SaaS products field both kinds of questions. One query asks a specific factual lookup. The next asks a synthesis question across the whole knowledge base. A production system typically needs vector retrieval for the first case and graph-aware retrieval for the second. A routing layer should send each query to the right method. Forcing every query through one path wastes the other method’s strength.
What GraphRAG Implementation Actually Requires
Entity and Relationship Extraction From Your Data
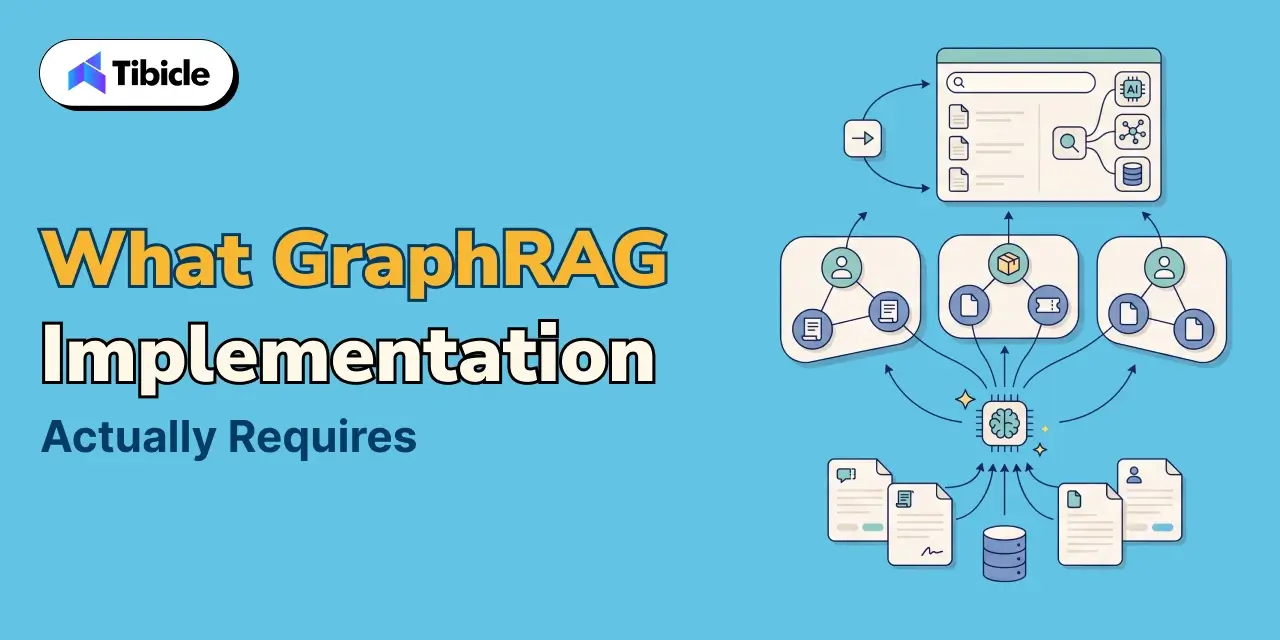
A GraphRAG pipeline starts with an LLM. The model extracts entities and the relationships between them from the source text. This step turns unstructured documents into a structured graph in the first place. The quality of this extraction step sets a ceiling on everything downstream.
Building the Community Hierarchy
Full GraphRAG groups related entities into hierarchical communities. It pre-generates summaries at each level. This structure lets the system answer a global query from a handful of summaries instead of the entire source corpus.
Integrating Graph Retrieval Into an Existing SaaS Product
The graph itself only earns its value once a team wires it into the product’s actual retrieval path, alongside the existing vector search. A routing layer needs to send local queries one way and global queries the other. Tibicle’s AI Development and Integration services cover this integration work directly. That includes teams that already run local model inference, a pattern covered in Tibicle’s guide on running local LLMs in Electron.
Full GraphRAG vs LazyGraphRAG vs Vector RAG: Choosing the Right Cost-Quality Tradeoff
Indexing cost is the practical constraint that decides which of these approaches actually fits a given dataset and budget.
| Approach | Indexing Cost | Best Fit |
| Vector RAG | Lowest; embeddings only | Local, factual queries with a findable answer in one region |
| LazyGraphRAG | Same as vector RAG, roughly 0.1% of full GraphRAG | Teams that want graph-quality global answers without upfront summarization cost |
| Full GraphRAG | Highest; LLM-generated entity, relationship, and community summaries | Datasets queried repeatedly for global, sense-making questions, where the graph pays for itself over many queries |
Microsoft’s own comparison found LazyGraphRAG’s data indexing costs identical to vector RAG. That cost runs roughly 0.1% of full GraphRAG’s cost. LazyGraphRAG still matches or beats full GraphRAG’s answer quality, at a fraction of the query cost. Enterprise SaaS teams often can’t tell whether their query volume justifies full GraphRAG’s upfront cost. For them, this middle path is often the right starting point.
Common Reasons GraphRAG Projects Fail to Reach Production
Gartner has found that at least 30% of generative AI projects never make it past proof of concept. The recurring causes: poor data quality, inadequate risk controls, escalating costs, and unclear business value. GraphRAG projects fail for a related, more specific set of reasons:
- The team graphed the entire dataset instead of scoping the graph to questions that actually need relationship reasoning
- Nobody validated entity extraction quality against a labeled sample before the team built the graph at scale
- No routing layer existed between local and global queries, so every question paid the cost of graph retrieval
- The team underestimated full GraphRAG’s indexing cost against the actual query volume the graph needed to justify
- The team measured success by whether the graph looked complete, not by whether retrieval quality actually improved for real user questions
How Tibicle Delivers GraphRAG & Knowledge Graph Integration Services
Data and Graph Architecture Scoping
Tibicle starts by identifying which parts of a SaaS product’s query volume are genuinely global and multi-hop. These are the questions that justify a graph. Local lookups, by contrast, are ones vector search already handles well. This scoping stage draws on Tibicle’s AI & Automation Consulting practice. It applies directly to internal knowledge bases through Tibicle’s Enterprise & Internal Tools work.
Build: Entity Extraction, Graph Construction, and Retrieval Integration
The build phase extracts entities and relationships, constructs the graph, and integrates graph-aware retrieval alongside existing vector search. A routing layer then sends each query down the right path.
Evaluation and Ongoing Tuning
After launch, Tibicle evaluates retrieval quality against real user queries, not just synthetic benchmarks. The team tunes the graph as the underlying data and query patterns evolve. Tibicle’s healthcare implementations apply this same evaluation discipline to clinical and research knowledge graphs, under its HealthTech industry work.
Conclusion
GraphRAG earns its place once a product’s questions genuinely need reasoning across relationships, not just similarity to a query. The right implementation then routes local and global questions to whichever retrieval method actually answers them well.
Evaluating GraphRAG or knowledge graph integration for your SaaS product? Talk to the Tibicle team.
Frequently Asked Questions
What do GraphRAG implementation services actually build, compared to a vector database?
A vector database retrieves text chunks by similarity alone. GraphRAG implementation services build a knowledge graph of entities and relationships extracted from your data. They then integrate graph-aware retrieval alongside vector search for questions that need reasoning across connections.
Does GraphRAG implementation services replace vector search entirely?
No. Research from Microsoft’s own GraphRAG team found vector search remains the better tool for local, factual queries. Graph-based retrieval wins specifically on global, sense-making questions that span an entire dataset.
How much more expensive is GraphRAG implementation services than standard vector RAG?
Full GraphRAG’s indexing cost runs significantly higher due to LLM-generated entity, relationship, and community summaries. LazyGraphRAG offers a middle path, with indexing costs matching vector RAG at roughly 0.1% of full GraphRAG’s cost.
What kind of questions actually benefit from a knowledge graph?
Global, multi-hop, or sense-making questions benefit most- the kind that require synthesizing information across many documents. Examples include identifying themes across a dataset or tracing a relationship between distant entities.
Why do GraphRAG implementation services projects fail to reach production?
Common causes include unvalidated entity extraction quality and no routing layer between local and global queries. Another frequent mistake: graphing an entire dataset instead of scoping it to questions that actually need relationship reasoning.
Does Tibicle offer GraphRAG implementation services and knowledge graph integration services for enterprise SaaS?
Yes. Tibicle builds GraphRAG and knowledge graph integration services for enterprise SaaS products. That includes data scoping, entity extraction, graph construction, retrieval integration, and ongoing evaluation.
Schedule A Developer Interview And Get 15 Days Risk-Free Trial
Schedule a Call

Relevant Blog
Enterprise AI Automation Development Agency
Arjun Shinojiya

Legacy Application AI Modernization Services
Arjun Shinojiya
Custom Computer Vision Software Development Company
Arjun Shinojiya
Written by
Recent Blogs
GraphRAG Implementation Services
Who this is for: Engineering leads and product owners at enterprise SaaS companies evaluating GraphRAG implementation services for a knowledge base or retrieval system that vector search alone is not answering well. Search intent: Commercial evaluation with a technical backbone. The reader has moved past “what is GraphRAG” and wants to know when a knowledge […]
Enterprise AI Automation Development Agency
Who this is for: Operations leads, CTOs, and process owners evaluating an enterprise AI automation development agency for a full business process rather than a single bolted-on bot. Search intent: Commercial evaluation with a technical backbone. The reader has moved past “what is workflow automation” and wants to know why point-solution RPA plateaus, what end-to-end […]
Legacy Application AI Modernization Services
Who this is for: Engineering leads, CTOs, and IT decision-makers responsible for a legacy web or desktop application who are evaluating AI modernization services for legacy applications rather than a full ground-up rebuild. Search intent: Commercial evaluation with a technical backbone. The reader has moved past “what is legacy modernization” and wants to know where […]
Got an Idea? Get FREE Consultation
In our world, there's no such thing as having too many clients

